1endpoint
A unified AI API gateway offering transparent, usage-based token pricing for high-volume workloads with automatic prompt caching across multiple models.
At a Glance
Engagement
Available On
Listed Sep 2026
About 1endpoint
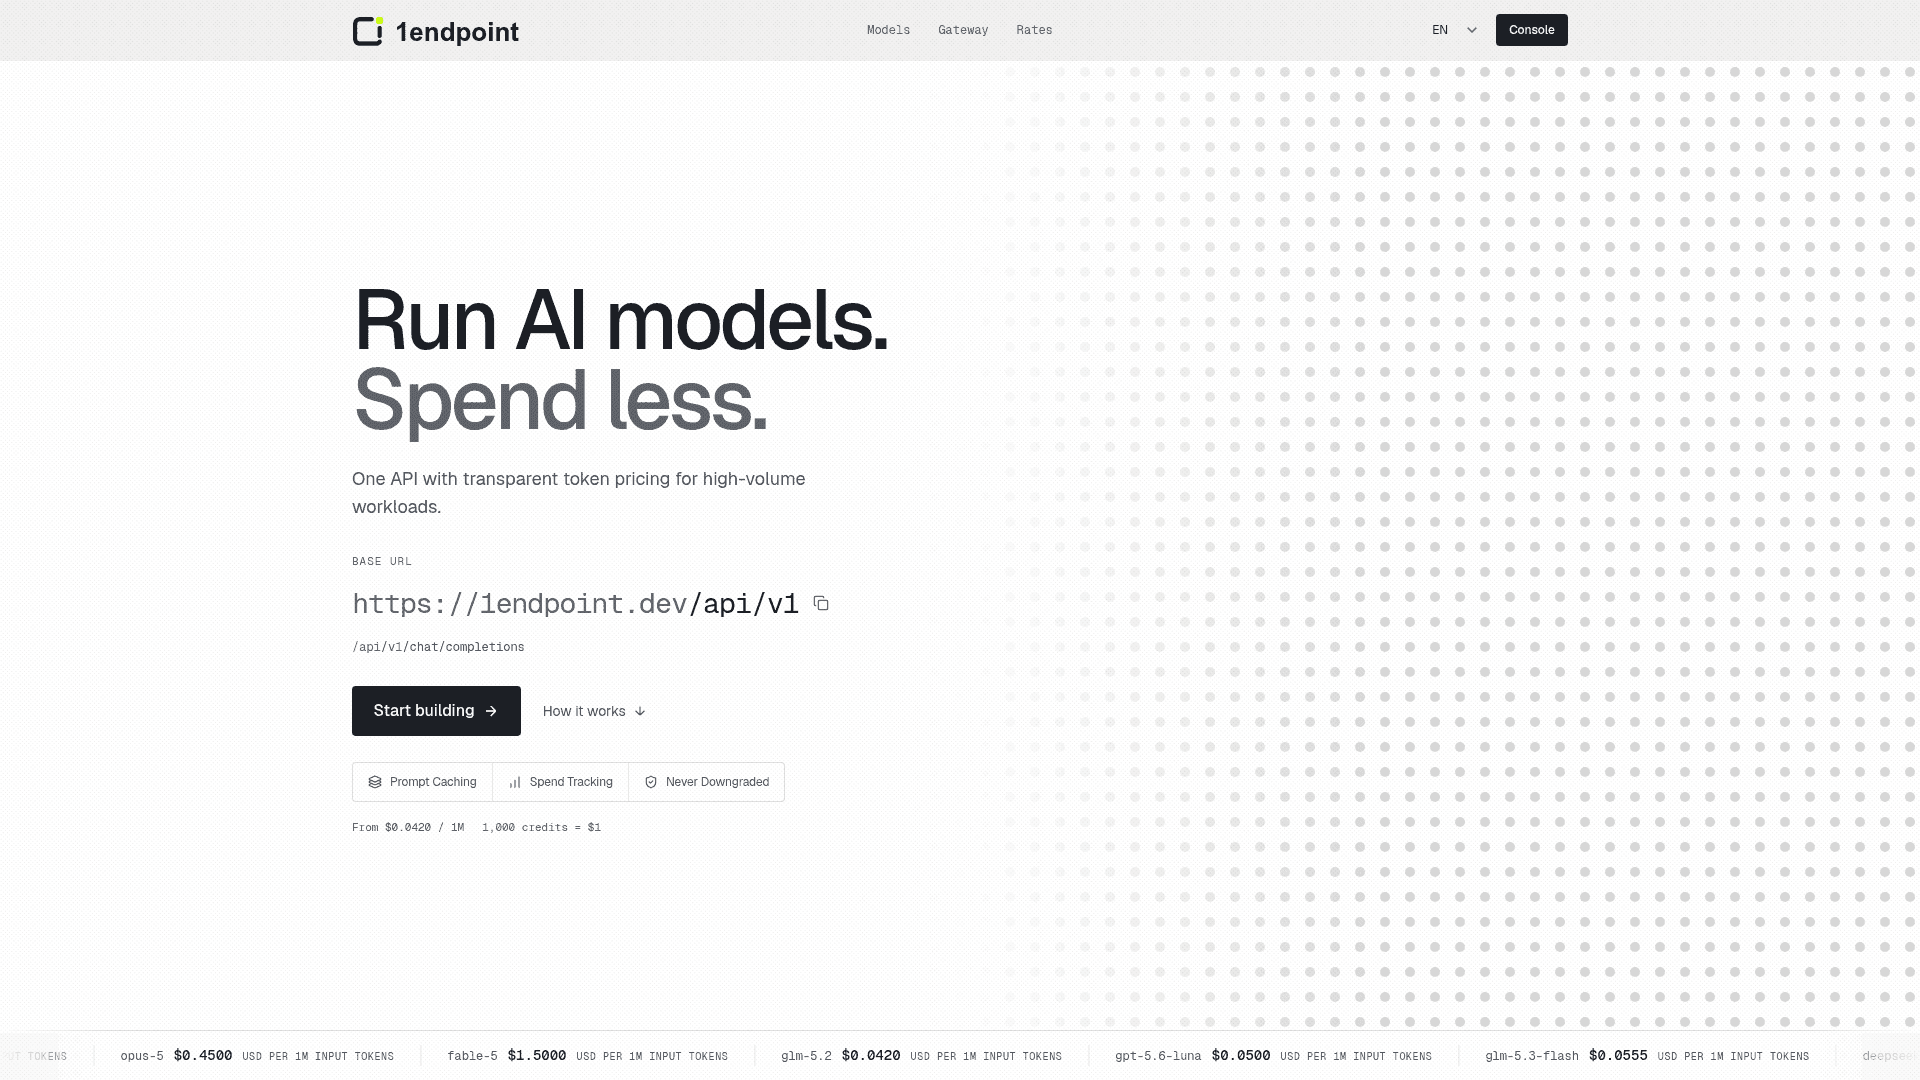
1endpoint is a unified AI API gateway that routes requests to multiple large language models through a single base URL, with transparent per-token pricing and automatic prompt caching. It is built for high-volume workloads where cost control matters, and it is powered by Enfyra. The service is OpenAI-compatible by design, meaning developers can switch to it by changing only the base URL in their existing application.
What It Is
1endpoint is an AI model gateway that aggregates access to a catalog of LLMs — including models from GLM, GPT, DeepSeek, Gemini, Qwen, Kimi, Claude (Sonnet/Opus), Grok, and others — under one API endpoint. It is positioned as a cost-reduction layer for developers and teams running high token volumes, with pricing that separates input, cached input, and output rates rather than blending them into a single opaque platform fee.
How the Gateway Works
The gateway exposes three request formats that mirror the major provider APIs:
- Chat Completions —
POST /chat/completions - Responses —
POST /responses - Messages —
POST /messages
The base URL is https://1endpoint.dev/api/v1. Because the request shape is unchanged from what OpenAI-compatible clients already send, integration requires only a base URL swap and a model ID change.
Prompt Caching and Cost Mechanics
The site's rate anatomy section illustrates how caching affects cost in multi-turn conversations. Because each message in a conversation resends all prior context, later messages would be expensive without caching. According to the site, a cache hit is billed at 5× less than a cache miss per model, and caching is applied automatically. The site's own example shows message 12 of a conversation costing $1.41 per 1,000 requests versus $5.17 without cache — a significant reduction for long conversations. Cache ratios differ per model.
Model Catalog
The site lists 16+ models at launch, spanning a wide range of price points:
- Budget tier: GLM 5.2, GPT 5.6 Luna, GLM 5.3 Flash, DeepSeek V4 Flash
- Mid tier: MiniMax M3, GPT 5.6 Terra, GLM 5.3, Gemini 3.7 Flash, Qwen3, Kimi K3
- Higher capability: DeepSeek V4 Pro, GPT 5.6 Sol, Sonnet 5, Grok 4.6, Opus 5, Fable 5
Input, cached input, and output are priced independently per model. The site states no blended platform fee is hidden in the rate.
Spend Tracking and Console
The console at console.1endpoint.dev provides API key management, documentation, and spend tracking. The site also offers a referral program where referring users earn 10% in credits when a referred user tops up. Billing is usage-based with a credit system (1,000 credits = $1).
Current Status
The site reports 730.8M tokens routed and 5,657 API requests in the last 24 hours as live counters, indicating an active production service as of 2026. The copyright footer reads © 2026 1endpoint, and the service is powered by Enfyra.
Community Discussions
Be the first to start a conversation about 1endpoint
Share your experience with 1endpoint, ask questions, or help others learn from your insights.
Pricing
Usage-Based
Pay only for what you use. Usage-based pricing with 1,000 credits = $1. Input starts at $0.0420 per 1M tokens with automatic prompt caching applied per model.
- Access to 16+ LLM models
- Automatic prompt caching
- Spend tracking
- API key management
- Chat Completions, Responses, and Messages endpoints
- Never downgraded
- Referral rewards (10% credits)
Capabilities
Key Features
- Unified API gateway for multiple LLMs
- Automatic prompt caching with per-model cache rates
- Transparent per-token pricing (input, cached input, output priced separately)
- OpenAI-compatible request formats (Chat Completions, Responses, Messages)
- Spend tracking via console
- API key management
- Referral rewards program (10% credits on referrals)
- 16+ model catalog including GLM, GPT, DeepSeek, Gemini, Qwen, Kimi, Claude, Grok
- Usage-based billing (1,000 credits = $1)
- Never downgraded guarantee