EveryDev.ai
Subscribe
Home
Tools

5,118+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2616
  • Coding1923
  • Infrastructure904
  • Projects719
  • Research646
  • MCP613
  • Analytics497
  • Marketing497
  • Design422
  • Testing411
  • Data378
  • Security329
  • Integration259
  • Communication250
  • Prompts247
  • Extensions219
  • Commerce171
  • Voice171
  • DevOps168
  • Web123
  • Learning114
  • Finance35
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. AgencyBench
    AgencyBench icon

    AgencyBench

    Academic Research

    Open-source benchmark that evaluates autonomous LLM agents on long-horizon, real-world tasks with automated rubric-based scoring.

    Visit Website

    At a Glance

    Pricing
    Open Source

    AgencyBench benchmark code, tasks and evaluation scripts released under the MIT License.

    Engagement

    Available On

    Web
    API
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    Academic ResearchAgent FrameworksLLM Evaluations

    Alternatives

    VitaBenchTerminal-Bench-ScienceEnterpriseRAG-Bench
    Developer
    SII - Generative Artificial Intelligence Research Lab (GAIR)GAIR is part of SII, focusing on Generative Artificial Intel…

    Listed Oct 2026

    About AgencyBench

    AgencyBench is a benchmark from GAIR-NLP (SII) for evaluating LLM-based autonomous agents on long-horizon, real-world workflows. The V2 release contains 138 tasks across 32 scenarios and 6 agentic capabilities: Game, Frontend, Backend, Code, Research and MCP. It is released under the MIT license, with a project website, a paper on arXiv and a dataset on Hugging Face.

    What It Is

    AgencyBench is a set of scenario folders, each with a task specification (subtasks, deliverables, rubrics), a configuration file and an evaluation script. The README says scenarios require an average of about 90 tool calls, 1 million tokens and hours of execution. Examples include building a C++ chat app, a browser Sudoku game, a 3D solar system landing page, a deep-research report with citations, and a GitHub MCP workflow that creates an issue, branch and pull request.

    How Automated Evaluation Works

    A user simulation agent gives iterative feedback to the agent under test. Game and Frontend scenarios run in a Docker-based remote VM sandbox. The evaluator opens the generated deliverables in a browser, performs human-like actions such as mouse clicks, keyboard input and command-line operations, and records screenshots and video. Scoring is rubric-based and combines rule-based judges, vision-based judges and LLM-as-judge where appropriate. An optional visualize flag lets you watch the evaluation run.

    Running a Scenario

    Setup uses a Python 3.11 conda environment and the repository's requirements file. For Game and Frontend scenarios, start the agent-infra sandbox Docker image and point the scenario .env at it. Fill in the .env with the scaffold, the evaluated model API and the evaluator model configuration, then run eval_task.py inside a scenario folder. Each run writes a model-named directory with intermediate artifacts and a final meta_eval.json holding the evaluation details and score.

    Leaderboard and Results

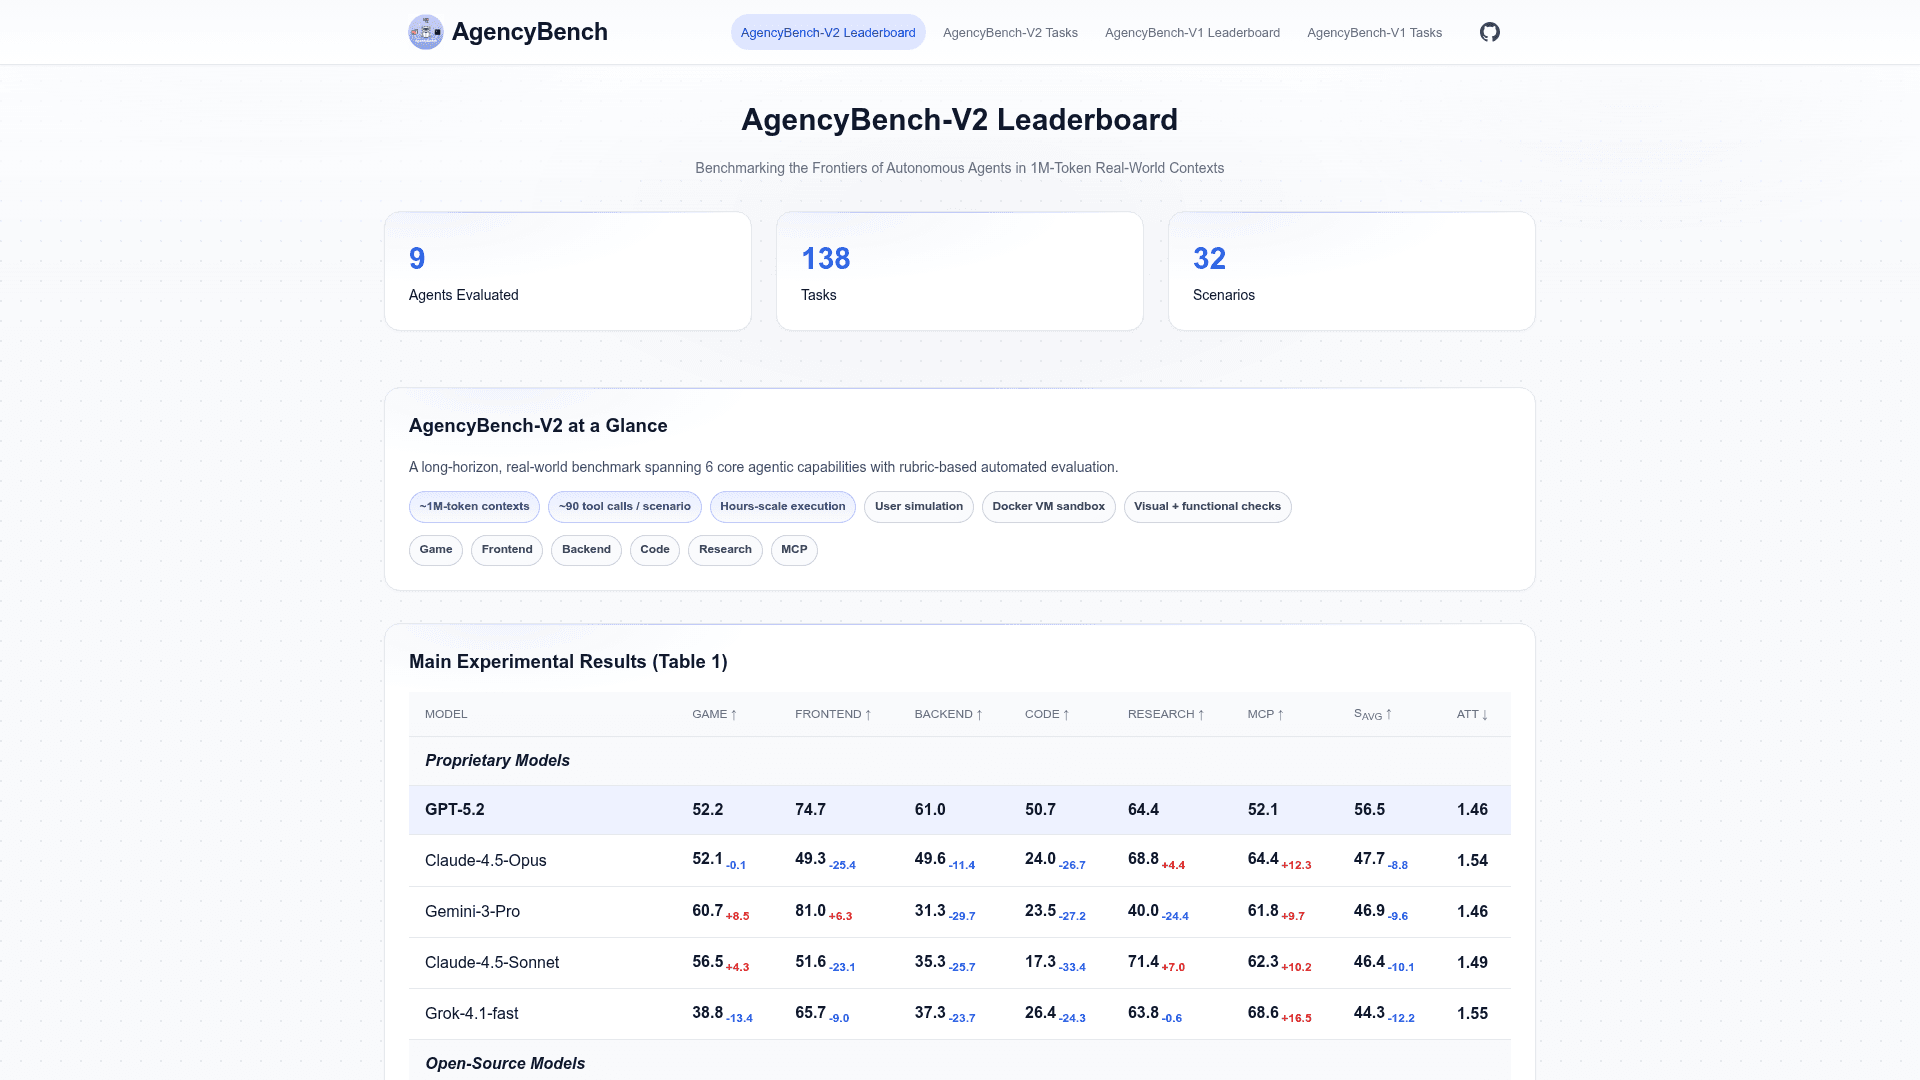
    The project website hosts V2 and V1 leaderboards and task pages. The V2 leaderboard lists 9 evaluated agents with per-capability scores, an average score (Savg) and average attempts per task (Att). The authors report that closed-source models outperform open-source models (48.4% vs 32.1%). They also analyze resource efficiency, feedback-driven self-correction and tool-use preferences. The earlier V1 release has 10 tasks.
    AgencyBench - 1

    Community Discussions

    Be the first to start a conversation about AgencyBench

    Share your experience with AgencyBench, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    AgencyBench benchmark code, tasks and evaluation scripts released under the MIT License.

    • MIT License
    • Open-sourced AgencyBench-V2 with queries, rubrics, deliverables and evaluation scripts
    • Open-sourced AgencyBench-V1 with 10 tasks

    Capabilities

    Key Features

    • 138 tasks across 32 real-world long-horizon scenarios
    • Six capability areas: Game, Frontend, Backend, Code, Research, MCP
    • User simulation agent for iterative feedback
    • Docker VM sandbox for visual and functional evaluation
    • Rubric-based scoring with rule-based, vision-based and LLM judges
    • Optional visualization of the evaluation process
    • Per-run meta_eval.json score output
    • Public V1 and V2 leaderboards

    Integrations

    Docker
    Hugging Face
    GitHub MCP
    Conda
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate AgencyBench and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    SII - Generative Artificial Intelligence Research Lab (GAIR)

    GAIR is part of SII, focusing on Generative Artificial Intelligence Research, with joint effort from SJTU.

    Read more about SII - Generative Artificial Intelligence Research Lab (GAIR)
    WebsiteGitHub
    1 tool in directory

    Similar Tools

    VitaBench icon

    VitaBench

    An open-source benchmark for evaluating LLM agents on versatile interactive tasks grounded in real-world life-serving applications like food delivery, in-store consumption, and online travel.

    Terminal-Bench-Science icon

    Terminal-Bench-Science

    An open-source benchmark for evaluating AI agents on expert-curated research workflows across life, physical, earth, mathematical, and engineering sciences.

    EnterpriseRAG-Bench icon

    EnterpriseRAG-Bench

    An open-source benchmark dataset of 500,000+ enterprise documents and 500 questions for evaluating RAG systems on realistic company internal data.

    Browse all tools

    Related Topics

    Academic Research

    AI tools designed specifically for academic and scientific research.

    90 tools

    Agent Frameworks

    Tools and platforms for building and deploying custom AI agents.

    871 tools

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    206 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions