AIBrix
Kubernetes control plane for production LLM inference that routes requests, autoscales, and manages models, LoRA adapters, and KV cache.
At a Glance
Self-hosted AIBrix Kubernetes control plane for LLM inference, licensed under Apache License 2.0.
Engagement
Available On
Alternatives
Listed Nov 2026
About AIBrix
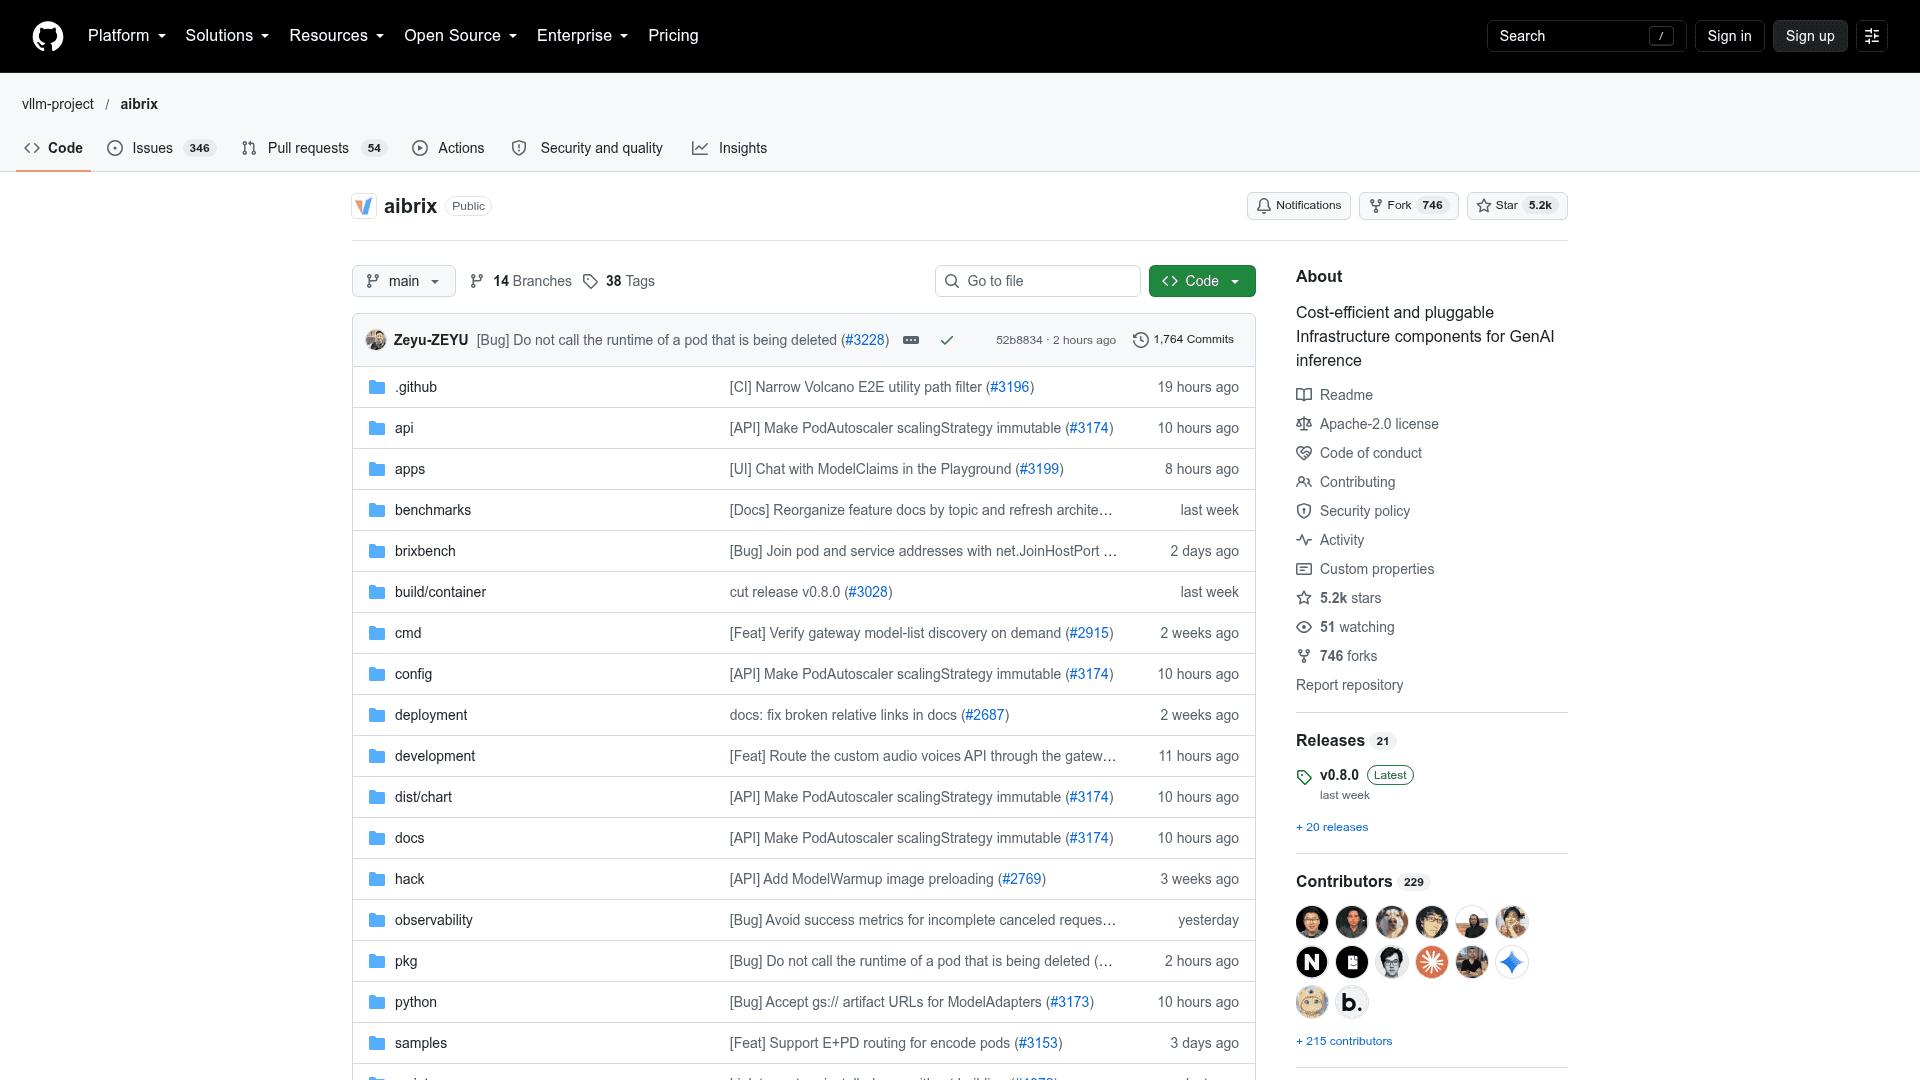
AIBrix is an open-source Kubernetes control plane for production LLM inference, hosted under the vllm-project GitHub organization. Users bring their own engine (vLLM, SGLang, or TensorRT-LLM), and AIBrix routes requests using live engine state, scales on inference metrics, and manages models, LoRA adapters, and KV cache. The latest release listed is v0.8.0.
What It Is
AIBrix sits between clients and inference engine pods on Kubernetes. Requests hit an OpenAI-compatible gateway and go straight to an engine pod, while Kubernetes controllers decide what should be running: model lifecycle, warmup, multi-node topology, autoscaling, and observability. It is aimed at teams running many models or replicas, mixing GPU types, or needing to hold cost and latency targets.
Routing and Serving Capabilities
The gateway picks a pod based on live engine state, including prefix-cache, load, and prefill/decode placement, with session affinity for agentic workloads. Multiple engines can be served behind one gateway. Many low-rank LoRA adapters can be packed onto shared base-model pods. Models are declared with ModelClaim, and ModelWarmup preloads images and weights so scale-up is faster. A runtime sidecar downloads weights, loads and unloads adapters, and normalizes engine metrics.
Scaling and Distributed Inference
Autoscaling acts on engine metrics such as queue depth, KV cache, and tokens. StormService runs multi-node and multi-role deployments, including prefill/decode. A distributed KV cache offloads cache and reuses it across engines. Heterogeneous GPU support, to mix GPU types while targeting cost and SLO, is marked experimental.
Setup Path
Installation applies release manifests with kubectl for dependencies (Envoy Gateway, KubeRay), CRDs, and core controllers into the current cluster context; KubeRay is only required for Ray-based multi-node inference. Helm steps and a quickstart with a base-model manifest and OpenAI-compatible curl commands are in the documentation. It can also be installed from a repository checkout using kustomize, with images tagged nightly.
Release History
The README lists releases from v0.1.0 through v0.8.0, with blog posts for most, and conference talks including KubeCon keynotes.
Community Discussions
Be the first to start a conversation about AIBrix
Share your experience with AIBrix, ask questions, or help others learn from your insights.
Pricing
Open Source
Self-hosted AIBrix Kubernetes control plane for LLM inference, licensed under Apache License 2.0.
- Apache License 2.0
- Gateway and routing with OpenAI-compatible API
- Multi-engine support (vLLM, SGLang, TensorRT-LLM)
- LoRA adapter management
- Autoscaling on engine metrics
Capabilities
Key Features
- OpenAI-compatible gateway with routing from live engine state
- Prefix-cache, load, and prefill/decode aware routing
- Session affinity for agentic workloads
- Multi-engine serving (vLLM, SGLang, TensorRT-LLM)
- Dynamic LoRA adapter packing on shared base-model pods
- ModelClaim and ModelWarmup model lifecycle management
- Autoscaling on engine metrics (queue depth, KV cache, tokens)
- Multi-node and multi-role distributed inference with StormService
- Distributed KV cache offloading and reuse
- Heterogeneous GPU support (experimental)
- Runtime sidecar for weight download, adapter loading, and metric normalization
Integrations
Demo Video