
AnySpeechRecognizer
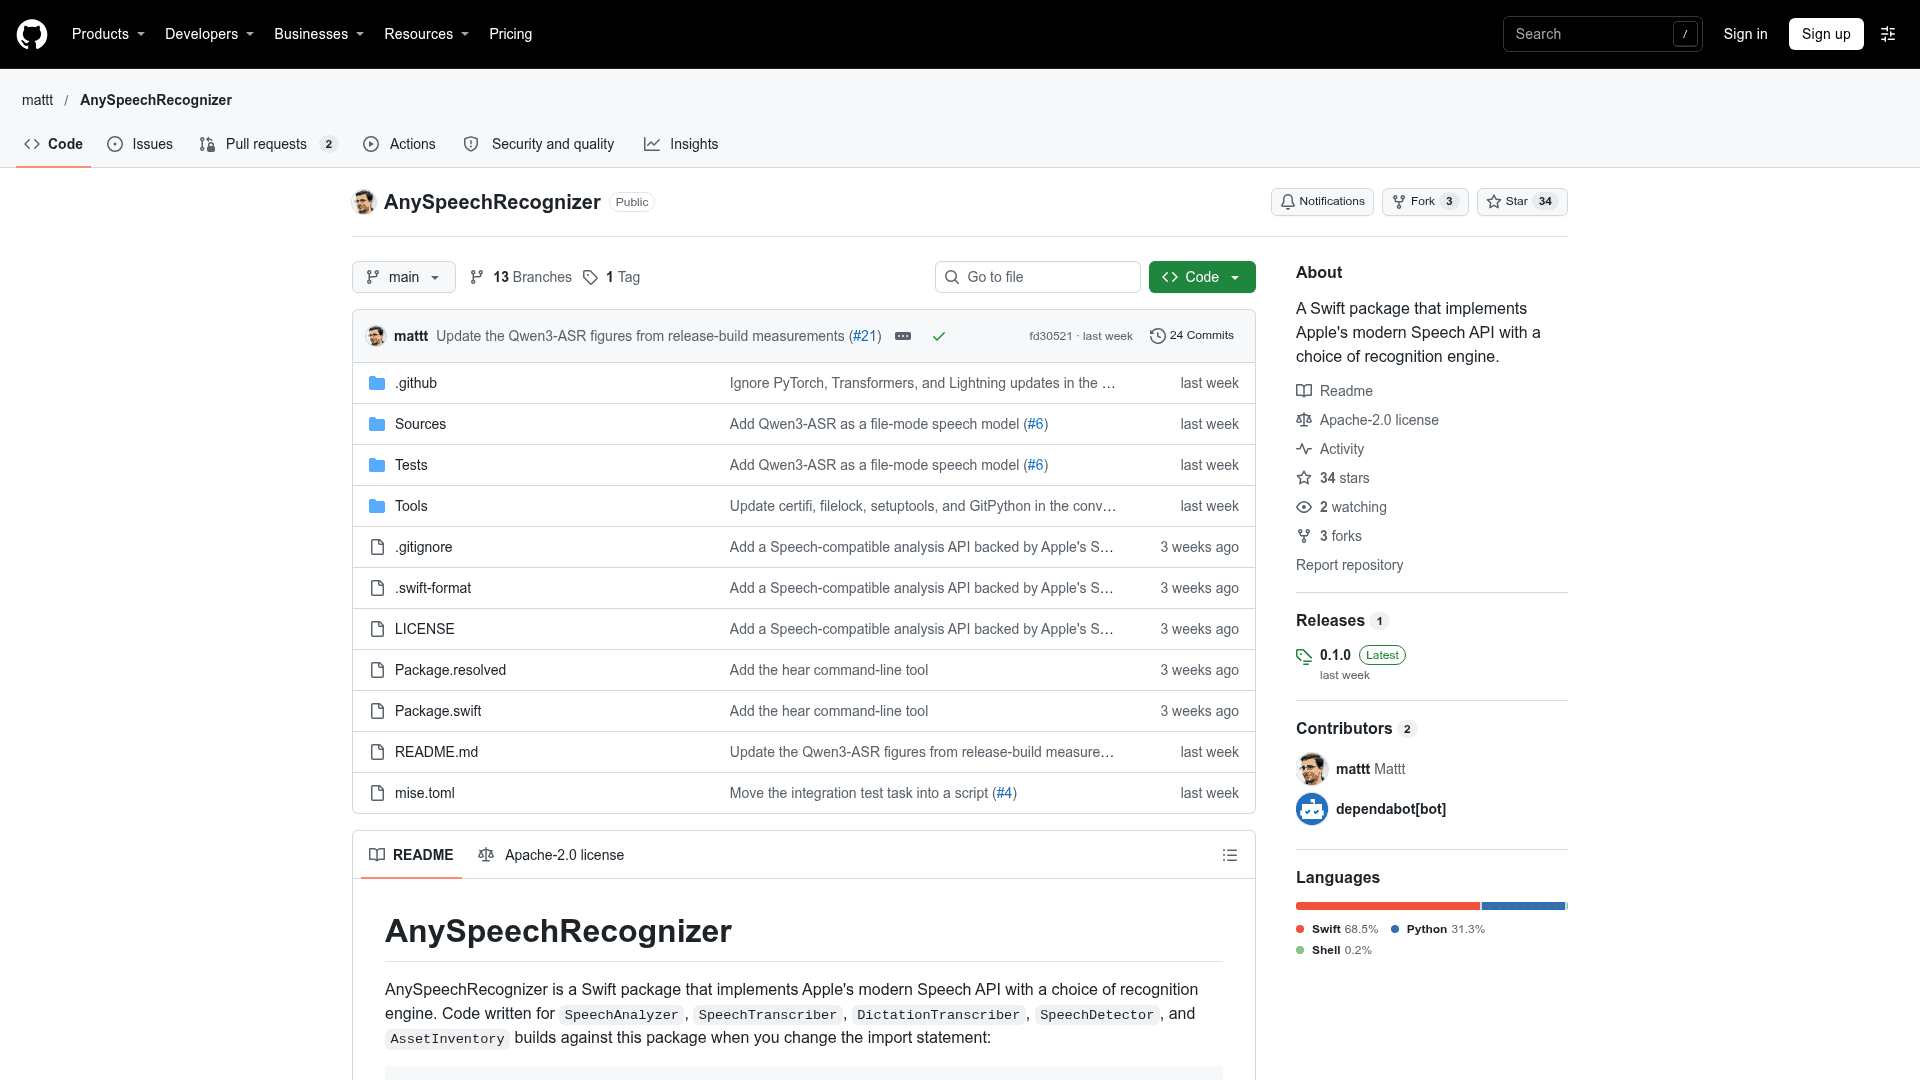
A Swift package that implements Apple's modern Speech API with a choice of recognition engine, including Parakeet and Qwen3-ASR on Core ML.
At a Glance
Swift package under the Apache License 2.0, free to use, modify and distribute. Model weights are downloaded at run time and carry their own licenses.
Engagement
Available On
Alternatives
Listed Nov 2026
About AnySpeechRecognizer
AnySpeechRecognizer is an open-source Swift package by mattt that implements Apple's modern Speech API (SpeechAnalyzer, SpeechTranscriber, DictationTranscriber, SpeechDetector, AssetInventory) with a choice of recognition engine. Code written for Apple's Speech framework builds against it by changing the import statement. The default backend is Apple's Speech framework, and the package adds its own Core ML runtimes for NVIDIA Parakeet and Alibaba Qwen3-ASR models.
What It Is
The package is a drop-in layer for on-device speech transcription on macOS 26 and iOS 26. You create a transcriber with a locale for Apple's engine, or pass a model such as ParakeetSpeechModel or QwenSpeechModel to use another engine. Asset installation, analysis, and results use the same API across backends. It does not implement the older SFSpeechRecognizer API and does not capture audio; you supply PCM buffers or files.
Backends and Models
- Apple: supports every preset and option of the Speech framework, plus DictationTranscriber and SpeechDetector.
- Parakeet: variants v3 (25 European languages), ultra, and unified (English only), with file and live input, volatile results, word timing and confidence.
- Qwen3-ASR: 0.6B and 1.7B models for file transcription covering 30 languages and 22 Chinese dialects, with segment-level results and no word timing.
Model files are downloaded from Hugging Face with pinned sizes and SHA-256 verification, or can be staged from a local directory for offline use.
Speaker Diarization and Tooling
SpeakerDiarizer runs NVIDIA's Streaming Sortformer on Core ML to identify who speaks when, for up to four speakers, on the same timeline as the transcriber. SpeakerTimeline attributes timed words to speakers. A custom provider protocol lets developers add their own recognition engine. A command-line tool, hear, can prepare assets, transcribe, diarize, and evaluate local files, reporting word and diarization error rates.
Requirements and Limitations
It needs Swift 6.2 or later, macOS 26 or iOS 26 or later, and Apple silicon for Parakeet and Sortformer. The README documents limitations such as unusable fast results on natural speech, Qwen3-ASR being file-only without word timing, and Parakeet on a physical iPhone not yet being tested.
Community Discussions
Be the first to start a conversation about AnySpeechRecognizer
Share your experience with AnySpeechRecognizer, ask questions, or help others learn from your insights.
Pricing
Open Source
Swift package under the Apache License 2.0, free to use, modify and distribute. Model weights are downloaded at run time and carry their own licenses.
- Apache License 2.0 core package
- Drop-in implementation of Apple's SpeechAnalyzer/SpeechTranscriber API
- Apple Speech and NVIDIA Parakeet TDT (Core ML) backends
- SpeakerDiarizer using NVIDIA Streaming Sortformer
- Model weights are not included and are downloaded at run time
Capabilities
Key Features
- Drop-in implementation of Apple's SpeechAnalyzer and SpeechTranscriber API
- Selectable recognition backends: Apple, Parakeet, Qwen3-ASR
- Live input with volatile and final results
- File transcription with word timing and confidence (Apple and Parakeet)
- Speaker diarization with NVIDIA Streaming Sortformer
- Pinned, verified model downloads via Hugging Face with offline staging
- Custom recognition provider protocol
- hear command-line tool for transcribe, diarize, and evaluate
- Dictation and speech detection via Apple backend