Bespoke Curator
Open-source Python library for building synthetic data pipelines and running bulk LLM inference for post-training and structured data extraction.
At a Glance
About Bespoke Curator
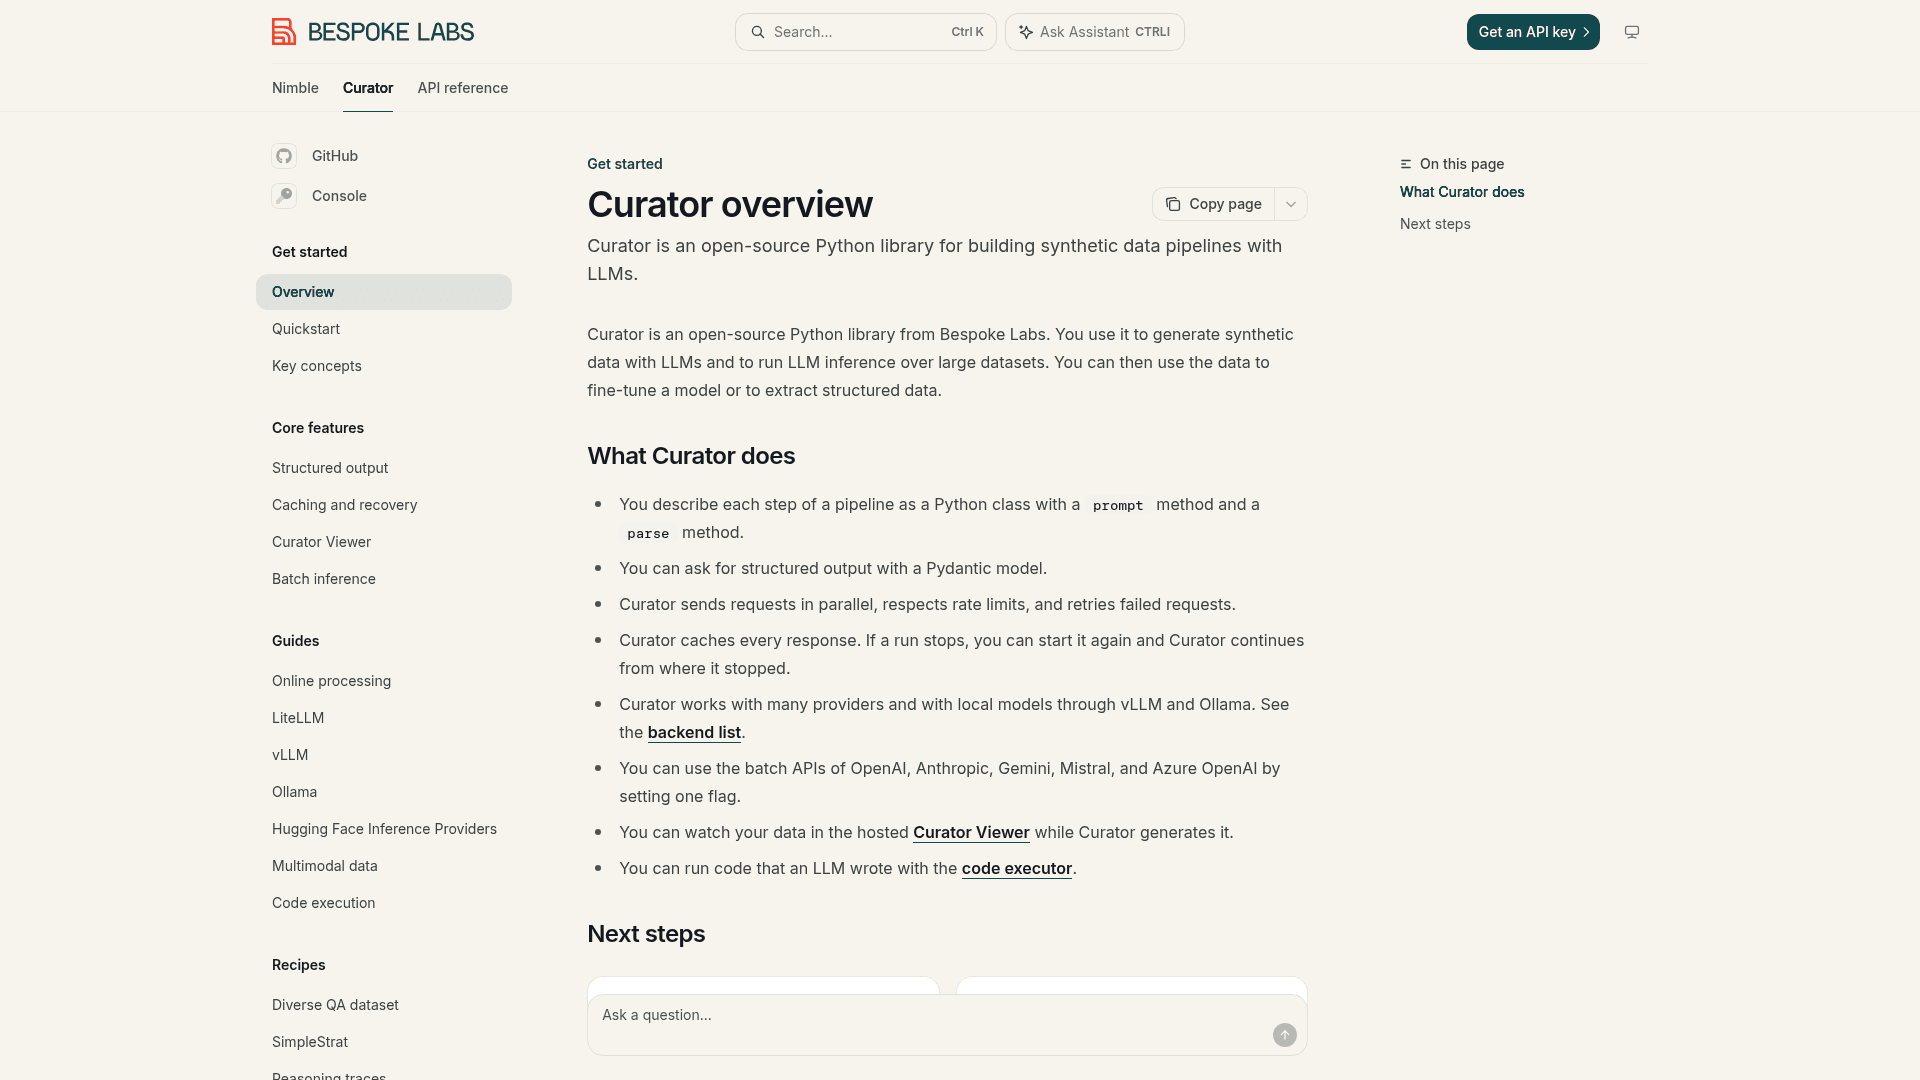
Curator is an open-source Python library from Bespoke Labs for generating synthetic data with LLMs and running LLM inference over large datasets. The resulting data can be used to fine-tune models or to extract structured data. It is released under the Apache 2.0 license, and the latest release listed on GitHub is v0.1.30.
What It Is
Curator is a data pipeline library for post-training workflows. Each pipeline step is a Python class that extends curator.LLM, with a prompt method that builds the request from an input row and a parse method that turns the model response into output rows. Structured output is supported through Pydantic models. Several steps can be chained, for example one block that generates topics and another that writes content for each topic.
How the Pipeline Runs
Curator sends requests in parallel, respects rate limits, and retries failed requests. Every response is cached, so an interrupted run resumes from where it stopped. Caching can be disabled or relocated with environment variables. Inputs can be Python lists or Hugging Face Datasets, and outputs can be converted to pandas or Hugging Face Datasets.
Backends and Batch Mode
It works with OpenAI and OpenAI-compatible endpoints, LiteLLM-supported providers such as Anthropic, Gemini and together.ai, kluster.ai, and local models through vLLM and Ollama. Setting batch=True switches to provider batch APIs (OpenAI, Anthropic, Gemini, Mistral, kluster.ai, and Azure OpenAI per the docs). The README notes that several providers offer about a 50% token discount in batch mode.
Viewer, Code Execution, and Fine-Tuning
A hosted Curator Viewer streams generated data as it is produced when CURATOR_VIEWER is enabled. Linking a Bespoke Labs API key keeps datasets private and enables dataset tracking and cost reports. A code executor runs LLM-generated code on local multiprocessing, Ray, Docker, or e2b backends. For fine-tuning, TinkerTrainer and FireworksTrainer take curated chat-format data to LoRA fine-tuned models. Examples include reasoning datasets, multimodal generation, function-calling data, RAFT, and sentiment analysis. The README states that minimal anonymized telemetry is collected, and it can be disabled.
Community Discussions
Be the first to start a conversation about Bespoke Curator
Share your experience with Bespoke Curator, ask questions, or help others learn from your insights.
Pricing
Open Source (Apache-2.0)
Curator is an open-source Python library released under the Apache License 2.0. LLM provider/inference costs are external.
- Apache License 2.0 (OSI-approved)
- Python library for synthetic data pipelines with LLMs
- Structured output with Pydantic
- Caching and recovery
- Batch inference via provider batch APIs
Capabilities
Key Features
- Prompt/parse class-based pipeline definition
- Structured output with Pydantic models
- Parallel requests with rate limiting and retries
- Response caching and run recovery
- Batch API support via a single flag
- Hosted Curator Viewer for monitoring generated data
- Code executor with multiprocessing, Ray, Docker and e2b backends
- Multimodal data generation
- Fine-tuning integrations with Tinker and Fireworks AI
- Support for vLLM, Ollama, LiteLLM and OpenAI-compatible backends