
ClawBench
Open-source benchmark that evaluates AI browser agents on everyday tasks across live websites using HTTP interception and an LLM judge.
At a Glance
ClawBench benchmark harness released under the Apache License 2.0; free to use, modify and distribute. Model/API inference costs are external.
Engagement
Available On
Alternatives
Listed Oct 2026
About ClawBench
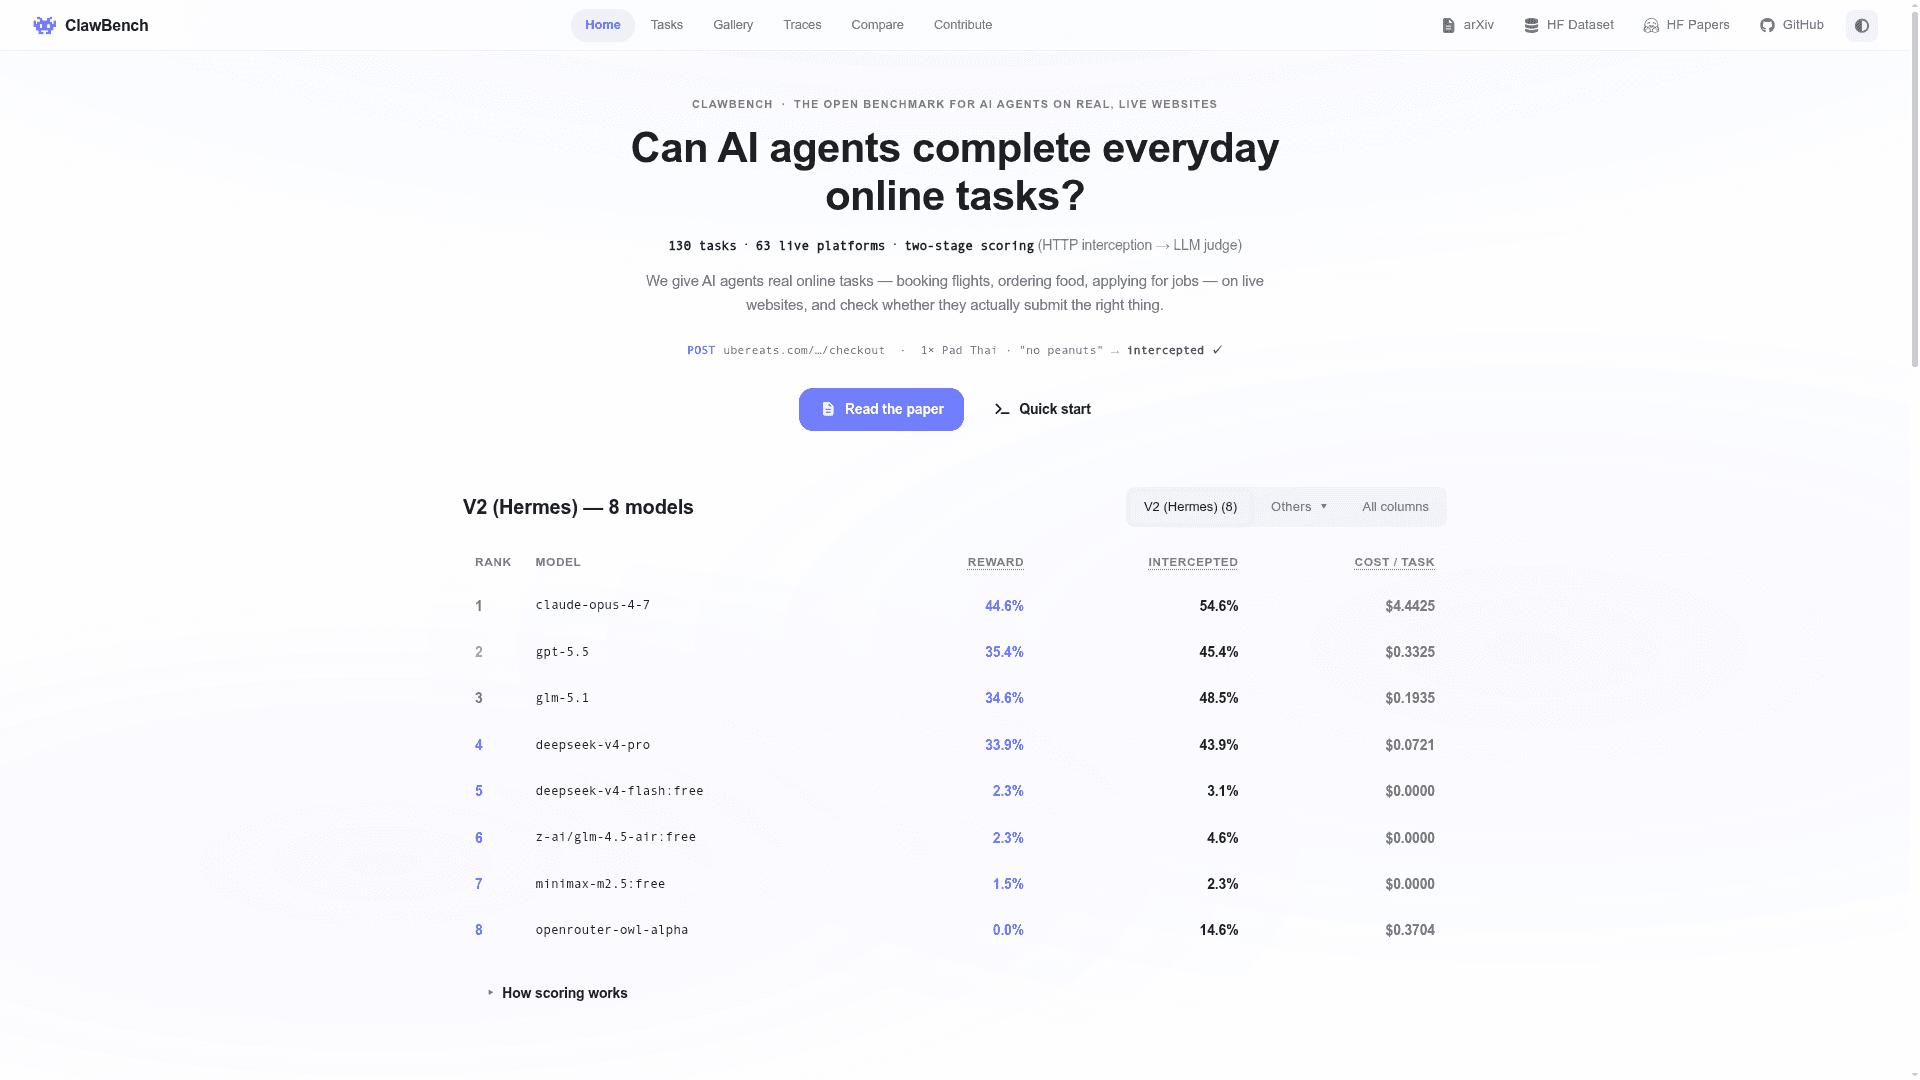
ClawBench is an open-source benchmark from TIGER-AI-Lab that gives AI browser agents everyday online tasks, such as ordering food, booking travel, and applying for jobs, on real live websites. It checks whether the agent submits the correct final request, and records five layers of evidence for each run. The project is released under Apache 2.0 and ships as the clawbench-eval Python package.
What It Is
ClawBench is an evaluation framework and dataset for browser agents. Each task is run in an isolated Docker or Podman container with Chromium, while the agent drives the live site. The V1 corpus has 152 tasks and V2 has 129, spanning 163 live websites across 15 life categories. The README notes that the paper reports 153 and 130 tasks, because two tasks were removed after publication.
How Scoring Works
Scoring has two stages. Stage 1 is deterministic: the harness intercepts the agent's final HTTP request before it fires and checks whether the URL and method match the task's schema. Stage 2 uses a judge model (deepseek-v4-pro by default) to check the intercepted payload against the instruction, under a lenient rubric or a strict one. The original V1 evaluation instead compares full agent trajectories with human reference trajectories. A public leaderboard breaks results down by corpus, harness, and rubric.
Traces and Datasets
Every run produces a bundle with a screen recording, actions, agent messages, HTTP requests, and the graded verdict. Task definitions and V1 and V2 trace datasets are published on Hugging Face. The project says the traces can be used to replay and audit runs, reproduce leaderboard scores, and build training data for SFT, DPO, or PRM.
Setup Path
Install with uv tool install clawbench-eval or from a source checkout, then launch the interactive TUI or run the non-interactive CLI commands (clawbench-run, clawbench-batch, clawbench-rescore). Requirements are Python 3.11+, uv, and Docker or Podman. Multiple harnesses and remote browser runtimes are supported, and a 20-task ClawBench-Lite subset is provided for quick runs.
Community Discussions
Be the first to start a conversation about ClawBench
Share your experience with ClawBench, ask questions, or help others learn from your insights.
Pricing
Open Source
ClawBench benchmark harness released under the Apache License 2.0; free to use, modify and distribute. Model/API inference costs are external.
- Apache License 2.0
- Install via pip: clawbench-eval
- 130 tasks on 63 live platforms (V2 corpus)
- Two-stage scoring (HTTP interception, LLM judge)
Capabilities
Key Features
- Benchmark of everyday online tasks on live websites (V1 152 tasks, V2 129 tasks)
- Two-stage scoring: HTTP request interception plus LLM judge
- Lenient and strict judge rubrics
- Five-layer run recording: video, actions, agent messages, HTTP requests, verdict
- Trace datasets on Hugging Face for replay, audit, and training
- Public leaderboard by corpus and harness
- ClawBench-Lite 20-task subset
- Interactive TUI and CLI (clawbench-run, clawbench-batch, clawbench-rescore)
- Multiple agent harnesses and remote browser runtimes
- Isolated Docker/Podman containers with Chromium