Context.dev
Web data API for AI agents to scrape, search, crawl, monitor, and extract brand and company data from the web.
At a Glance
About Context.dev
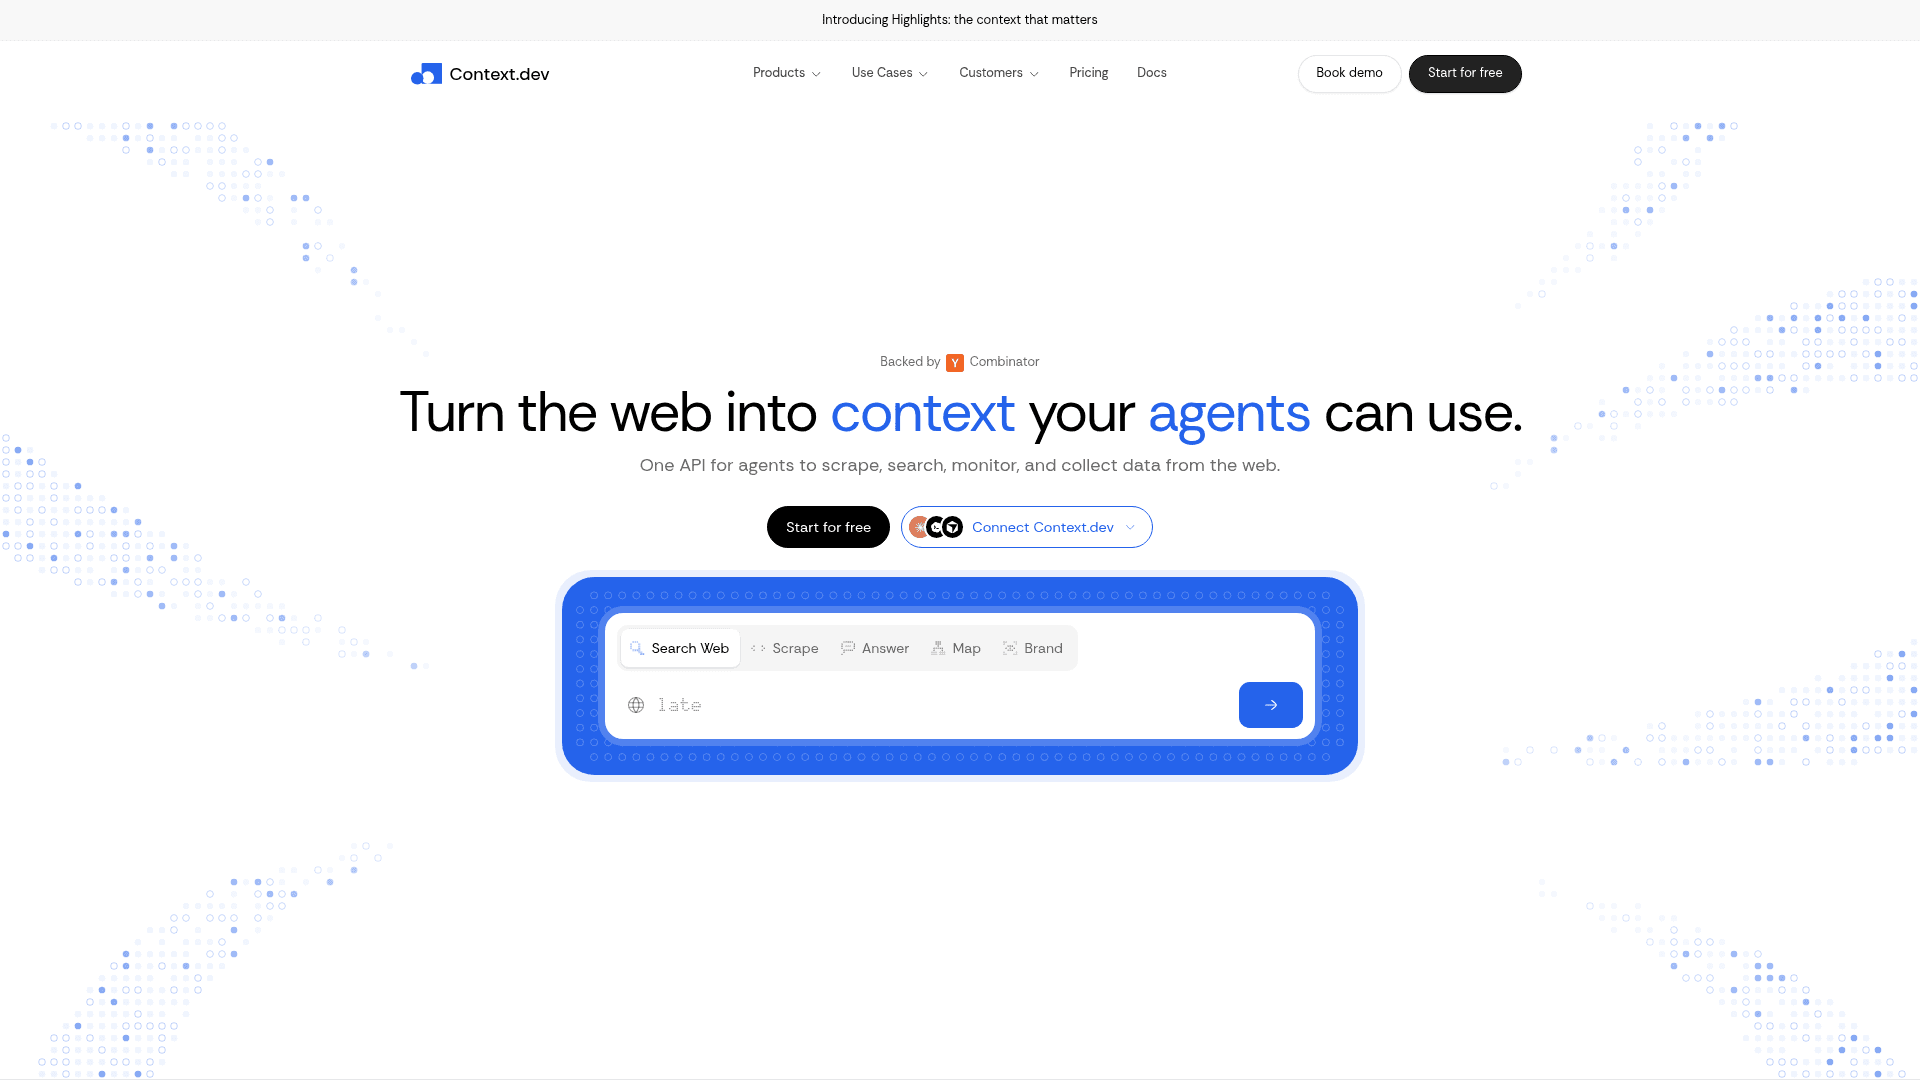
Context.dev is a web data infrastructure product for AI agents and applications. Through one API, developers can scrape pages and PDFs, search the web, map and crawl sites, run batch jobs, get sourced answers, monitor pages for changes, and retrieve company brand data. The company describes itself as backed by Y Combinator and based in San Francisco.
What It Is
Context.dev is an API platform that turns live web content into structured context for LLM apps, RAG pipelines, and agents. A developer sends a URL or a query and receives output such as Markdown, HTML, screenshots, images, structured JSON fields, ranked search results, or cited answers. Rendering, proxy escalation, and retries are handled on the service side, and the site states a 99.96% scrape success rate.
Core Capabilities
- Scrape: converts any page or PDF into Markdown, HTML, structured fields, images, or screenshots in one request.
- Search: searches the web or news and returns ranked results with page content.
- Crawl and Map: crawls up to 500 pages per call into Markdown, or discovers URLs across a domain.
- Batches: scrapes thousands of URLs or crawls whole sites as background jobs, with webhook or paginated result collection.
- Answers: takes a research question and returns structured JSON with source URLs.
- Monitors: watches pages on a schedule and sends webhook updates when content changes.
- Brand data: returns company profile, logos, colors, fonts, and style guides from a domain.
Developer Access
Official SDKs cover TypeScript, Python, Ruby, Go, and PHP, and the API is also available over REST with cURL. A CLI and a hosted MCP server at mcp.context.dev work with clients such as Claude Code, Codex, and Cursor. AI agents can register for API credentials programmatically through an auth.md guide, though email verification is still required.
Security and Data Handling
The site lists SOC 2 Type 2 compliance through a trust center and offers a zero data retention option that keeps inputs and outputs out of logs, caches, and storage.
Community Discussions
Be the first to start a conversation about Context.dev
Share your experience with Context.dev, ask questions, or help others learn from your insights.
Pricing
Free Tier
For exploring the APIs and testing your first ideas.
- 1,000 credits per month
- No overage
- 2 concurrent · 10 req/min
- Scrape 1,000 pages
- JS rendering & proxies included
Developer
For side projects, MVPs, and lightweight apps.
- 7,500 credits per month
- $2.20 per 1,000 credits overage
- 10 concurrent
- Scrape 7,500 pages
- 750 Answers in Fast mode
- 100 monitors
- 2 concurrent batches
- Email support
- Usage alerts
- Pull 100K logos
Pro
For production apps and AI agents powered by web data.
- 125,000 credits per month
- $1.80 per 1,000 credits overage
- 100 concurrent
- Scrape 125,000 pages
- 12,500 Answers in Fast mode
- 1,000 monitors
- 5 concurrent batches
- Email + Slack support
- Spend controls
- Pull 2.5M logos
Growth
For growing products that need more data, more often.
- 500,000 credits per month
- $1.40 per 1,000 credits overage
- 250 concurrent
- Scrape 500,000 pages
- 50,000 Answers in Fast mode
- 5,000 monitors
- 5 concurrent batches
- Priority support
- Pull 5M logos
Scale
For large datasets, bulk scraping, and continuous monitoring.
- 1,000,000 credits per month
- $1.00 per 1,000 credits overage
- 500 concurrent
- Scrape 1,000,000 pages
- 100,000 Answers in Fast mode
- 10,000 monitors
- 20 concurrent batches
- SSO / SAML
- Priority + Slack support
- Custom usage alerts
- Pull 10M logos
Enterprise
For teams with custom volume, security, and compliance requirements.
- 2M+ credits per month
- Volume discounts
- Custom rate and monitor limits
- SSO, SAML and SCIM provisioning
- 99.9% uptime SLA
- Annual invoicing, MSA and DPA
- Dedicated Slack channel
- Custom support and implementation help
Capabilities
Key Features
- Scrape pages and PDFs to Markdown, HTML, JSON, images, or screenshots
- Web and news search with page content
- Website crawl up to 500 pages per call
- URL mapping across domains
- Batch scraping and crawling
- Answers API with structured JSON and sources
- Scheduled page monitors with webhooks
- Brand data: logos, colors, fonts, style guides
- JavaScript rendering, proxy escalation, and retries included
- Zero data retention option
- Official SDKs, CLI, and MCP server