EveryDev.ai
Subscribe
Home
Tools

5,347+ AI tools

  • Featured
  • Gems
  • Trending
  • New
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2725
  • Coding2018
  • Infrastructure950
  • Projects752
  • Research670
  • MCP655
  • Analytics520
  • Marketing503
  • Design435
  • Testing432
  • Data395
  • Security362
  • Integration270
  • Prompts257
  • Communication255
  • Extensions227
  • Voice182
  • DevOps176
  • Commerce175
  • Web124
  • Learning114
  • Finance39
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. GenieX
    GenieX icon

    GenieX

    AI Infrastructure

    On-device Gen AI inference runtime for running LLMs and VLMs locally on Qualcomm Snapdragon NPU, GPU, or CPU.

    Visit Website

    At a Glance

    Pricing
    Open Source

    GenieX core runtime, SDK and CLI released under the BSD 3-Clause License (developer preview).

    Engagement

    Available On

    Windows
    Linux
    Android
    CLI
    SDK

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    AI InfrastructureAI Development LibrariesLocal Inference

    Alternatives

    ONNX RuntimeBaseRTuzu
    Developer
    Qualcomm Technologies, Inc.San Diego, CAEst. 1985

    Listed Nov 2026

    About GenieX

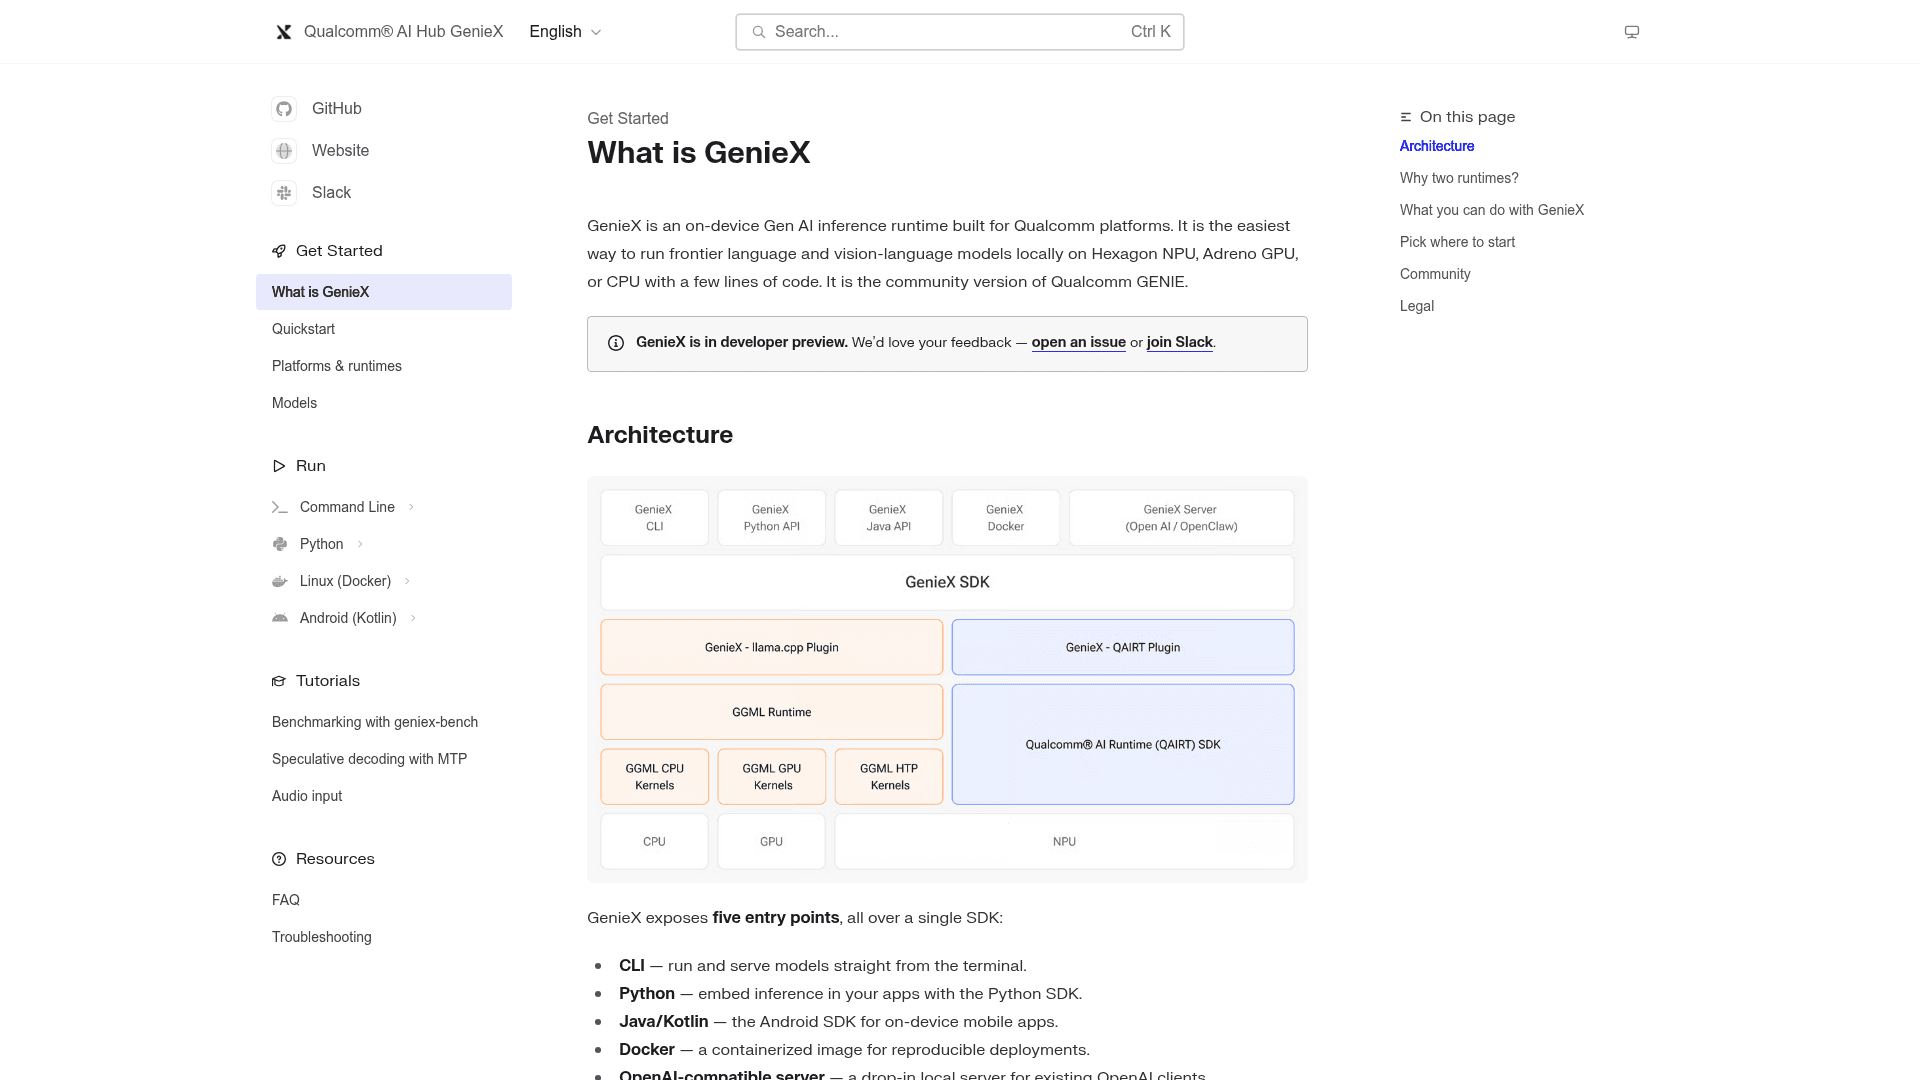
    GenieX is an on-device Gen AI inference runtime from Qualcomm for running language and vision-language models locally on Snapdragon devices. It targets the Hexagon NPU, Adreno GPU, or CPU and is exposed through a CLI, Python, Kotlin/Java, Docker, and an OpenAI-compatible server. It is the community version of Qualcomm GENIE and is currently in developer preview.

    What It Is

    GenieX is a local inference runtime built around a single C SDK. Users bring a GGUF model from Hugging Face, ModelScope, or Docker Hub, or use a pre-compiled bundle from Qualcomm AI Hub, and run it on Qualcomm hardware with a few lines of code. It supports both LLMs and VLMs.

    Two Runtimes, Two Goals

    The SDK dispatches to one of two runtimes. The llama.cpp runtime uses GGML kernels across CPU, GPU, and Hexagon HTP and covers almost any community GGUF model. The Qualcomm AI Engine Direct runtime (qairt) is NPU-only and runs per-chipset bundles from Qualcomm AI Hub, which the docs describe as the path for peak on-device performance. For llama.cpp, the README recommends the Q4_0 precision for the best Hexagon NPU support.

    Interfaces and Workflow

    • CLI: commands such as geniex infer <model> for chat, geniex pull, and geniex model list.
    • Python: pip install geniex, with an API that mirrors Hugging Face transformers (from_pretrained() then .generate()).
    • OpenAI-compatible server: geniex serve exposes a local /v1 endpoint for existing OpenAI clients.
    • Android: a Kotlin/Java SDK distributed as a Gradle dependency, with a sample chat app in a separate repository.
    • Docker: a container image that wraps the CLI.
    • C/C++: a single header that the other interfaces wrap.

    Supported Platforms

    GenieX runs only on Qualcomm Snapdragon: Windows ARM64 (Snapdragon X), Android (Snapdragon 8 Elite), and Linux ARM64 (Dragonwing IoT). Tutorials cover benchmarking with geniex-bench, speculative decoding with MTP, and audio input. The project is released under the BSD 3-Clause License.
    GenieX - 1

    Community Discussions

    Be the first to start a conversation about GenieX

    Share your experience with GenieX, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    GenieX core runtime, SDK and CLI released under the BSD 3-Clause License (developer preview).

    • BSD 3-Clause License (OSI-approved)
    • CLI, Python SDK, Android (Kotlin/Java) SDK, Docker image, C/C++ SDK
    • OpenAI-compatible local server
    • Runs on Qualcomm Snapdragon only (Windows ARM64, Android, Linux ARM64)
    • Developer preview status

    Capabilities

    Key Features

    • On-device LLM and VLM inference on Hexagon NPU, Adreno GPU, or CPU
    • Runs GGUF models from Hugging Face, ModelScope, and Docker Hub
    • Runs pre-compiled Qualcomm AI Hub bundles via Qualcomm AI Engine Direct
    • CLI for inference and model management
    • Python SDK mirroring Hugging Face transformers
    • OpenAI-compatible local server
    • Android Kotlin/Java SDK
    • Docker image for Linux ARM64
    • C SDK
    • Benchmarking with geniex-bench
    • Speculative decoding with MTP
    • Audio input

    Integrations

    llama.cpp
    Qualcomm AI Engine Direct
    Qualcomm AI Hub
    Hugging Face
    ModelScope
    Docker Hub
    OpenAI-compatible clients
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate GenieX and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    Qualcomm Technologies, Inc.

    At Qualcomm Technologies, Inc., we transform how the world connects, computes and communicates.

    Founded 1985
    San Diego, CA
    52,000 employees

    Used by

    GoPro (AI capabilities optimized with…
    Amazon SageMaker / AWS ecosystem users
    Golioth and Foundries.io edge-inference…
    Lantronix
    +1 more
    Read more about Qualcomm Technologies, Inc.
    WebsiteGitHub
    1 tool in directory

    Similar Tools

    ONNX Runtime icon

    ONNX Runtime

    A cross-platform, high-performance ML inference and training accelerator that speeds up AI models from PyTorch, TensorFlow, scikit-learn, and more across CPU, GPU, and NPU hardware.

    BaseRT icon

    BaseRT

    BaseRT is the fastest LLM inference runtime for Apple Silicon, offering up to 6.4x faster prefill than llama.cpp and 3.9x faster than MLX, with an OpenAI-compatible server and multi-language bindings.

    uzu icon

    uzu

    An open-source Rust inference engine from Mirai for running AI models on-device on Apple Silicon, with Swift, Python, TypeScript and Rust APIs.

    Browse all tools

    Related Topics

    AI Infrastructure

    Infrastructure designed for deploying and running AI models.

    556 tools

    AI Development Libraries

    Programming libraries and frameworks that provide machine learning capabilities, model integration, and AI functionality for developers.

    530 tools

    Local Inference

    Tools and platforms for running AI inference locally without cloud dependence.

    311 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions