EveryDev.ai
Subscribe
Home
Tools

5,923+ AI tools

  • Featured
  • Gems
  • Trending
  • New
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2992
  • Coding2260
  • Infrastructure1068
  • Projects824
  • MCP795
  • Research744
  • Analytics567
  • Marketing527
  • Design489
  • Testing476
  • Data442
  • Security417
  • Integration288
  • Communication286
  • Prompts284
  • Extensions239
  • Voice214
  • DevOps191
  • Commerce184
  • Web128
  • Learning123
  • Finance44
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. Harbor
    Harbor icon

    Harbor

    LLM Evaluations
    Featured

    Open-source framework for evaluating and optimizing agents and language models in sandboxed container environments.

    Visit Website

    At a Glance

    Pricing
    Open Source

    Harbor core framework, self-hosted and licensed under Apache License 2.0.

    Engagement

    Available On

    API
    SDK
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    LLM EvaluationsAI Development LibrariesAgent Harness

    Alternatives

    ScopeSIA (Self-Improving AI)ClawGUI
    Developer
    Harbor Framework TeamUnited States of AmericaEst. 2025$100M raised

    Listed Nov 2026

    About Harbor

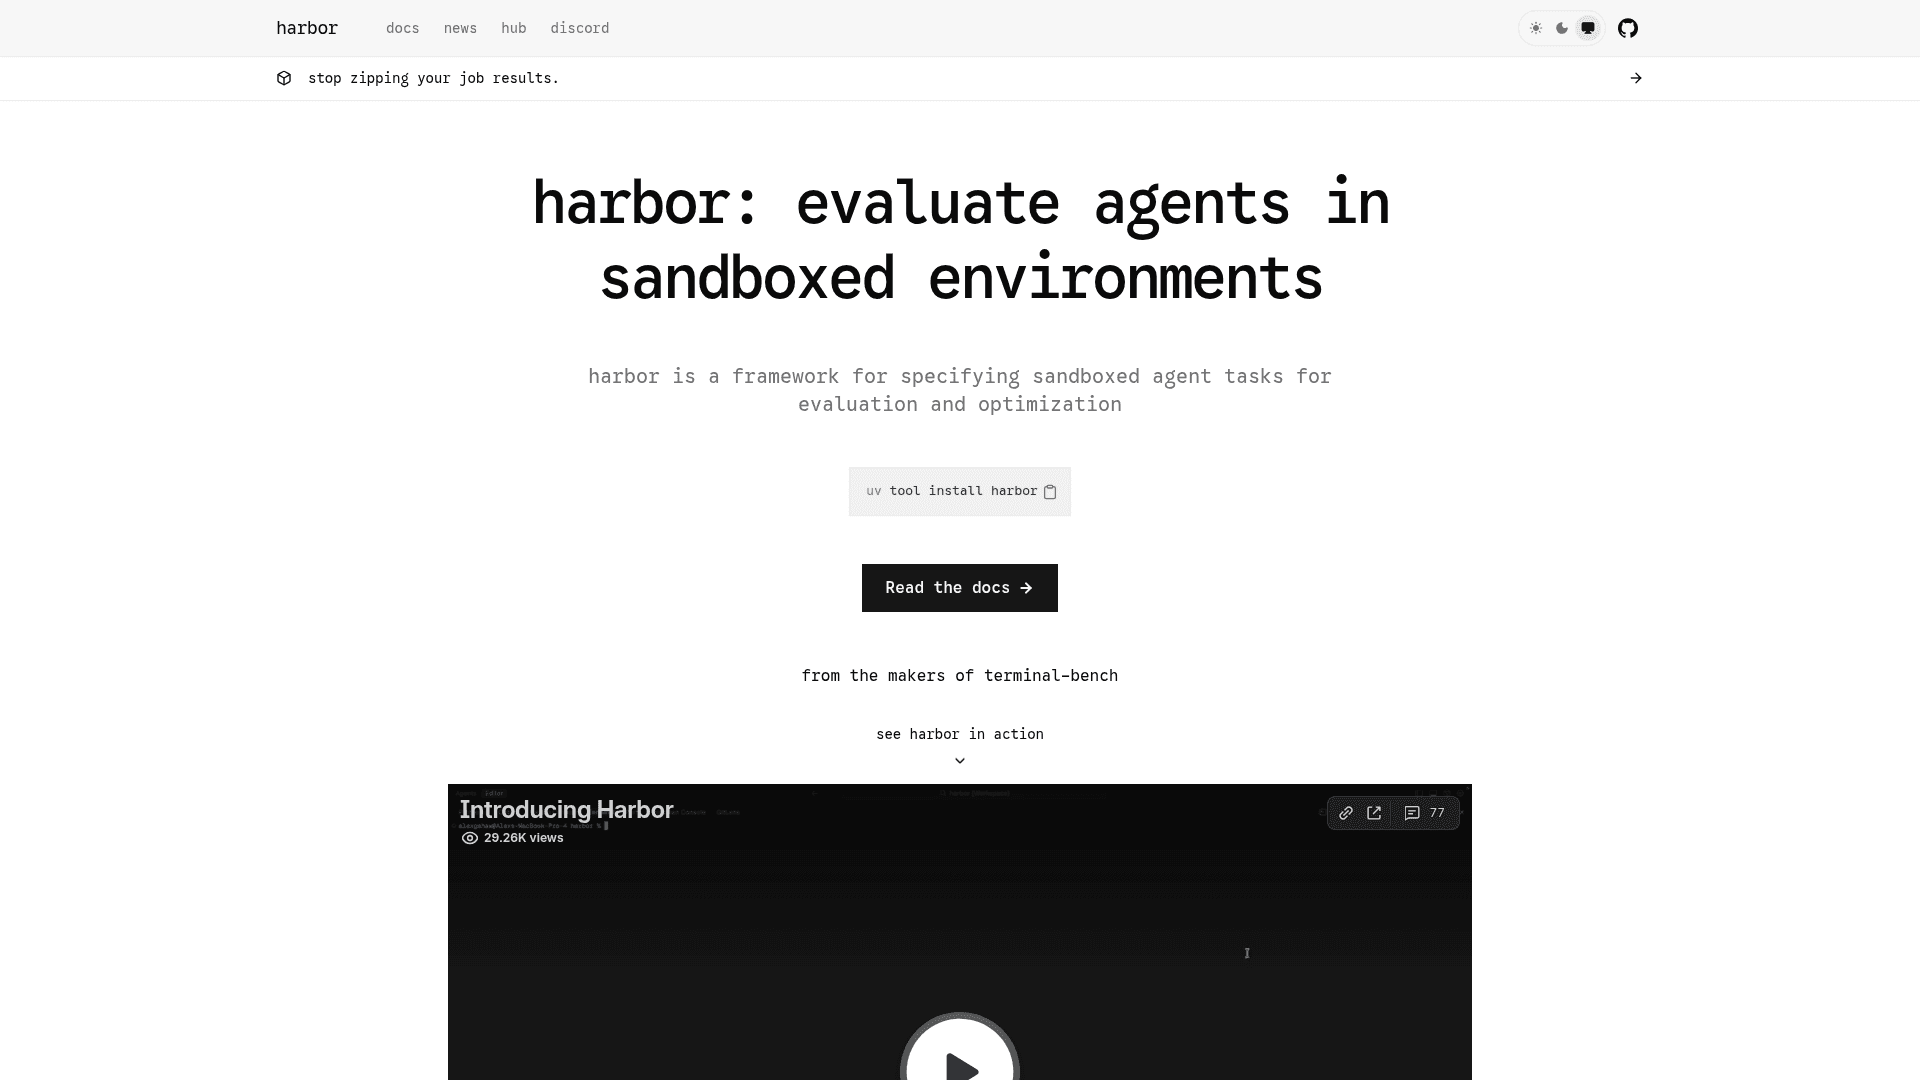
    Harbor is an open-source framework from the creators of Terminal-Bench for evaluating and optimizing agents and language models. It lets users run agents against benchmark datasets in sandboxed environments, locally with Docker or in parallel on cloud sandbox providers. It is installed as a Python package and driven from a command line.

    What It Is

    Harbor is an agent evaluation harness. Users specify sandboxed agent tasks, then run an agent and model against a dataset to measure performance. The README describes it as the official harness for Terminal-Bench-2.0, and it can also run third-party benchmarks such as SWE-Bench and Aider Polyglot.

    How the Workflow Runs

    A run is launched with the harbor run command, choosing a dataset and version, an agent, and a model. By default the benchmark runs locally in Docker. Passing an environment flag moves execution to a cloud provider such as Daytona, with a concurrency setting controlling how many trials run in parallel. harbor datasets list shows the supported benchmarks, and harbor run --help shows supported agents and options.

    Agents, Benchmarks and Rollouts

    The README says Harbor can evaluate arbitrary agents such as Claude Code, OpenHands and Codex CLI. Users can build and share their own benchmarks and environments. Harbor can also generate rollouts for RL optimization. Parallel experiments across thousands of environments are supported through providers including Daytona, Modal, LangSmith, Blaxel, Novita Sandbox, Tensorlake, Runta and Sail.

    Setup Path

    Install with uv tool install harbor or pip install harbor. A separate Harbor Cookbook provides end-to-end examples and guides. The project is licensed under Apache 2.0.
    Harbor - 1

    Community Discussions

    Be the first to start a conversation about Harbor

    Share your experience with Harbor, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    Harbor core framework, self-hosted and licensed under Apache License 2.0.

    • Apache License 2.0 (Apache-2.0)
    • Install via uv tool install harbor or pip install harbor
    • Evaluate agents such as Claude Code, OpenHands, Codex CLI
    • Build and share your own benchmarks and environments
    • Run locally with Docker or on cloud providers like Daytona and Modal

    Capabilities

    Key Features

    • Evaluate arbitrary agents such as Claude Code, OpenHands and Codex CLI
    • Build and share custom benchmarks and environments
    • Run thousands of sandboxed environments in parallel via cloud providers
    • Generate rollouts for RL optimization
    • Official harness for Terminal-Bench-2.0
    • Run third-party benchmarks such as SWE-Bench and Aider Polyglot
    • Local Docker execution or cloud execution via an environment flag
    • Dataset listing and versioned dataset runs from the CLI

    Integrations

    Daytona
    Modal
    LangSmith
    Blaxel
    Novita Sandbox
    Tensorlake
    Runta
    Sail
    Docker
    Claude Code
    OpenHands
    Codex CLI
    SWE-Bench
    Aider Polyglot
    Terminal-Bench
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate Harbor and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    Harbor Framework Team

    The Harbor Framework Team builds open-source infrastructure for evaluating and optimizing AI agents and language models. Their flagship products are Terminal-Bench, a benchmark suite for terminal-use agents, and Harbor, the evaluation harness that powers it. The project is described as a Stanford × Laude collaboration, with contributors including researchers and engineers from those institutions. Harbor supports parallel cloud-based evaluations and RL environment generation, making it a general-purpose platform for agent developers.

    Founded 2025
    United States of America
    $100M raised
    20 employees

    Used by

    Terminal-Bench 2.0
    CompileBench
    Terminal-Bench-Science
    Harbor-Index
    Read more about Harbor Framework Team
    WebsiteGitHubX / Twitter
    3 tools in directory

    Similar Tools

    Scope icon

    Scope

    Open-source platform for evaluating how AI coding agents handle your product using reusable criteria and repeatable experiments.

    SIA (Self-Improving AI) icon

    SIA (Self-Improving AI)

    Open-source framework that uses Meta, Target and Feedback agents to autonomously improve an AI agent's performance on a benchmark task.

    ClawGUI icon

    ClawGUI

    Open-source framework for training GUI agents with online RL, evaluating them on standardized benchmarks, and deploying them on real devices.

    Browse all tools

    Related Topics

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    242 tools

    AI Development Libraries

    Programming libraries and frameworks that provide machine learning capabilities, model integration, and AI functionality for developers.

    573 tools

    Agent Harness

    Infrastructure, orchestrators, and task runners that wrap around LLM coding agents — covering session management, context delivery, worktree isolation, architecture enforcement, and issue-to-PR pipelines.

    455 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions
    9views