EveryDev.ai
Subscribe
Home
Tools

5,347+ AI tools

  • Featured
  • Gems
  • Trending
  • New
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2725
  • Coding2018
  • Infrastructure950
  • Projects752
  • Research670
  • MCP655
  • Analytics520
  • Marketing503
  • Design435
  • Testing432
  • Data395
  • Security362
  • Integration270
  • Prompts257
  • Communication255
  • Extensions227
  • Voice182
  • DevOps176
  • Commerce175
  • Web124
  • Learning114
  • Finance39
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. HELM
    HELM icon

    HELM

    Academic Research

    Open source Python framework from Stanford CRFM for holistic, reproducible, and transparent evaluation of language and multimodal foundation models.

    Visit Website

    At a Glance

    Pricing
    Open Source

    HELM is an open source Python framework released under the Apache License 2.0; install from PyPI and run locally.

    Engagement

    Available On

    CLI
    Web
    SDK

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    Academic ResearchPerformance MetricsLLM Evaluations

    Alternatives

    LLM StatsARC-AGI-2LM Evaluation Harness
    Developer
    Stanford Center for Research on Foundation ModelsStanford University, CaliforniaEst. 2021

    Listed Nov 2026

    About HELM

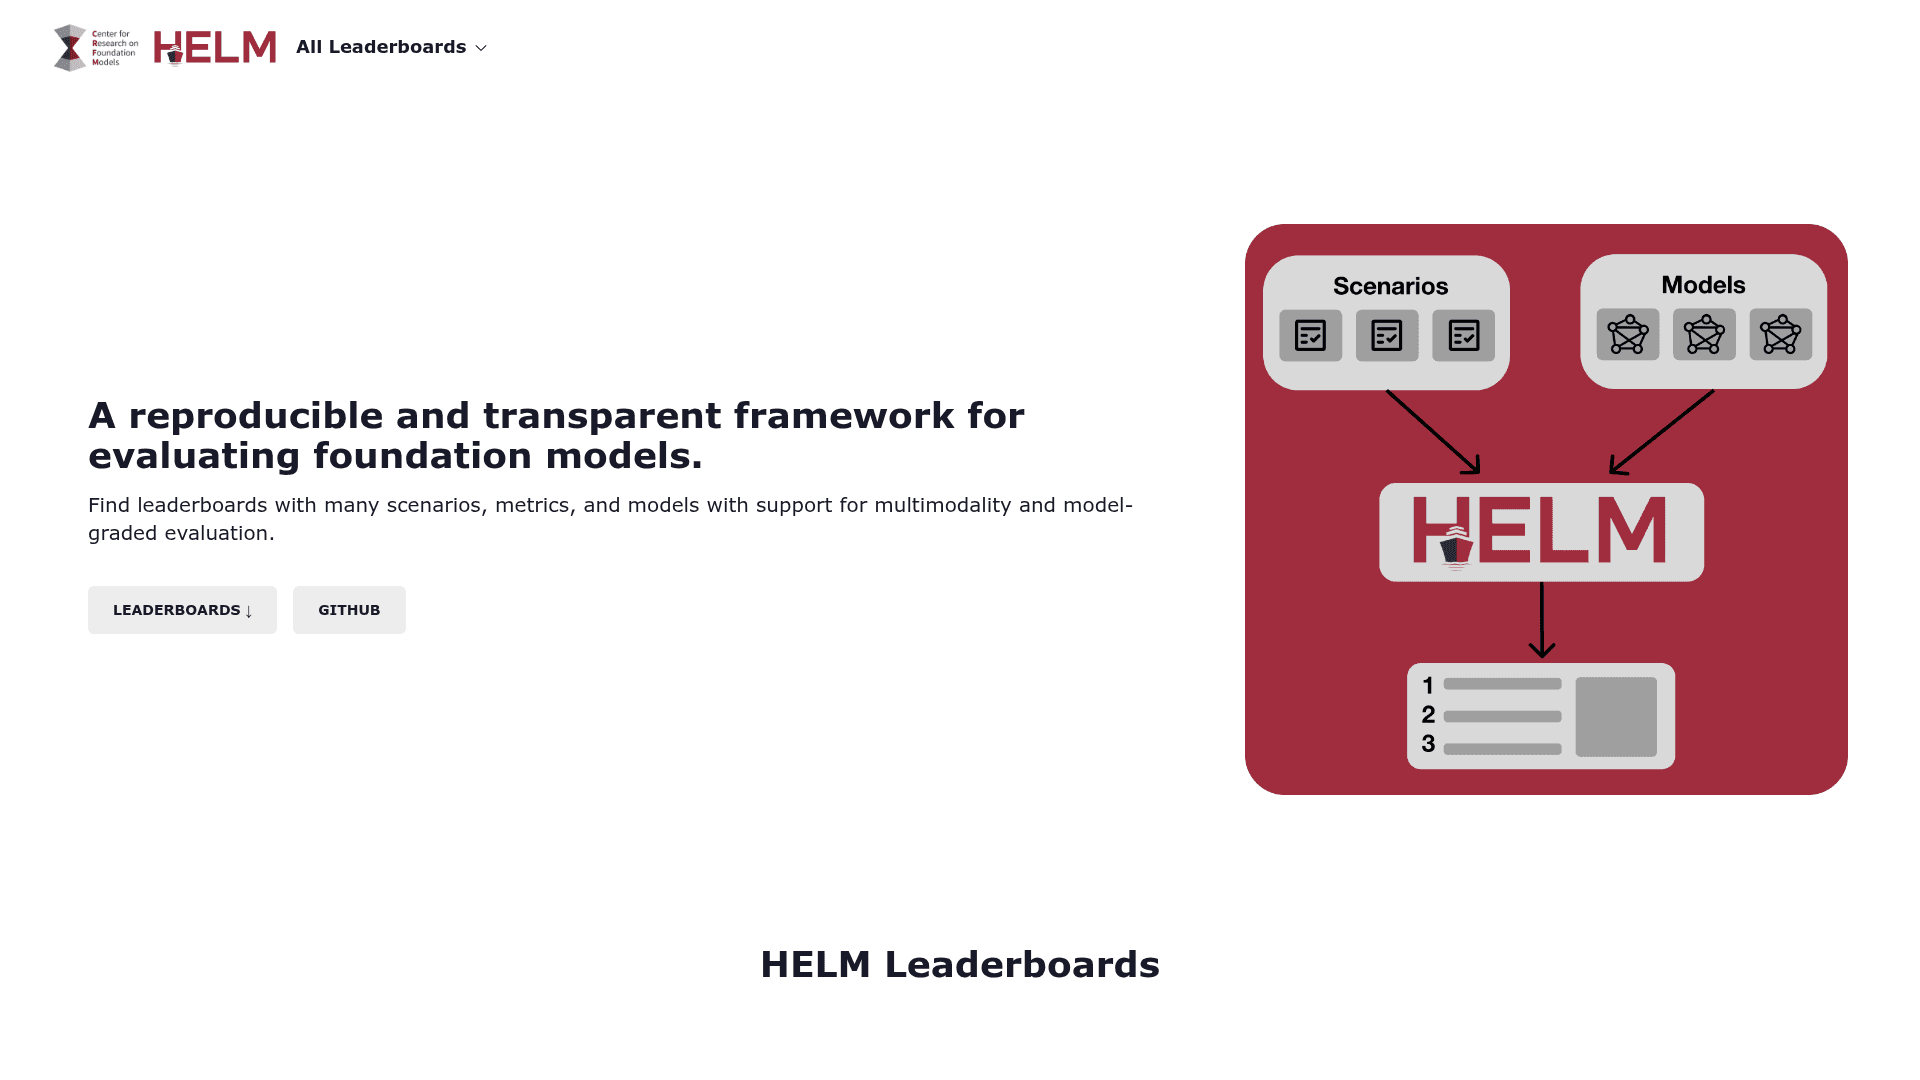
    Holistic Evaluation of Language Models (HELM) is an open source Python framework created by Stanford's Center for Research on Foundation Models (CRFM). It runs standardized benchmarks against models from various providers, computes metrics beyond accuracy, and presents results in a web UI and leaderboards. The README notes that HELM entered maintenance mode on June 1, 2026.

    What It Is

    HELM is a evaluation framework for foundation models, including large language models and multimodal models. It provides datasets and benchmarks in a standardized format (for example MMLU-Pro, GPQA, IFEval, WildBench) and a unified interface to models from providers such as OpenAI, Anthropic Claude, and Google Gemini. Metrics cover aspects such as efficiency, bias, and toxicity in addition to accuracy.

    Workflow and Outputs

    After installing the crfm-helm package from PyPI, users run helm-run with run entries (benchmark, subject, model), summarize results with helm-summarize, and launch helm-server to browse results locally in a browser. The web UI allows inspecting individual prompts and responses, and a web leaderboard compares results across models and benchmarks.

    Official Leaderboards

    The project maintains leaderboards built on the framework. Flagship ones are HELM Capabilities, HELM Safety, and VHELM for vision-language models. Others cover text-to-image models (HEIM), audio-language models, medicine (MedHELM), finance, long context, table reasoning (ToRR), and language-specific benchmarks such as Arabic, Thai, Chinese, and Southeast Asian languages. The framework can be used to reproduce the results published in the associated papers.

    Current Status

    The README states HELM entered maintenance mode on June 1, 2026, with details in a Maintenance Mode Policy. The latest listed release is v0.5.16, published 2026-04-30. It is licensed under Apache 2.0.
    HELM - 1

    Community Discussions

    Be the first to start a conversation about HELM

    Share your experience with HELM, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    HELM is an open source Python framework released under the Apache License 2.0; install from PyPI and run locally.

    • Apache License 2.0
    • Datasets and benchmarks in a standardized format
    • Models from various providers accessible through a unified interface
    • Metrics beyond accuracy (efficiency, bias, toxicity)
    • Web UI for inspecting prompts and responses

    Capabilities

    Key Features

    • Standardized datasets and benchmarks
    • Unified interface to models from multiple providers
    • Metrics beyond accuracy such as efficiency, bias, and toxicity
    • Web UI for inspecting individual prompts and responses
    • Web leaderboards comparing models and benchmarks
    • Multimodal evaluation (vision-language, audio-language, text-to-image)
    • Reproduction of published leaderboard results
    • CLI commands: helm-run, helm-summarize, helm-server

    Integrations

    OpenAI
    Anthropic Claude
    Google Gemini
    PyPI

    Ratings & Reviews

    No ratings yet

    Be the first to rate HELM and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    Stanford Center for Research on Foundation Models

    The Center for Research on Foundation Models (CRFM) is an interdisciplinary initiative at the Stanford Institute for Human-Centered Artificial Intelligence (HAI). It advances the study, development, and deployment of foundation models. The center brings together faculty, students, researchers, and engineers spanning 10+ departments at Stanford.

    Founded 2021
    Stanford University, California
    Read more about Stanford Center for Research on Foundation Models
    WebsiteGitHub
    1 tool in directory

    Similar Tools

    LLM Stats icon

    LLM Stats

    Public leaderboards and benchmark site that publishes verifiable evaluations, scores, and performance metrics for large language models and AI providers.

    ARC-AGI-2 icon

    ARC-AGI-2

    Open dataset of ARC-AGI-2 reasoning tasks for benchmarking AI systems and humans on abstract grid-based puzzles.

    LM Evaluation Harness icon

    LM Evaluation Harness

    Open-source framework from EleutherAI for few-shot evaluation of language models across many academic benchmarks.

    Browse all tools

    Related Topics

    Academic Research

    AI tools designed specifically for academic and scientific research.

    103 tools

    Performance Metrics

    Specialized tools for measuring, evaluating, and optimizing AI model performance across accuracy, speed, resource utilization, and other critical parameters.

    92 tools

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    225 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions