
Hyperstack
GPU-as-a-Service cloud platform from NexGen Cloud offering on-demand and reserved NVIDIA GPU virtual machines for AI, ML and HPC workloads.
At a Glance
Engagement
Available On
Alternatives
Listed Oct 2026
About Hyperstack
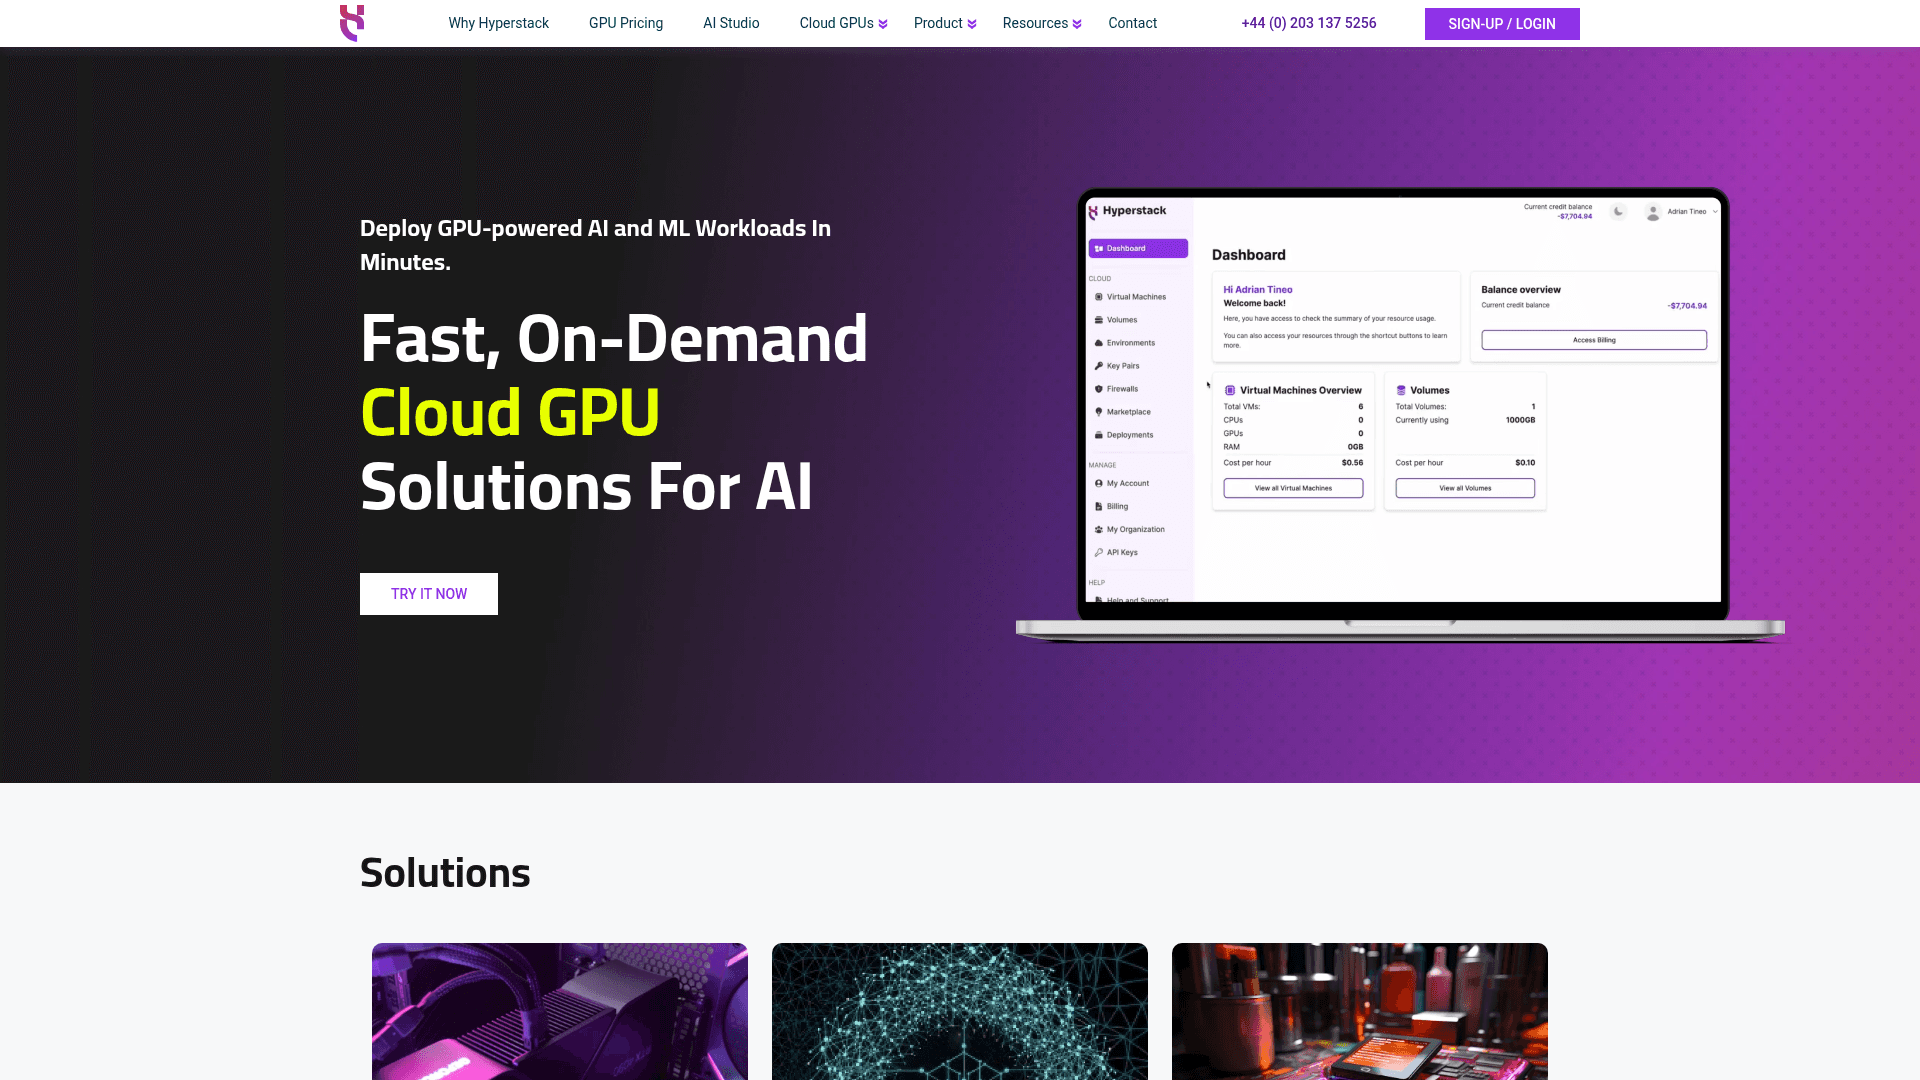
Hyperstack is NexGen Cloud's GPU-as-a-Service platform for AI, machine learning and HPC workloads. It provides NVIDIA GPU virtual machines through a console and an API-first model, with data centres in Europe and North America. The platform also lists Kubernetes, object storage, and an AI Studio for training, deploying and monitoring custom models.
What It Is
Hyperstack is a GPU cloud where users deploy virtual machines on NVIDIA hardware such as H100, H200, A100, L40 and RTX A6000, with newer Blackwell-generation options listed on the site. Workloads include model training, fine-tuning, inference, rendering, virtual workstations, data analytics and simulation. Billing is stated to be accurate to the minute.
Platform and Tooling
The site lists role-based access control, resource callbacks, grouping of VMs into environments, custom-build flavours and one-click deployment. Hyperstack says it has no egress or ingress fees. Developer tooling includes documentation, a Terraform provider, Go and Python SDKs, and an open-source LLM Inference Toolkit.
LLM Inference Toolkit
The MIT-licensed toolkit deploys open-source LLMs locally or on Hyperstack. It provides a UI for managing models, a playground, API key generation with usage limits, a vLLM-backed proxy API, and monitoring of usage data. The default cloud deployment creates a proxy VM plus two inference VMs hosting Llama 3.1 8B Instruct and Phi-3 medium.
Current Status
The homepage announces NVIDIA B300s coming on-demand in August, with reserved private clusters in Q4. AI Studio is presented as an early-access offering. The site also warns of a fraudulent site impersonating Hyperstack.
Community Discussions
Be the first to start a conversation about Hyperstack
Share your experience with Hyperstack, ask questions, or help others learn from your insights.
Pricing
NVIDIA RTX Pro 6000 SE
On-demand GPU VM, billed per hour
- 96 GB VRAM
- Max 31 pCPUs per GPU
- Max 180 GB RAM per GPU
- Reservation pricing starts from $1.30/hour
NVIDIA H200 SXM
On-demand GPU VM, billed per hour
- 141 GB VRAM
- Max 22 pCPUs per GPU
- Max 225 GB RAM per GPU
- Reservation pricing starts from $2.79/hour
NVIDIA H100 SXM
On-demand GPU VM, billed per hour
- 80 GB VRAM
- Max 24 pCPUs per GPU
- Max 240 GB RAM per GPU
- Reservation pricing starts from $2.72/hour
NVIDIA A100 SXM
On-demand GPU VM, billed per hour
- 80 GB VRAM
- Max 24 pCPUs per GPU
- Max 120 GB RAM per GPU
- Reservation pricing starts from $1.36/hour
NVIDIA A4000
On-demand GPU VM, billed per hour
- 16 GB VRAM
- Max 6 pCPUs per GPU
- Max 24 GB RAM per GPU
- Reservation pricing starts from $0.11/hour
Capabilities
Key Features
- On-demand NVIDIA GPU virtual machines
- Reserved GPU capacity and private clusters
- Spot VMs
- On-demand Kubernetes
- Object storage
- AI Studio for training, deploying and monitoring custom models
- Role-based access control
- API-first management
- Per-minute billing
- One-click deployment
- Custom-build flavours
- Environments for organizing VMs
- Resource callbacks
- Terraform provider and Go/Python SDKs
- LLM Inference Toolkit