Liquid Inference
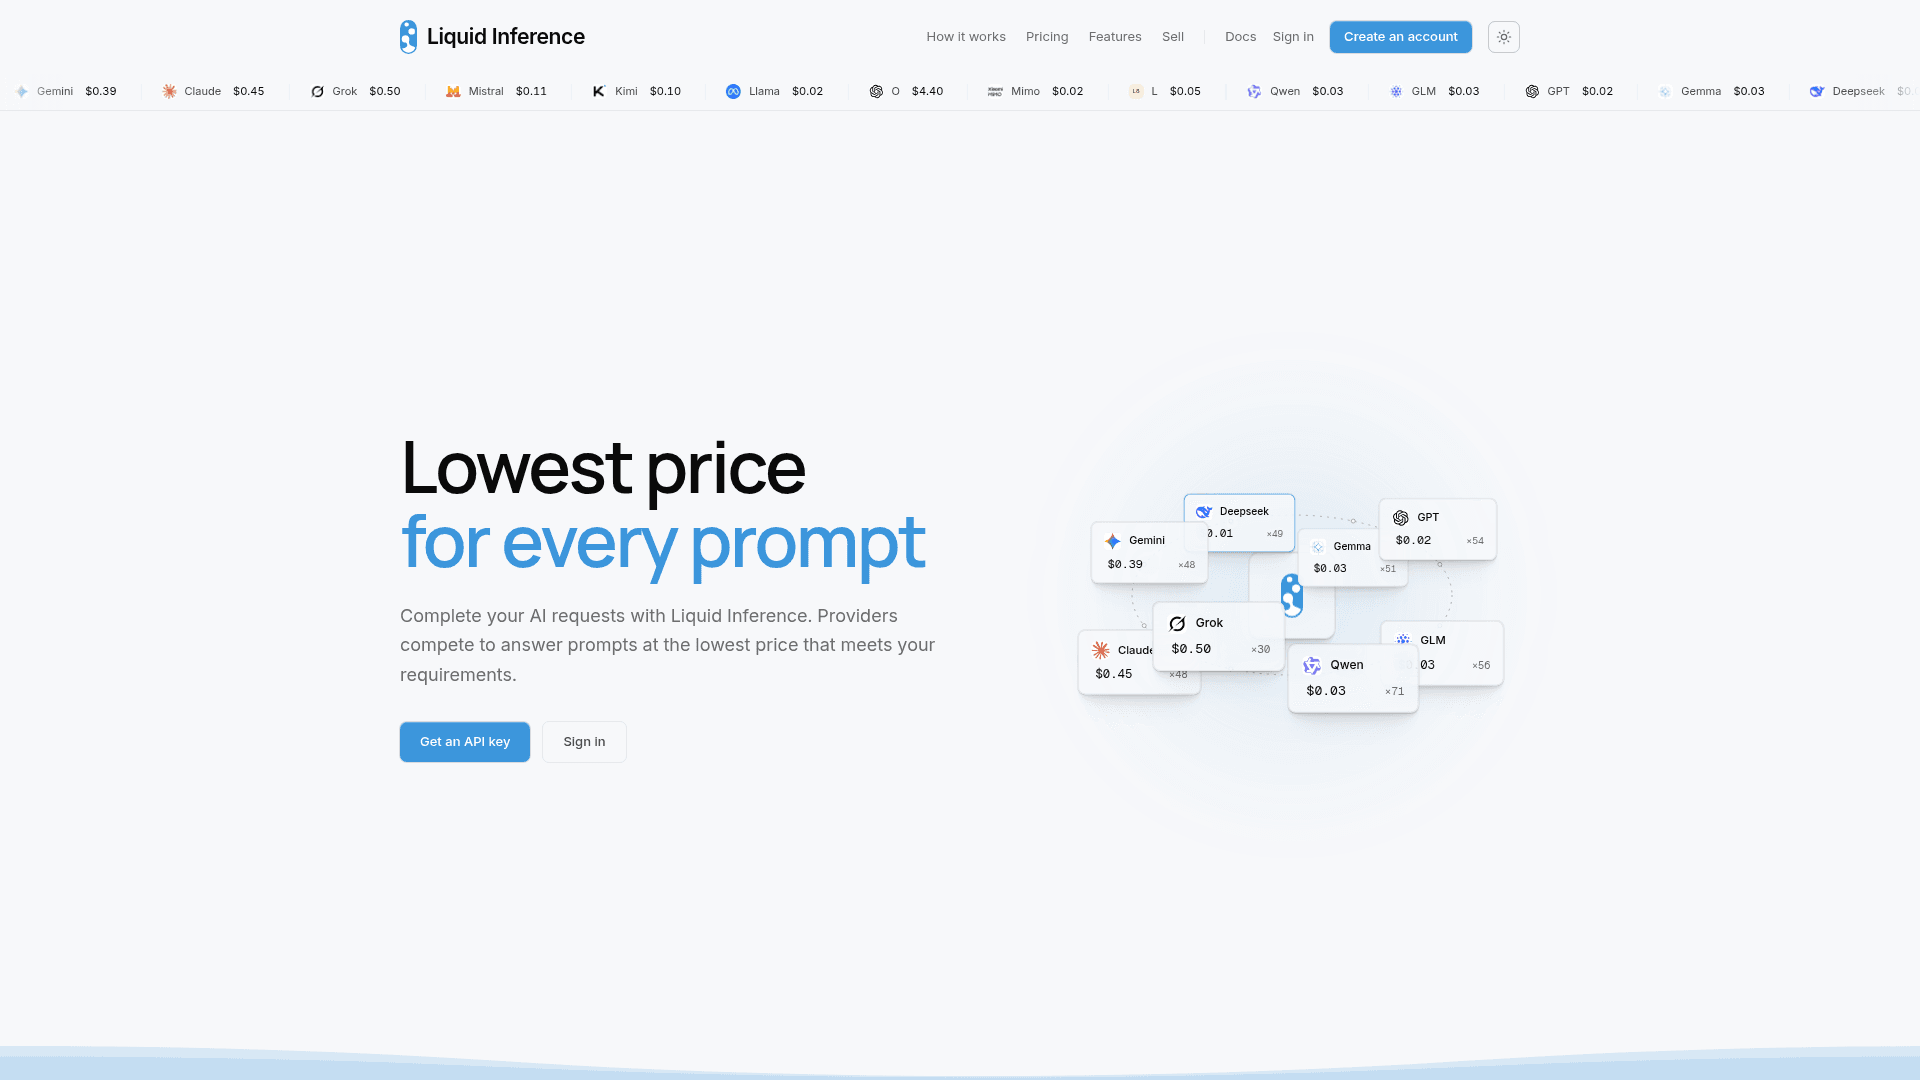
An auction exchange for LLM inference where providers compete to serve each request at the lowest price that meets your requirements.
At a Glance
Engagement
Available On
Alternatives
Listed Oct 2026
About Liquid Inference
Liquid Inference, by the AI Exchange and Architect Financial Technologies, Inc., is an auction-style marketplace for LLM inference. Users send ordinary chat requests through an OpenAI- or Anthropic-compatible API, and providers compete to answer each one at the lowest price meeting the user's rules.
What It Is
Liquid Inference is an inference routing exchange. Providers set a per-token price for each model they serve and can change it at any time. Customers choose the model, region, speed and minimum quality, and the cheapest provider that meets those rules answers the request. The site lists model families such as Qwen, GLM, GPT, Gemma, DeepSeek, Gemini, Claude, Grok, Mistral, Kimi and Llama.
How requests are priced and routed
The maximum cost of a request is fixed before the model starts, and billing covers only the tokens produced. Billing is itemized line by line. Public price history for live and past prices can be downloaded, so work can be sent when prices are low. The vendor says Architect Liquid Inference regularly tests every provider with standard benchmarks and publishes the results.
Compatibility and setup
OpenAI Chat Completions and Anthropic Messages are served on one base URL, so existing code works by changing the base URL and API key. The site lists compatible clients and SDKs including Claude Code, Codex, Cursor, OpenCode, Cline, Roo Code, Kilo Code, Goose, Open WebUI, n8n, the OpenAI and Anthropic SDKs, the Vercel AI SDK, LiteLLM, LangChain and curl.
Selling inference
Providers can sell inference on models they already run. Their software posts prices and adjusts them as costs change. The provider flow is: create an account, register a deployment, have an operator review and list it, then connect an agent and start quoting. Providers can stop quoting when full or lower prices when they have spare capacity.
Community Discussions
Be the first to start a conversation about Liquid Inference
Share your experience with Liquid Inference, ask questions, or help others learn from your insights.
Pricing
Pay-as-you-go (Deepseek)
Metered marketplace pricing; lowest current offer for Deepseek models, billed only for tokens produced.
- Lowest offer now: $0.01 USD per Mtok output (DeepSeek V4 Flash)
- Output tokens only; input tokens priced separately
- Billed only for tokens produced; maximum request cost fixed before first token
Pay-as-you-go (GPT)
Metered marketplace pricing; lowest current offer for GPT models.
- Lowest offer now: $0.02 USD per Mtok output (GPT: OSS 120B)
- Output tokens only; input tokens priced separately
Pay-as-you-go (Qwen)
Metered marketplace pricing; lowest current offer for Qwen models.
- Lowest offer now: $0.03 USD per Mtok output (Qwen 2.5 Coder 3B Instruct)
- Output tokens only; input tokens priced separately
Pay-as-you-go (Gemini)
Metered marketplace pricing; lowest current offer for Gemini models.
- Lowest offer now: $0.39 USD per Mtok output
- Output tokens only; input tokens priced separately
Pay-as-you-go (Claude)
Metered marketplace pricing; lowest current offer for Claude models.
- Lowest offer now: $0.45 USD per Mtok output
- Output tokens only; input tokens priced separately
Capabilities
Key Features
- Auction-based routing to the cheapest provider that meets requirements
- Routing rules for model, region, speed and minimum quality
- Per-request price cap fixed before the first token
- Itemized billing
- Public price history download
- Independent provider benchmarks
- OpenAI Chat Completions and Anthropic Messages compatibility on one base URL
- Provider marketplace with self-set prices