EveryDev.ai
Subscribe
Home
Tools

4,741+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents3426
  • Coding2391
  • Infrastructure1055
  • Projects732
  • Marketing662
  • Research612
  • MCP593
  • Analytics538
  • Design533
  • Testing420
  • Security410
  • Data358
  • Prompts260
  • Integration256
  • Communication250
  • Extensions222
  • Voice201
  • Learning193
  • Commerce173
  • DevOps161
  • Web122
  • Finance36
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai © 2026
    1. Home
    2. Tools
    3. LMCache
    LMCache icon

    LMCache

    AI Infrastructure
    Featured

    Open-source KV cache management layer that stores, reuses, compresses and moves KV cache to speed up LLM inference.

    Visit Website

    At a Glance

    Pricing
    Open Source

    LMCache core KV cache layer, self-hosted under the Apache License 2.0.

    Engagement

    Available On

    Linux
    API
    SDK
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    AI InfrastructureCompute OptimizationLocal Inference

    Alternatives

    ML DriftChituWafer
    Developer
    LMCacheChicago, ILEst. 2023

    Listed Oct 2026

    About LMCache

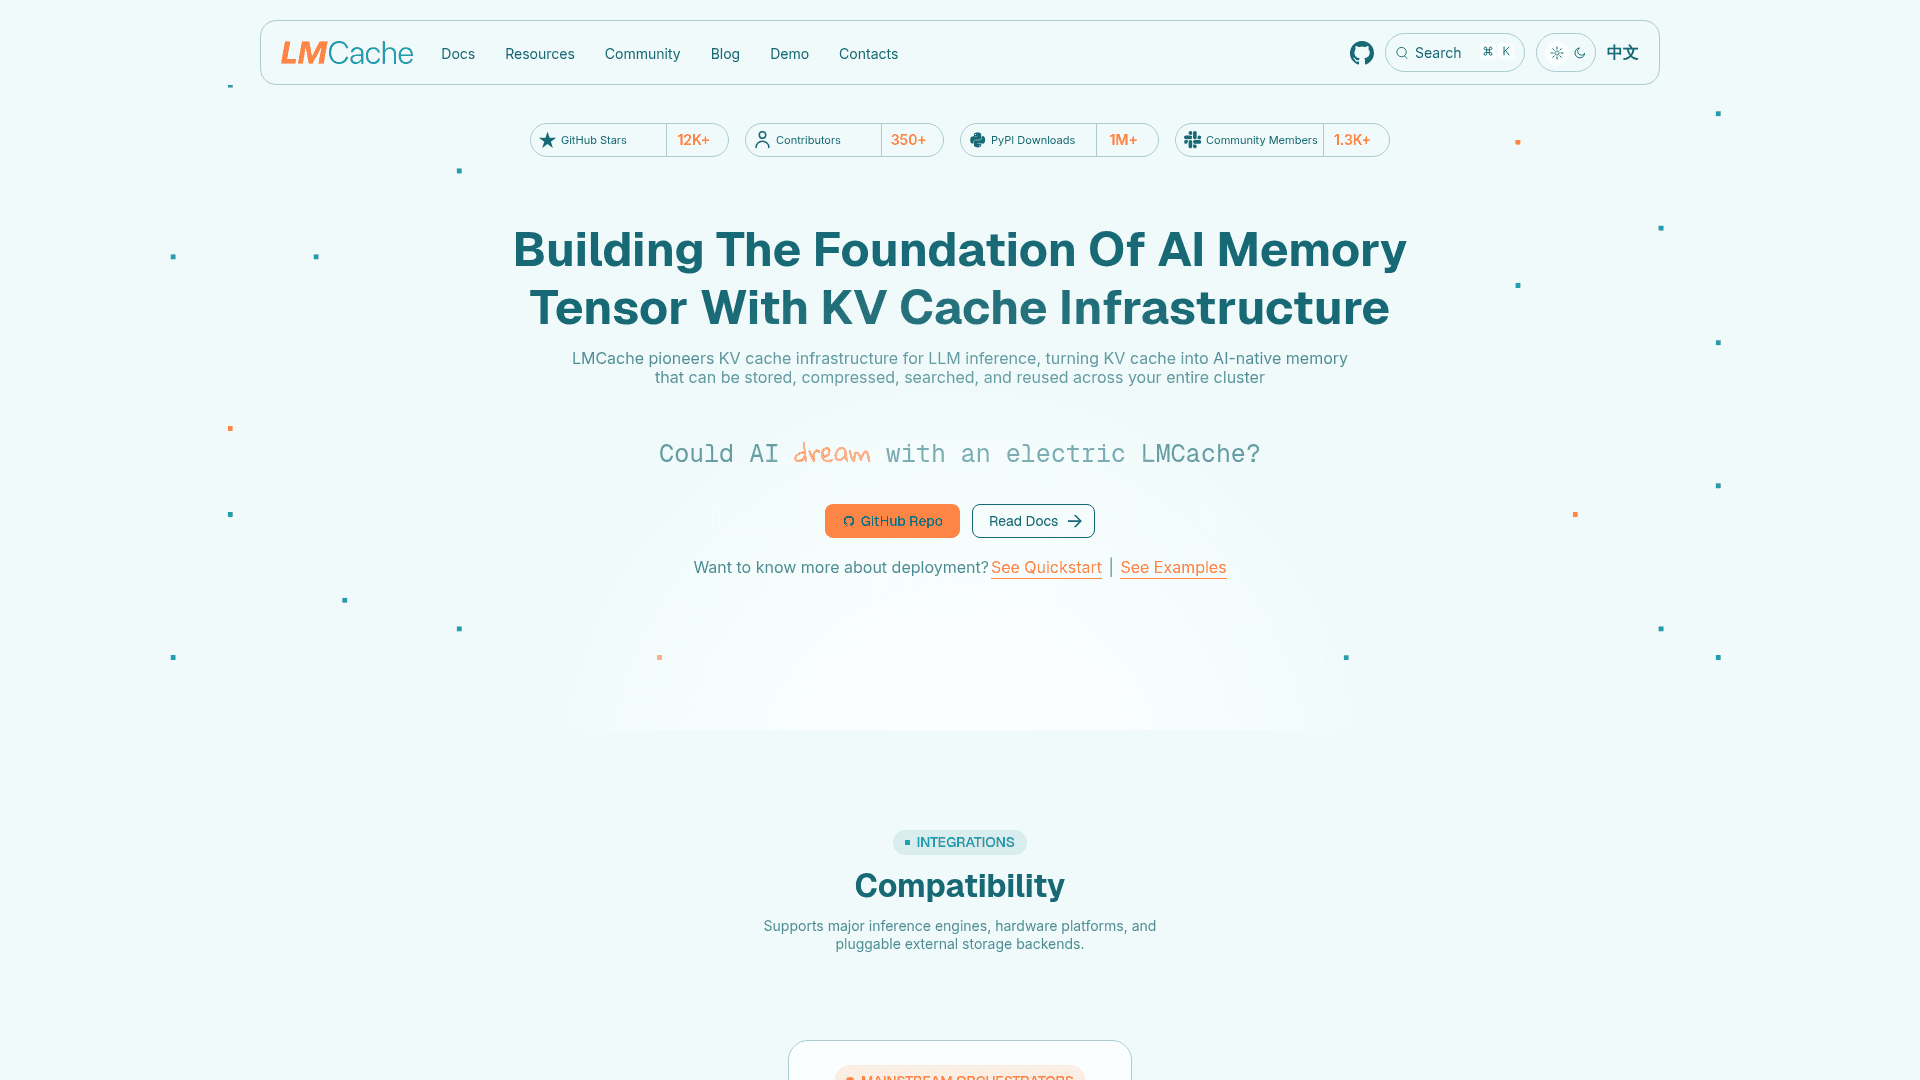
    LMCache is an open-source KV cache management layer for LLM inference, developed as a community project under the LMCache GitHub organization. It persists KV cache beyond GPU memory and reuses it across requests, sessions and serving engines, which the project says reduces time-to-first-token and improves throughput for long-context, multi-turn and RAG workloads. The latest release listed is v0.5.5, and the code is licensed under Apache 2.0.

    What It Is

    LMCache sits between an inference engine and storage, treating KV cache as reusable data rather than temporary state. Instead of recomputing prefill for repeated prompts, conversation history or retrieved content, the engine can load previously computed KV cache from CPU memory, local disk or external backends. The project describes itself as vendor-neutral, so users can switch serving engines and storage vendors while reusing stored caches. It installs with pip install lmcache.

    Deployment Modes

    LMCache supports an in-process mode, where it runs inside the inference engine process, and a multiprocess mode, where it runs as a standalone server separate from the engine. The multiprocess mode keeps cache available if an engine worker crashes or restarts. The project site names it the recommended path and the focus of future development.

    Caching Capabilities

    • Tiered offloading across CPU RAM, local storage and remote backends such as Redis/Valkey, Mooncake, InfiniStore, S3-compatible object storage, NIXL and GDS.
    • Non-prefix KV reuse through CacheBlend, which selectively recomputes tokens to recover quality.
    • KV transfer from prefill to decode workers over NVLink, RDMA or TCP for prefill/decode disaggregation.
    • A pluggable SERDE interface for compression, token dropping and custom serialization.
    • Observability metrics covering health, prefix cache hits, cache lifecycle and per-user usage.

    Research Background

    The project site says LMCache grew out of systems research at the University of Chicago, and it links the LMCache, CacheGen and CacheBlend papers. The README says its development is supported in part by Tensormesh.
    LMCache - 1

    Community Discussions

    Be the first to start a conversation about LMCache

    Share your experience with LMCache, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    LMCache core KV cache layer, self-hosted under the Apache License 2.0.

    • Apache License 2.0 codebase
    • Install via pip install lmcache
    • In-process and multiprocess deployment modes
    • Tiered KV cache offloading (CPU memory, local disk, remote backends)
    • Non-prefix KV reuse with CacheBlend

    Capabilities

    Key Features

    • Tiered KV cache offloading across GPU, CPU memory, disk and remote backends
    • KV cache reuse across requests, sessions and engines
    • Non-prefix KV reuse with CacheBlend
    • Standalone multiprocess server mode
    • In-process deployment mode
    • Prefill-decode disaggregation KV transfer over NVLink, RDMA or TCP
    • Pluggable storage and transport backends
    • Pluggable KV transformation via SERDE interface
    • KV cache observability metrics
    • KV cache compression
    • Multi-node P2P CPU memory sharing
    • CLI and benchmarking tools

    Integrations

    vLLM
    NVIDIA Dynamo
    Redis
    Valkey
    Mooncake
    InfiniStore
    S3-compatible object storage
    NIXL
    GDS
    CoreWeave AI Object Storage
    Google Kubernetes Engine
    AMD Instinct GPUs
    PyTorch
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate LMCache and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    LMCache Team

    Founded 2023
    Chicago, IL

    Used by

    Bloomberg
    Red Hat
    Redis
    Tencent
    +3 more
    Read more about LMCache Team
    WebsiteGitHubX / Twitter
    1 tool in directory

    Similar Tools

    ML Drift icon

    ML Drift

    Cross-platform GPU-accelerated inference engine for running ML and large generative models on-device across mobile, web, and servers.

    Chitu icon

    Chitu

    High-performance open-source large language model inference framework focused on efficiency, flexibility, and usability across diverse hardware.

    Wafer icon

    Wafer

    Wafer uses AI agents to autonomously optimize AI inference, delivering 1.5–5x faster performance on any hardware for chip companies, cloud providers, and AI labs.

    Browse all tools

    Related Topics

    AI Infrastructure

    Infrastructure designed for deploying and running AI models.

    472 tools

    Compute Optimization

    Tools for optimizing computational resources and performance.

    57 tools

    Local Inference

    Tools and platforms for running AI inference locally without cloud dependence.

    263 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions