EveryDev.ai
Subscribe
Home
Tools

5,007+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2546
  • Coding1875
  • Infrastructure880
  • Projects712
  • Research627
  • MCP598
  • Marketing495
  • Analytics485
  • Design416
  • Testing402
  • Data373
  • Security317
  • Integration257
  • Communication250
  • Prompts241
  • Extensions218
  • Commerce169
  • DevOps168
  • Voice168
  • Web123
  • Learning114
  • Finance33
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. OpenEvals
    OpenEvals icon

    OpenEvals

    Automated Testing
    Featured

    Open-source Python and TypeScript library of readymade evaluators for testing LLM applications, including LLM-as-judge, structured output, code, and agent trajectory evals.

    Visit Website

    At a Glance

    Pricing
    Open Source

    OpenEvals core package is MIT-licensed and free to use, modify, and distribute. LLM-as-judge evaluators require your own model provider API key (external cost).

    Engagement

    Available On

    Windows
    API
    SDK
    CLI

    Resources

    WebsiteGitHubllms.txt

    Topics

    Automated TestingLLM EvaluationsAI Development Libraries

    Alternatives

    AgentEvalsBigCode Evaluation HarnessEvalPlus
    Developer
    LangChain, Inc.San Francisco, CAEst. 2023$160M raised

    Listed Oct 2026

    About OpenEvals

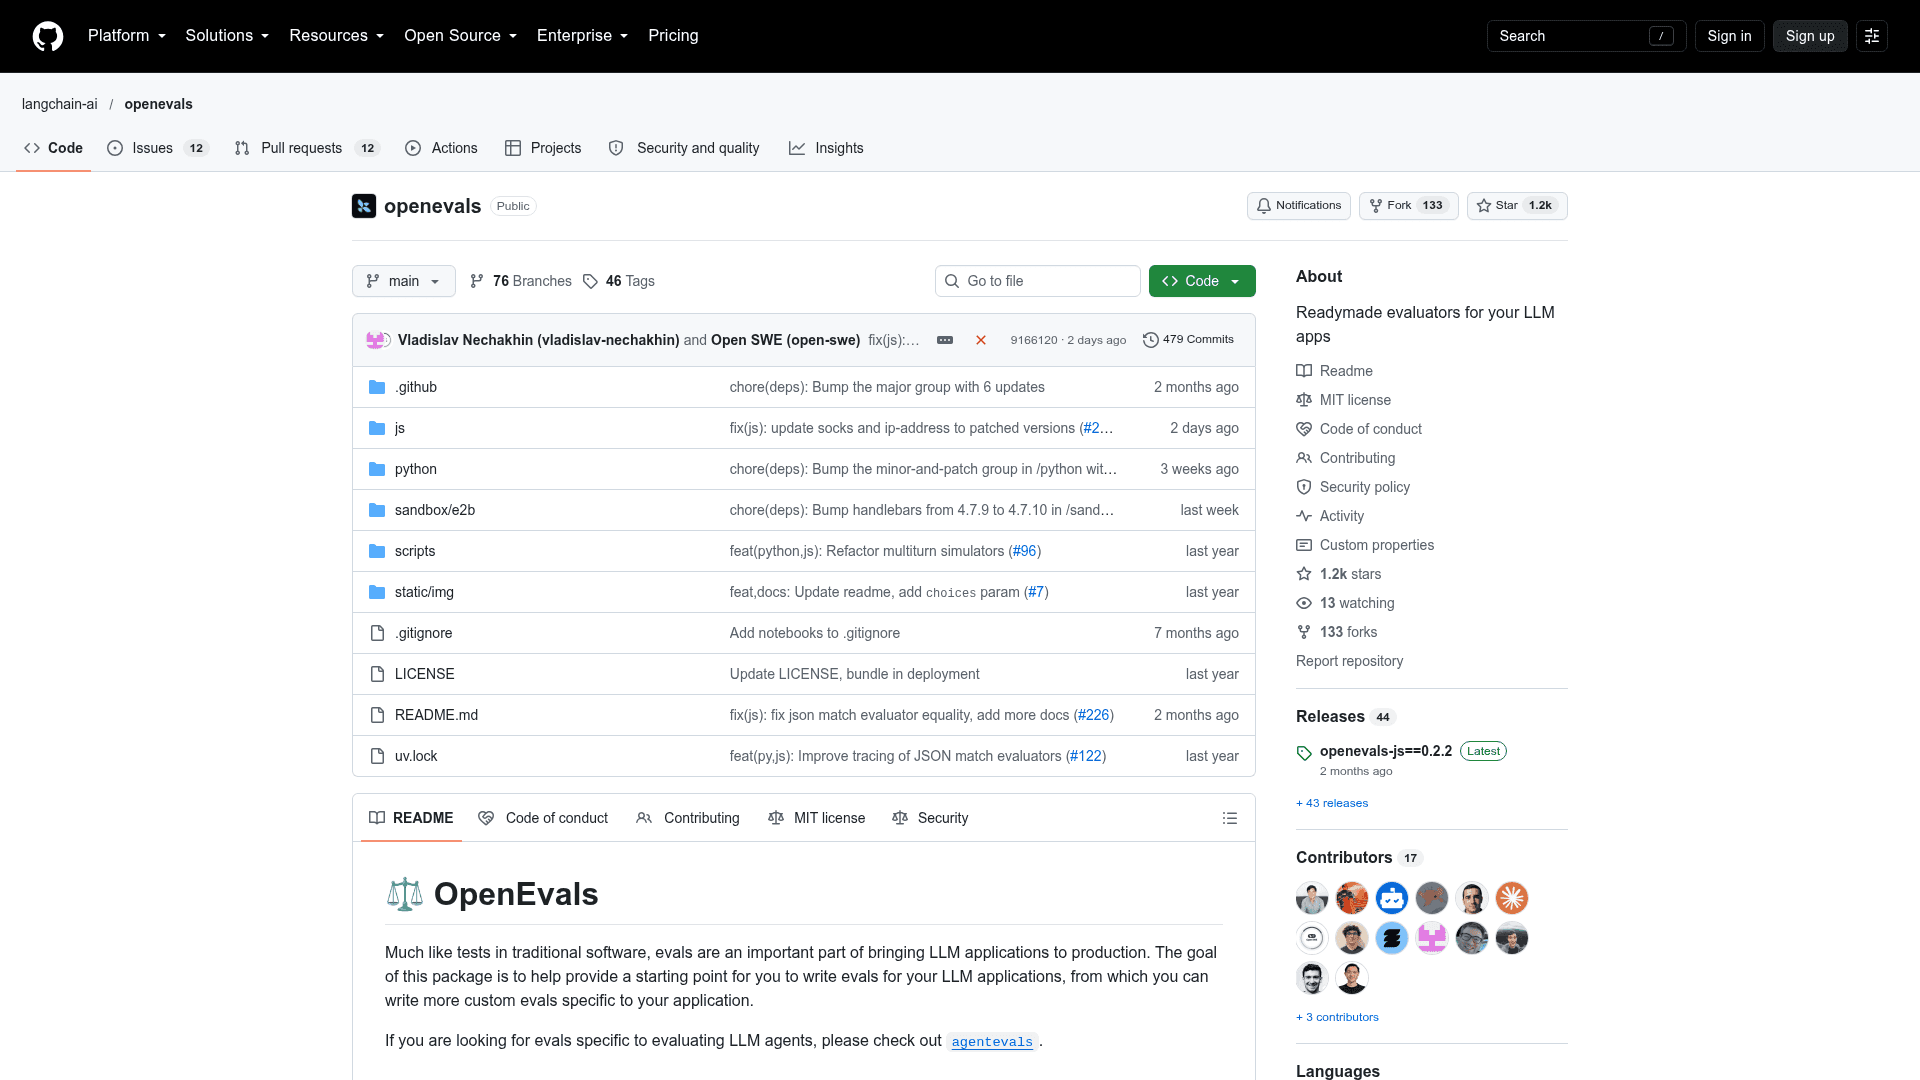
    OpenEvals is an open-source evaluation library from LangChain that provides readymade evaluators for LLM applications, available in Python and TypeScript. It gives developers a starting point for writing evals, which they can then customize for their own application. The latest release listed in the repository is openevals-js==0.2.2.

    What It Is

    OpenEvals is a package of evaluator functions that score the outputs of LLM-based systems, much like tests in traditional software. Developers pass in inputs, outputs, and optionally reference_outputs, and receive a result containing a key, a score, and a comment. Evaluators specific to LLM agents are covered by a separate LangChain package, agentevals, which the README points to.

    LLM-as-Judge and Prebuilt Prompts

    The core evaluator is create_llm_as_judge, which takes a prompt and a model and returns an evaluator function that formats parameters into the prompt and parses the judge model's output into a score. Prompts can be f-strings, LangChain prompt templates, or functions that return messages. Scores can be binary, continuous, or drawn from custom choices, and custom output schemas are supported. The judge model can be set via a PROVIDER:MODEL string, a LangChain chat model, or an OpenAI client.

    Prebuilt prompts cover several areas:

    • Quality: conciseness, correctness, hallucination, answer relevance, plan adherence, code correctness, and laziness.
    • Safety and security: toxicity, fairness, PII leakage, prompt injection, and code injection.
    • Multimodal: image prompts such as explicit content and sensitive imagery, and voice prompts such as audio quality and transcription accuracy, using image, audio, and PDF attachments.
    • RAG: correctness, helpfulness, groundedness, and retrieval relevance.

    Structured Output, Code, and Agent Trajectories

    A JSON match evaluator checks extraction and tool-call outputs with exact match or with LLM-as-judge rubrics for chosen keys, with aggregation across keys and lists. Code evaluators extract code from LLM output and type-check it with Pyright, Mypy, or the TypeScript compiler, or judge it with an LLM. Sandboxed variants use E2B to install dependencies and run Pyright, TypeScript type-checking, or execution in isolation.

    For agents, trajectory match evaluators compare tool-call sequences against a reference in strict, unordered, subset, or superset modes, with configurable tool-argument matching. A trajectory LLM-as-judge assesses accuracy with or without a reference. Other string evaluators include exact match, Levenshtein distance, and embedding similarity.

    Setup and Integrations

    Install with pip install openevals for Python or npm install openevals @langchain/core for TypeScript. LLM-as-judge evaluators need an LLM client, by default through LangChain chat model integrations. The README also describes multiturn simulation with simulated users and LangGraph, and LangSmith integration through pytest, Vitest/Jest, or evaluate.
    OpenEvals - 1

    Community Discussions

    Be the first to start a conversation about OpenEvals

    Share your experience with OpenEvals, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source (MIT)

    OpenEvals core package is MIT-licensed and free to use, modify, and distribute. LLM-as-judge evaluators require your own model provider API key (external cost).

    • MIT License
    • Python and TypeScript packages
    • Prebuilt LLM-as-judge evaluator prompts
    • Bring your own model API key (e.g., OpenAI) for LLM-as-judge evaluators

    Capabilities

    Key Features

    • LLM-as-judge evaluator factory with customizable prompts, models, and scoring
    • Prebuilt prompts for quality, safety, security, image, voice, and RAG evaluation
    • Structured output and tool call evaluation with JSON match evaluator
    • Code evaluators using Pyright, Mypy, TypeScript type-checking, and LLM-as-judge
    • Sandboxed code type-checking and execution via E2B
    • Agent trajectory match evaluators in strict, unordered, subset, and superset modes
    • Trajectory LLM-as-judge evaluator
    • Exact match, Levenshtein distance, and embedding similarity evaluators
    • Multimodal support for images, audio, and PDFs
    • Multiturn simulation with simulated users
    • Custom output schemas and custom evaluator creation
    • Python async support

    Integrations

    LangChain
    LangSmith
    LangGraph
    OpenAI
    Anthropic
    Google Gemini
    E2B
    Pyright
    Mypy
    Pytest
    Vitest
    Jest
    API Available

    Demo Video

    OpenEvals Demo Video
    Watch on YouTube

    Ratings & Reviews

    No ratings yet

    Be the first to rate OpenEvals and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    LangChain, Inc.

    LangChain is a company focused on building a comprehensive framework for developing applications with large language models (LLMs) through composable building blocks for orchestrating agentic workflows.

    Founded 2023
    San Francisco, CA
    $160M raised
    136 employees

    Used by

    Replit
    Clay
    Harvey
    Rippling
    +13 more
    Read more about LangChain, Inc.
    WebsiteGitHubX / Twitter
    10 tools in directory

    Similar Tools

    AgentEvals icon

    AgentEvals

    Readymade evaluators for scoring LLM agent trajectories in Python and TypeScript.

    BigCode Evaluation Harness icon

    BigCode Evaluation Harness

    A framework for evaluating autoregressive code generation language models on a range of code benchmarks.

    EvalPlus icon

    EvalPlus

    Open-source evaluation framework that rigorously tests LLM-generated code for correctness and efficiency using HumanEval+, MBPP+ and EvalPerf.

    Browse all tools

    Related Topics

    Automated Testing

    AI-powered platforms that automate end-to-end testing processes with intelligent test case generation, execution, and reporting for faster, more reliable software delivery.

    179 tools

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    198 tools

    AI Development Libraries

    Programming libraries and frameworks that provide machine learning capabilities, model integration, and AI functionality for developers.

    471 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions