
PageSift
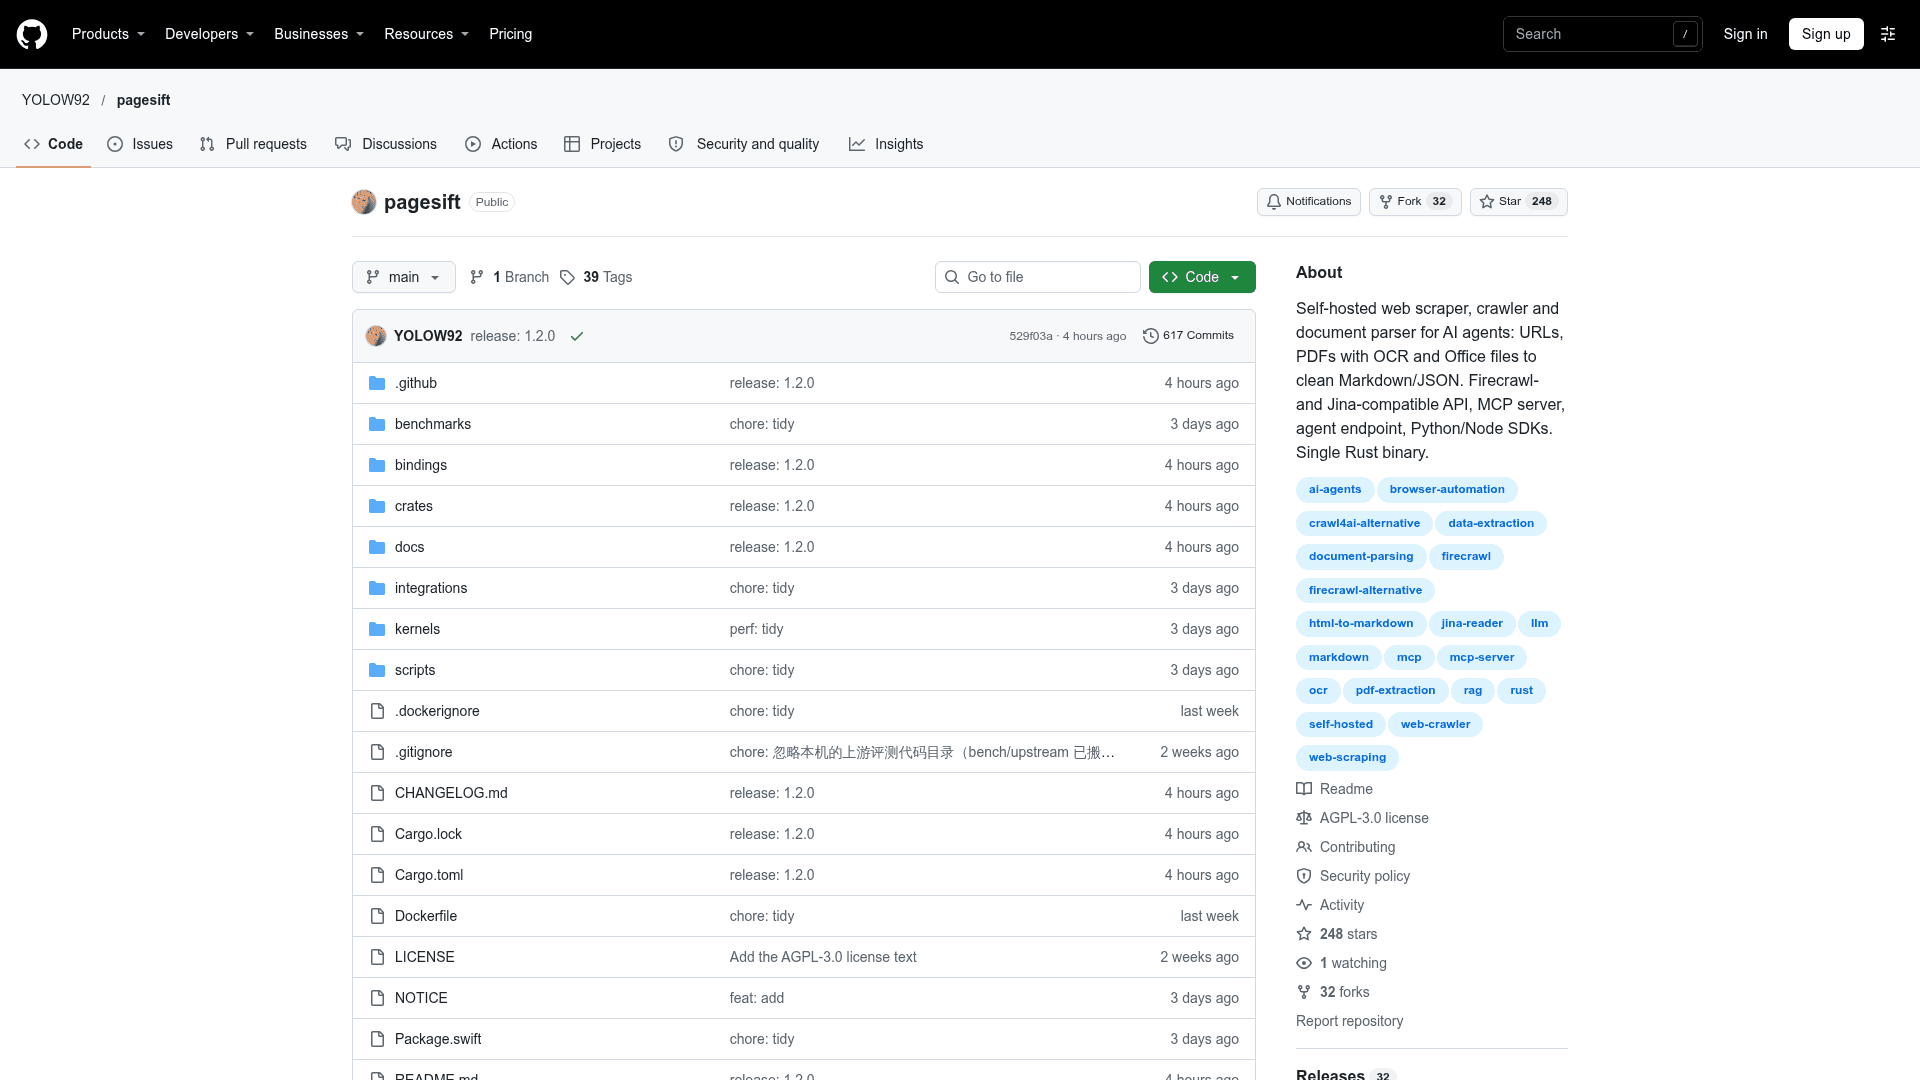
Self-hosted Rust web scraper, crawler and document parser that turns URLs, PDFs and Office files into clean Markdown or JSON for AI agents.
At a Glance
Self-hosted pagesift core under AGPL-3.0, a free copyleft license.
Engagement
Available On
Alternatives
Listed Nov 2026
About PageSift
PageSift is a self-hosted web and document extraction engine published by YOLOW92 on GitHub. It fetches a URL, rendering JavaScript only when that adds content, or opens a local file, and returns Markdown or structured JSON. The current release is 1.2.0, distributed as a single Rust binary with a CLI, HTTP API, MCP server and language packages.
What It Is
PageSift is a web scraper, crawler and document parser aimed at feeding LLMs, RAG indexes and agents. Inputs include URLs, HTML, PDFs (including scanned pages via OCR), Word, Excel and PowerPoint files, OpenDocument, e-books, email, archives, databases, source code and WARC archives. Outputs include Markdown, HTML, links, images, metadata and schema-based JSON, with warnings when a result is incomplete.
Interfaces and Compatibility
The project exposes a CLI, a Firecrawl v1/v2-compatible HTTP API, Jina Reader-style endpoints, and an MCP server over stdio or HTTP. Packages are listed for Python, Node.js/TypeScript and Rust, plus a C ABI with bindings for Go, Java, Kotlin, C#, Ruby, PHP and others, along with LangChain and LlamaIndex. It runs on Linux, macOS arm64 and Windows x86_64, and is also published as a Docker image.
Workflow Capabilities
- Structured extraction by CSS selectors that are relocated when a site changes, or by a schema written by your own model.
- Browser actions such as clicks, typing and scrolling, with persistent sessions.
- An agent endpoint that answers questions from the web using your own model and checks each field against the source evidence.
- Scheduled change monitoring with webhooks, sitemap and query-focused crawling, and WARC output.
- Multi-server gateway, worker and standby roles, with robots.txt, rate-limit and private-network guards.
Licensing and Update
PageSift is released under AGPL-3.0, with a separate commercial license offered for proprietary linking or private deployment. Version 1.2.0 adds optional, off-by-default access-barrier recovery with scoped sessions, validated proxy tunnels and a bounded wait for non-interactive challenges. Interactive CAPTCHAs are reported as needing a human, and no solver is included. The README states that standalone image-file OCR is not covered and that the tool is self-hosted rather than a managed cloud service, and it publishes its own benchmark comparisons against other tools.
Community Discussions
Be the first to start a conversation about PageSift
Share your experience with PageSift, ask questions, or help others learn from your insights.
Pricing
Open Source (AGPL-3.0)
Self-hosted pagesift core under AGPL-3.0, a free copyleft license.
- Self-hosted Rust binary with CLI, Firecrawl and Jina Reader compatible APIs, and MCP server
- Python, Node.js, Go, Java, C# and other bindings
- Licensed AGPL-3.0; a commercial license is available separately for proprietary linking or private deployment without AGPL obligations
Capabilities
Key Features
- URL to Markdown/JSON conversion with JavaScript rendering only when needed
- PDF, Office, e-book, email, archive and source-code parsing
- OCR for scanned PDF pages
- Firecrawl v1/v2 and Jina Reader compatible API
- MCP server over stdio or HTTP
- Schema-based structured extraction with selector repair
- Browser interaction sessions
- Agent endpoint using your own model with evidence checking
- Scheduled change monitoring with webhooks
- Query-focused crawling with robots.txt and rate limits
- WARC output and input
- Multi-server gateway, worker and standby roles