Photon
Fast Python web crawler designed for OSINT that extracts URLs, files, emails, keys, and DNS data.
At a Glance
Photon crawler for OSINT, self-hosted and licensed under GPL v3.0.
Engagement
Available On
Alternatives
Listed Oct 2026
About Photon
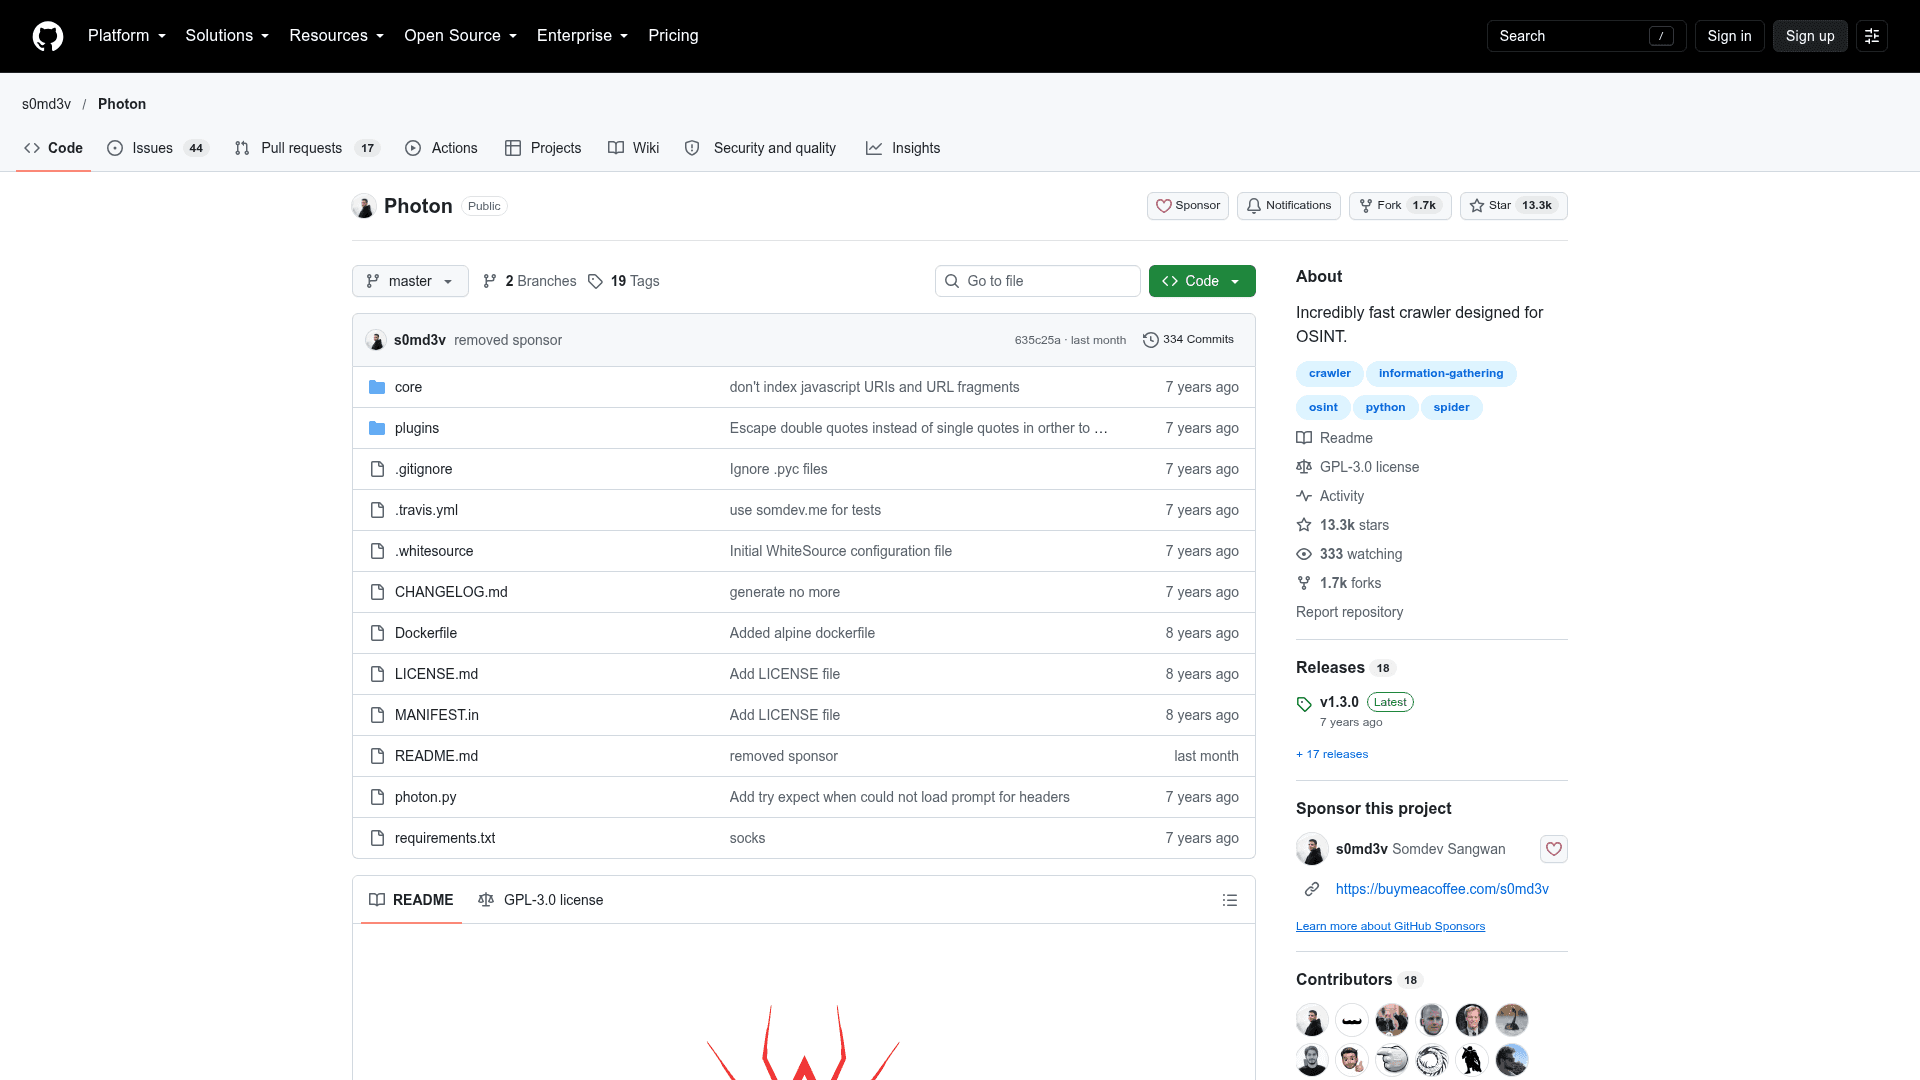
Photon is an open-source crawler for OSINT work, written in Python and published by s0md3v on GitHub under the GPL v3.0 license. It crawls a target site and pulls out URLs, files, intel such as emails and social media accounts, secret keys, and subdomain data. The latest release listed is v1.3.0, published 2019-04-05.
What It Is
Photon is a command-line information-gathering crawler. You point it at a target URL and it follows links, collecting data while it goes. Results are saved in an organized structure and can be exported as JSON.
What It Extracts
While crawling, Photon can collect in-scope and out-of-scope URLs, URLs with parameters, files (pdf, png, xml and others), and intel such as emails, social media accounts and Amazon buckets. It also finds auth/API keys and hashes, JavaScript files and the endpoints inside them, strings matching a custom regex, and subdomains with DNS-related data.
Controls and Plugins
Users can set timeout and delay, add seeds, and exclude URLs matching a regex. Plugins include wayback, which uses URLs archived by archive.org as seeds via the --wayback option, dnsdumpster for DNS data, and an exporter for formatted results. The README says Photon uses thread management to improve performance.
Setup Path
Photon can be run from source or through a lightweight Python-Alpine Docker image, which the README describes as 103 MB. Results can be read from the Docker volume or from a mounted output folder. The --update option installs updates without losing saved data.
Community Discussions
Be the first to start a conversation about Photon
Share your experience with Photon, ask questions, or help others learn from your insights.
Pricing
Open Source
Photon crawler for OSINT, self-hosted and licensed under GPL v3.0.
- Licensed under GPL v3.0 (OSI-approved)
- Extracts URLs, parameterized URLs, intel, files, secret keys, JS endpoints, subdomains and DNS data
- Export results as JSON
- Plugins: wayback, dnsdumpster, Exporter
- Docker image support
Capabilities
Key Features
- Crawls URLs, including those with parameters
- Extracts emails, social media accounts and Amazon buckets
- Finds files, secret keys and hashes
- Extracts JavaScript files and endpoints
- Custom regex matching
- Subdomain and DNS data extraction
- Wayback Machine seed URLs
- JSON export
- Configurable timeout, delay and URL exclusion
- Docker image
- Self-update option