EveryDev.ai
Subscribe
Home
Tools

5,901+ AI tools

  • Featured
  • Gems
  • Trending
  • New
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2972
  • Coding2248
  • Infrastructure1067
  • Projects818
  • MCP794
  • Research744
  • Analytics565
  • Marketing527
  • Design488
  • Testing476
  • Data442
  • Security412
  • Integration288
  • Communication284
  • Prompts283
  • Extensions238
  • Voice213
  • DevOps190
  • Commerce183
  • Web128
  • Learning123
  • Finance44
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. samir-vllm
    samir-vllm icon

    samir-vllm

    AI Infrastructure
    Featured

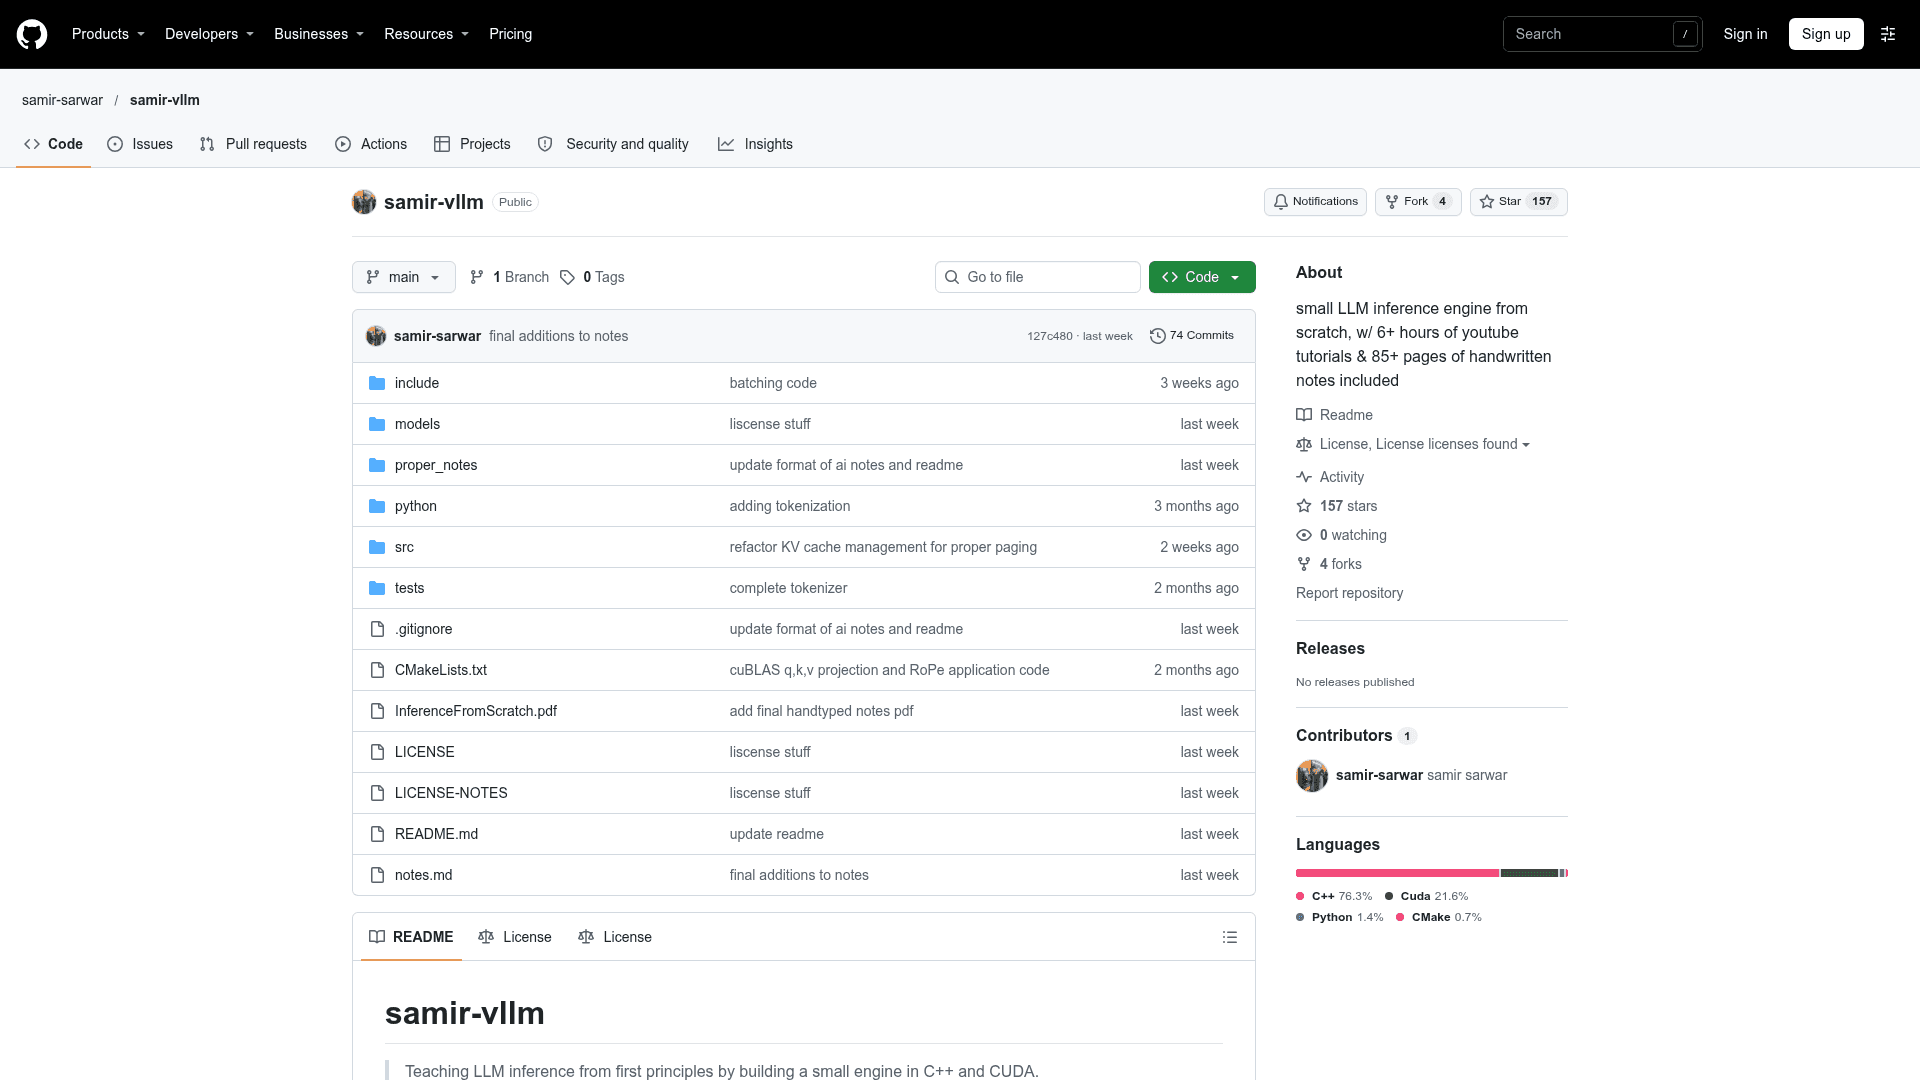
    A small LLM inference engine in C++ and CUDA that teaches inference from first principles with video tutorials and study notes.

    Visit Website

    At a Glance

    Pricing
    Open Source

    MIT-licensed engine source code; notes and Llama materials are excluded from MIT and carry separate terms.

    Engagement

    Available On

    API
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    AI InfrastructureAI TutorialsLocal Inference

    Alternatives

    PowerInferKTransformersWASTE — Weight-Aware Streaming Tensor Engine
    Developer
    samir sarwaruwaterloo computer engineering

    Listed Nov 2026

    About samir-vllm

    samir-vllm is an educational C++17/CUDA project by Samir Sarwar that builds a small LLM inference engine for Llama 3.2 1B Instruct. It pairs the source code with a video build series and handwritten notes covering what happens between a prompt and a generated token.

    What It Is

    The project is a learning-oriented inference engine that loads model weights, tokenizes prompts, and runs the transformer on an NVIDIA GPU. It walks through each stage of inference: SafeTensor weight loading, embedding gather, RMSNorm, RoPE, Q/K/V projections with cuBLAS, causal self-attention, the SwiGLU feed-forward network, decode with a KV cache, batching, and paged attention.

    How the engine works

    The engine reads model.safetensors directly and copies BF16 weights to GPU memory. A local BPE tokenizer handles Unicode, special tokens, and the Instruct chat format. Prefill runs all 16 layers, and a GPU argmax picks each next token using greedy generation. A shared paged KV cache stores 16-token pages with per-sequence block tables, and decode attention uses FP32 online softmax over cached pages.

    Batching and scope

    The command-line program accepts one or more prompts and a max_new_tokens value. It supports static batching and a continuous scheduler that admits queued requests according to page budgets, plus a --kv-cache-mib option and a --stats report. Model dimensions and the 2,048-token context are fixed. The README notes that greedy outputs may differ between individual and batched runs because of BF16 rounding.

    Learning materials and licensing

    The repository links to a video series of 6+ hours (Part 0 through a paged-attention finale), per-video study notes in Markdown and PDF, and an 80+ page handwritten notes PDF. The source code is MIT licensed, while the notes and handwritten materials are all rights reserved. Llama weights and tokenizer keep Meta's Llama 3.2 Community License.
    samir-vllm - 1

    Community Discussions

    Be the first to start a conversation about samir-vllm

    Share your experience with samir-vllm, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source (MIT engine)

    MIT-licensed engine source code; notes and Llama materials are excluded from MIT and carry separate terms.

    • Engine source in src/, include/, tests/, python/ plus CMakeLists.txt, .gitignore and README under MIT License
    • Notes (proper_notes/, notes.md, podLibraryInstall.md, handwritten notes, PDFs) are all rights reserved, not MIT; personal reading and study permitted
    • Bundled Llama 3.2 tokenizer and Llama weights are under Meta's Llama 3.2 Community License, excluded from MIT

    Capabilities

    Key Features

    • Direct SafeTensor weight loading to GPU
    • Local Unicode BPE tokenizer with Instruct chat format
    • CUDA kernels for embedding gather, RMSNorm and RoPE
    • cuBLAS Q/K/V projections
    • Dense causal prefill across 16 layers
    • Paged KV cache with block tables
    • Paged decode attention with FP32 online softmax
    • Static and continuous batching
    • Configurable KV cache size and stats reporting
    • Video series and handwritten study notes

    Integrations

    CUDA
    cuBLAS
    ICU
    nlohmann/json
    Llama 3.2 1B Instruct
    API Available
    View Docs

    Demo Video

    samir-vllm Demo Video
    Watch on YouTube

    Ratings & Reviews

    No ratings yet

    Be the first to rate samir-vllm and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    samir sarwar

    uwaterloo computer engineering

    Read more about samir sarwar
    WebsiteGitHubLinkedIn
    1 tool in directory

    Similar Tools

    PowerInfer icon

    PowerInfer

    Open-source CPU/GPU hybrid LLM inference engine that exploits activation locality to run large models on a single consumer-grade GPU.

    KTransformers icon

    KTransformers

    Open-source framework for CPU-GPU heterogeneous inference and fine-tuning of large MoE language models.

    WASTE — Weight-Aware Streaming Tensor Engine icon

    WASTE — Weight-Aware Streaming Tensor Engine

    An embeddable, dependency-free C inference engine that runs massive frontier models like Kimi K3 (2.78T parameters) on consumer hardware by streaming expert weights from NVMe storage.

    Browse all tools

    Related Topics

    AI Infrastructure

    Infrastructure designed for deploying and running AI models.

    589 tools

    AI Tutorials

    Step-by-step tutorials and hands-on guides for AI tools and frameworks.

    61 tools

    Local Inference

    Tools and platforms for running AI inference locally without cloud dependence.

    353 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions
    7views