Scry
An MCP server that lets AI agents run programmatic SQL queries over billions of internet documents including Reddit, Hacker News, arXiv, Wikipedia, and prediction markets.
At a Glance
Free non-commercial access with $5 of credit at signup, no card required.
Engagement
Available On
Alternatives
Listed Sep 2026
About Scry
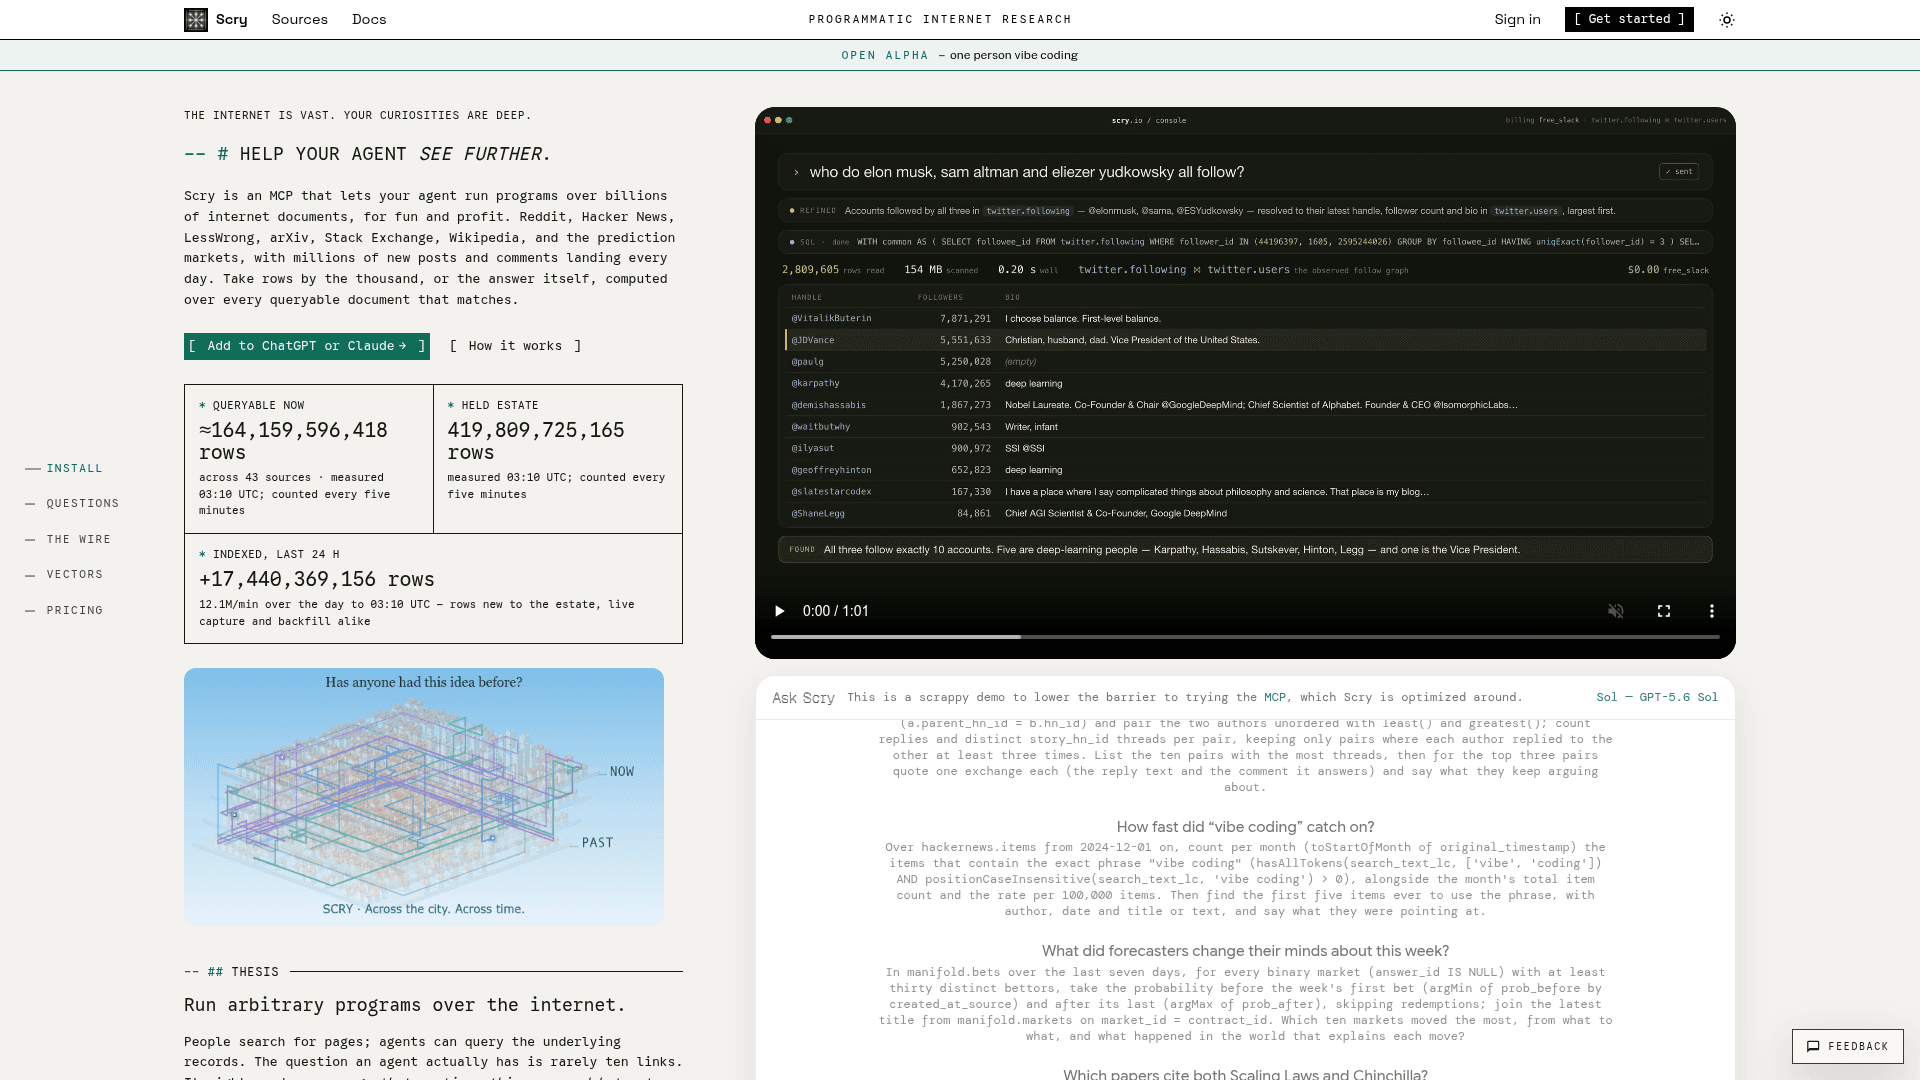
Scry is a programmatic internet research tool built as an MCP server, giving AI agents the ability to run structured SQL queries over hundreds of billions of indexed internet documents. Built by Unflatten and currently in open alpha, it connects to ChatGPT, Claude, Claude Code, Codex, Cursor, and any MCP-compatible client via a single URL: https://mcp.scry.io.
What It Is
Scry is an MCP-native data query engine that exposes the public internet as a queryable relational database. Rather than returning ten links like a search engine, Scry lets an agent write a bounded SQL statement — with time windows, joins, vector composition, and recursive graph walks — and get back thousands of rows with source-native identifiers and provenance fields. The homepage describes it as giving agents "Turing-complete search programs over the public record."
What's Queryable
Scry's vendor-published stats report approximately 164 billion queryable rows across 43 sources, with a "held estate" of over 419 billion rows (including sources under reviewed access). Key source families include:
- Social: Reddit posts and comments (near-census from 2005), Hacker News (since 2006, indexed within 15 minutes), Stack Exchange, Bluesky, Mastodon, LessWrong, EA Forum
- Writing & Web: Common Crawl index and pages, mailing lists (~34k lists), Wikipedia, Substack, web crawl pages
- Scholarship: OpenAlex works and citation graph, arXiv, PubMed, Crossref, patents, book passages
- Markets: Kalshi, Polymarket, and Manifold trades and markets
- Code: GitHub Archive events, Software Heritage, package registries, deps.dev dependency graph
- Records: SEC EDGAR filings, FEC transactions, Google Trends
The schema is live and self-describing via GET /v1/scry/schema, which returns each relation's columns, indexes, extent, and known coverage gaps.
How Agents Use It
Agents connect over MCP (one URL, OAuth on first use) or via the HTTP API with a bearer key. The recommended workflow is: call schema to read the live contract, pick a relation, write a bounded SQL statement with a LIMIT, and iterate from the returned rows. Key capabilities include:
- Scry SQL: A ClickHouse-dialect SQL with token-indexed text search (
hasAllTokens,hasAnyTokens), thescry_lexpredicate for full search grammar (exact phrases, exclusion, regex, proximity), and time-series aggregates - Vector helpers:
POST /v1/scry/embedmints a named vector from any text;scry_cosine_similarity,scry_contrast_axis_balanced,scry_centroid, andscry_vector_topk_distanceexpose linear embedding structure directly in queries - Fixpoint programs: A JSON program body on
POST /v1/scry/queryruns recursive graph walks (citation trees, reply threads, follow graphs) reading only the frontier at each depth - Rerank:
POST /v1/scry/rerankor thex-scry-rerankheader re-orders results by a natural-language directive using local models at no additional cost - Explain:
x-scry-explain: 1returns the query plan, index analysis, and a forecast (rows, bytes, seconds, memory) without running the statement
Performance and Benchmark Claims
The homepage publishes vendor-measured performance figures: the site states that on Google's DeepSearchQA benchmark (900 research questions, exact-set grading), an agent researching through Scry answered 71.8% fully correct, compared to a reported 66.1% for Google's Gemini Deep Research Agent on the same leaderboard. The site notes the same judge model and grading prompt were used, and links to a dedicated DeepSearchQA page with every question, grade, and tool-call transcript. Additional vendor-measured timings include: 0.86 seconds to scan all indexed Hacker News text (15.5 billion characters at 18 GB/s), 7 ms to count all posts containing "the" from the index, and a median of 98 ms across 65 of 71 canonical query constructs.
Deployment and Setup
Scry requires no local installation. The MCP server at https://mcp.scry.io is added as a custom connector in ChatGPT (developer mode), Claude.ai (Settings → Connectors), Claude Code (one CLI command), Codex, or Cursor. OAuth handles authentication on first use. For headless or CI environments, an API key from the dashboard can be passed as a bearer token. The x402 payment lane allows agents to run queries without an account at a per-second rate.
Current Status: Open Alpha
Scry is in open alpha, described on the site as "one person vibe coding." Individual accounts are self-serve. The site positions Scry as "public-benefit infrastructure, subsidized for independent noncommercial research and funded by commercial engagements." Sources under reviewed access (comprising the majority of the held estate) are not queryable by default and require contacting the team. Commercial use, large evaluations, custom source builds, and dataset engagements are handled through direct contact at hi@scry.io.
Community Discussions
Be the first to start a conversation about Scry
Share your experience with Scry, ask questions, or help others learn from your insights.
Pricing
Researcher
Free non-commercial access with $5 of credit at signup, no card required.
- $5 of credit at signup, no card
- API key and MCP
- Non-commercial use
Patron
$100/month becomes balance and rolls over. Non-commercial use.
- $100 a month becomes balance and rolls over
- Non-commercial use
Team
Commercial use with dedicated capacity and custom source builds.
- Commercial use
- Dedicated capacity
- Custom source builds
Agents
x402 pay-per-second lane for agents without an account. The declared time box is the charge.
- x402, no account required
- The declared time box is the charge
Capabilities
Key Features
- MCP server at https://mcp.scry.io
- SQL queries over billions of internet documents
- Token-indexed text search with hasAllTokens and hasAnyTokens
- scry_lex predicate for full search grammar (exact phrases, exclusion, regex, proximity)
- Vector embedding helpers: mint, add, subtract, project, and rank
- scry_contrast_axis_balanced for semantic axis ranking
- scry_cosine_similarity and scry_vector_topk_distance
- Fixpoint graph walk programs for citation trees and reply threads
- Recursive SQL with WITH RECURSIVE support
- Live schema discovery via GET /v1/scry/schema
- Rerank endpoint and x-scry-rerank header
- Explain mode with query plan and cost forecast
- x402 payment lane for accountless agent queries
- Sources: Reddit, Hacker News, Stack Exchange, Bluesky, Mastodon, LessWrong, arXiv, OpenAlex, Wikipedia, Common Crawl, Manifold, Kalshi, Polymarket, SEC EDGAR, GitHub Archive, and more
- Near-real-time indexing (Hacker News within 15 minutes)
- Source-native identifiers and provenance fields in every row
- HTTP API with bearer key authentication
- OAuth sign-in via MCP
- Compatible with ChatGPT, Claude, Claude Code, Codex, Cursor, and any MCP client