
spinf
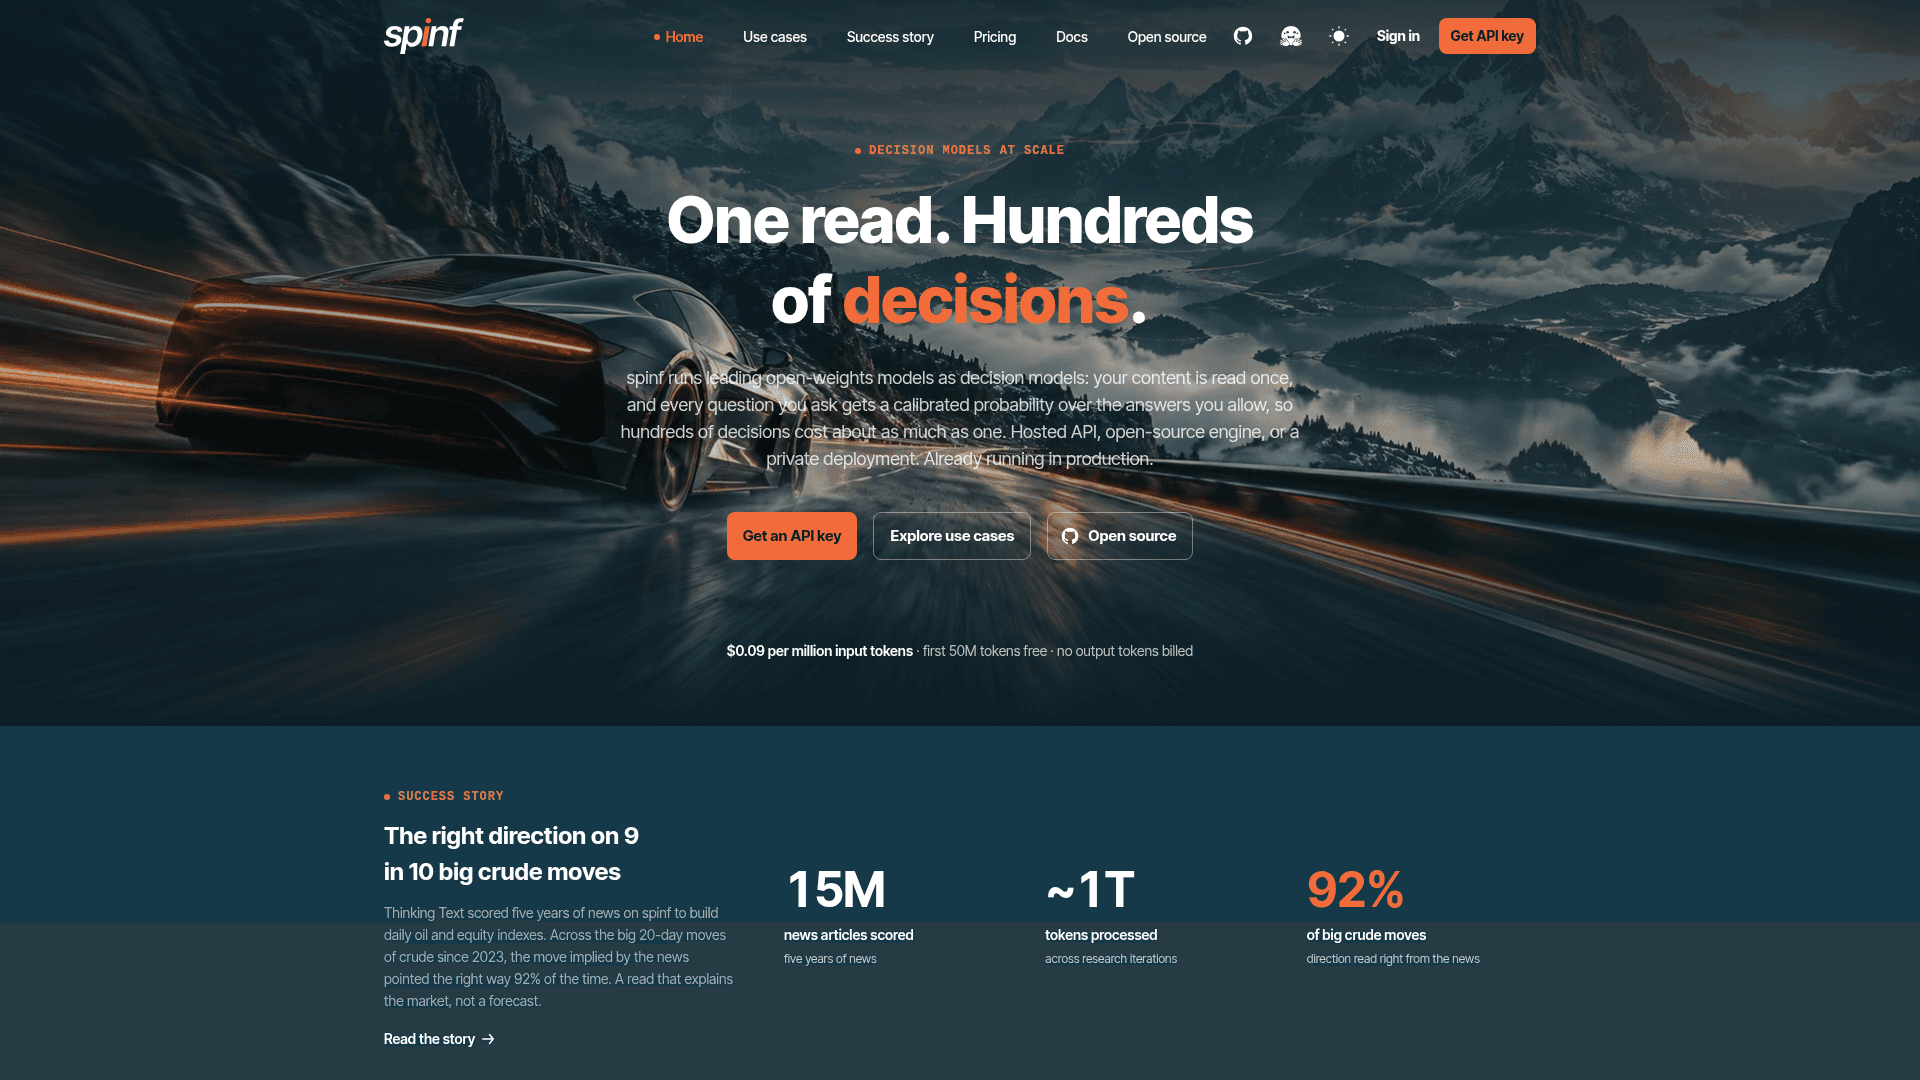
Decision-model inference API and open-source engine that reads content once and returns calibrated probabilities for many questions.
At a Glance
Open-source inference engine under Apache 2.0, free to run on your own 24 GB NVIDIA GPU; same request/response as the hosted API.
Engagement
Available On
Listed Nov 2026
About spinf
spinf, made by spinf Inc. in San Francisco, runs open-weights language models as decision models: content is read once and every question returns a probability over the answers you allow. It is offered as a hosted API (currently in beta), as the open-source spinf-serve engine under Apache 2.0, and as private deployments.
What It Is
spinf is a bulk classification and scoring service. A question is written as a template that ends where the answer goes, with a list of answers to score. The response gives a probability for each answer rather than generated text, so classification, scoring and decisions can be run over many documents. The spinf-serve engine exposes an OpenAI-compatible API and uses the same request and response format as the hosted service.
How scoring works
Each question returns three numbers: p (probability of an answer), residual (probability that went to words outside your options) and floor_p (the same answer scored on empty content, so p minus floor_p shows what the content added). Placeholders in a template expand one question into a grid, and many contents can be sent in one call. Extraction slots can decode text, numbers and amounts from the same read. Billing covers input tokens only, with no charge for the scores returned, according to the vendor.
Use cases and prompt packs
The site lists news analysis, survey and review analysis, content classification, content moderation, ticket and message routing, and prompt-injection detection. Prompt packs are ready-made, calibrated question sets, such as a moderation pack, that can run in the same call as your own questions. The vendor presents a case study in which Thinking Text built daily oil and equity news indexes on spinf.
Running it yourself
spinf-serve installs with pip or Docker and runs on one 24 GB NVIDIA GPU on Linux, with fp8 tensor cores (Ada, Hopper or Blackwell) and CUDA 13 on Python 3.12; Ampere cards use int8 weights. Published checkpoints include Gemma 4 12B and 31B, Qwen3.8-27B and a Perplexity decision model. Some models also read images, audio or video frames. The README reports its own benchmark against vLLM on one RTX 4090.
Community Discussions
Be the first to start a conversation about spinf
Share your experience with spinf, ask questions, or help others learn from your insights.
Pricing
spinf-serve (self-hosted, open source)
Open-source inference engine under Apache 2.0, free to run on your own 24 GB NVIDIA GPU; same request/response as the hosted API.
- Apache License 2.0
- Runs on one 24 GB NVIDIA GPU
- OpenAI-compatible API
- Decision mode, prompt packs, extraction and media
- Hardware and hosting costs are external
Hosted API - spinf 12B
Hosted usage-based API billed on input tokens only; no output charge. New accounts start with $4.50 free credit (50M tokens).
- $0.09 / 1M input tokens
- No output token charge
- Minimum 1,000 tokens billed per call
- New accounts start with $4.50 of free credit (50M tokens)
- Content up to 4,096 tokens, questions up to 256 tokens
- Concurrency by credit balance: one concurrent request per $100 of credit
Hosted API - spinf 31B
Larger Gemma 4 31B model, available on request.
- Available on request
- Model id spinf-31b
Capabilities
Key Features
- Reads content once and answers many questions in one pass
- Calibrated probabilities with residual and empty-content floor
- Question templates with placeholders
- Extraction of text, numbers and amounts
- Prompt packs such as content moderation
- Image, audio and video frame input on supported models
- Bit-identical scores regardless of batch composition on fp8 checkpoints
- OpenAI-compatible API
- Hosted API, self-hosted engine and private deployments
- Reserved real-time endpoints