Strata
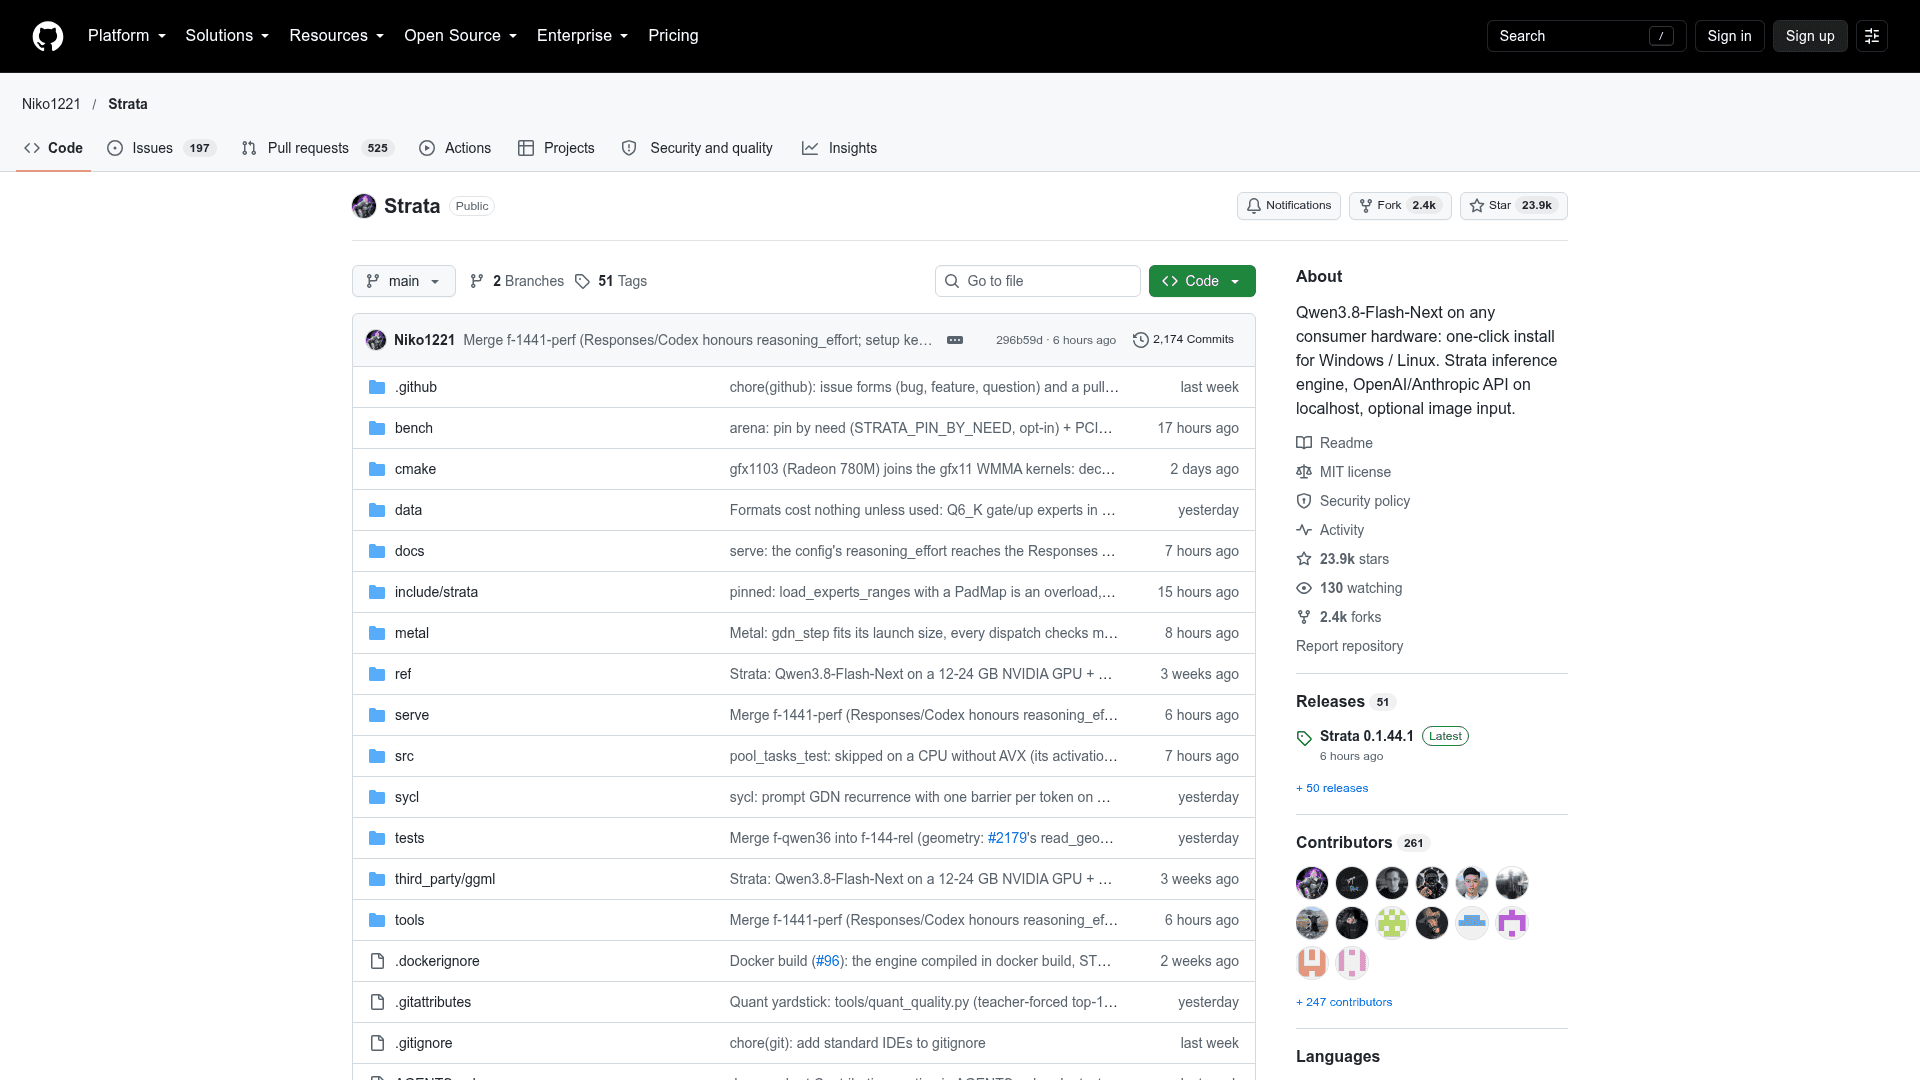
Open-source inference engine that runs the Qwen3.8-Flash-Next model locally on consumer NVIDIA or AMD GPUs with an OpenAI/Anthropic-compatible local API.
At a Glance
Strata is free and open source under the MIT License. A few parts and every model have their own licenses. Optional donations via Buy Me A Coffee.
Engagement
Available On
Alternatives
Listed Oct 2026
About Strata
Strata is an open-source local inference engine from Niko1221 that runs Qwen3.8-Flash-Next, a large AI model normally needing a server, on a gaming PC with a 12 GB or larger NVIDIA or AMD graphics card. It installs with a one-click script on Windows or Linux and serves a chat app and an API on localhost. The README states that nothing leaves the PC.
What It Is
Strata is a local LLM runtime plus installer. It downloads a compressed build of the model, starts an engine tuned to your GPU, and exposes a browser app at 127.0.0.1:8080 with Chat, a live Monitor of the model and GPU/CPU/RAM, and an About page. It can chat, write code, and read images when image input is enabled.
How It Fits the Model on a Gaming PC
The README explains that the model is a mixture of 24,576 small experts, of which 10 are used per token. The busiest experts stay on the graphics card, all of them sit in RAM, the processor works on the rest, and the SSD holds a lookup table. A small helper model guesses upcoming words and the large model verifies them in one pass, which the README says gives answers 1.6-1.8x sooner. Long prompts are read in chunks of up to 8,192 tokens.
Connecting Apps and Coding Agents
Strata exposes an OpenAI-compatible endpoint at http://127.0.0.1:8080/v1, an Anthropic-style /v1/messages endpoint (usable with Claude Code via ANTHROPIC_BASE_URL), and a /v1/responses endpoint for Codex CLI. Reasoning effort can be set to off, low, medium or high. An MCP server lets AI tools install, start and stop Strata, and a docs/AI_SETUP.md guide lets an AI coding assistant perform the setup. Remote access from another device is possible with a host flag and an API key.
Model Sizes and Hardware
The installer recommends a model size by RAM, from the Coder variant for 32 GB up to larger quantizations such as IQ3_S or Unsloth builds for 96 GB or more. The README lists about 80 GB of free disk and measured speeds on an RTX 5070 and an RX 9070 XT, for example 94 tokens/s for answers with Q2_0 on the RTX 5070. Experimental paths exist for older GPUs, Intel Arc, Apple Silicon Macs, and Strix Halo. A BENCH script measures speed on your own machine.
Community Discussions
Be the first to start a conversation about Strata
Share your experience with Strata, ask questions, or help others learn from your insights.
Pricing
Open Source
Strata is free and open source under the MIT License. A few parts and every model have their own licenses. Optional donations via Buy Me A Coffee.
- MIT License for Strata
- Runs Qwen3.8-Flash-Next locally on NVIDIA or AMD GPU (12 GB+ VRAM)
- Windows or Linux
- OpenAI/Anthropic-compatible API on localhost
- Optional image input
Capabilities
Key Features
- Runs Qwen3.8-Flash-Next locally on 12 GB+ NVIDIA or AMD GPUs
- One-click installer for Windows and Linux
- OpenAI-compatible, Anthropic Messages and Responses API endpoints on localhost
- Browser app with Chat and live hardware Monitor
- Optional image input
- Selectable reasoning effort (off, low, medium, high)
- Multiple model sizes and quantizations chosen by available RAM
- Speculative decoding (guess and check) for faster answers
- Multi-GPU support
- MCP server for AI-driven install and control
- Built-in benchmark script
- Optional parallel request batching