
SWE-CoWork
A benchmark that evaluates coding agents taking over engineering assignments inside simulated software organizations.
At a Glance
Download the benchmark and evaluation tools to run on your own infrastructure. Model API usage and compute costs are separate. Task assets retain their upstream licenses.
Engagement
Available On
Alternatives
Listed Nov 2026
About SWE-CoWork
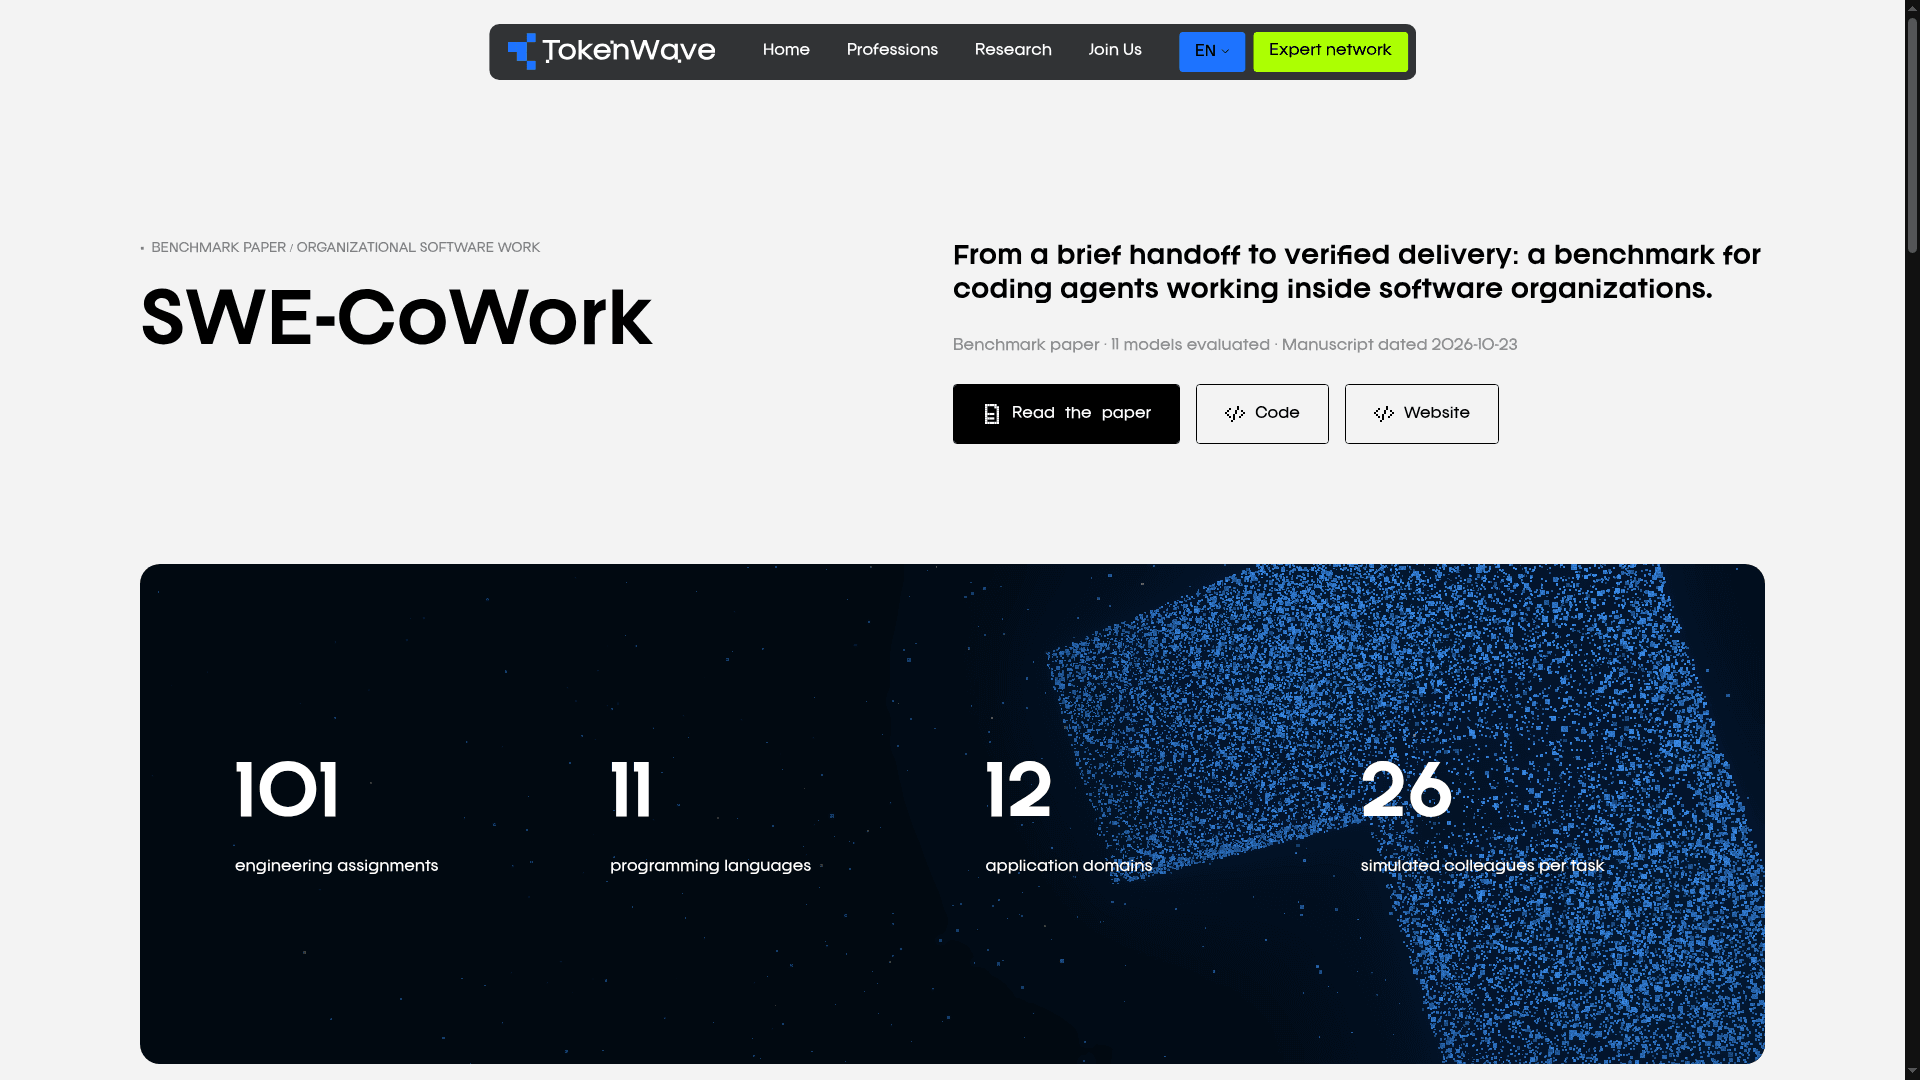
SWE-CoWork is a benchmark from TokenWave AI that tests whether a coding agent can inherit an ongoing engineering assignment and finish it as a dependable teammate. The agent receives a short handoff, a real repository, and access to a simulated workplace, then must recover requirements, implement changes, and verify delivery. The project page and README describe 101 assignments across 11 programming languages and 12 application domains.
What It Is
SWE-CoWork is an evaluation suite for coding agents rather than an agent itself. Instead of a fully specified issue, each task gives the agent a team note, a repository, and workplace records. Per the README, 82% of requirements are held only by simulated colleagues, so the agent has to find the right people and ask them.
How a Task Works
The agent reads a handoff at /task/README.md and works in the repository at /app/code. It searches board cards, design documents, reviews, artifacts, and chat threads through a single MCP server exposing 17 workplace tools plus a terminal. LLM-simulated colleagues answer questions from their private knowledge. The agent writes /app/SOLUTION.md, and the harness replays its changes in a fresh grading container and runs hidden tests, with eight hours allowed per assignment.
Scoring and Reported Results
Fail-to-pass tests measure newly required behavior and pass-to-pass tests measure preserved behavior. A task counts as resolved only when every test node passes. The manuscript reports results for eleven models; the two highest F2P scores, Claude-Opus-5.5 at 63.84% and GPT-6 Astra at 62.91%, resolve 6.93% and 7.92% of tasks. These are manuscript-reported results that were not independently reproduced. A paired Oracle-Spec condition that supplies the full requirements up front was evaluated for two models.
Setup Path
The repository ships a ./cowork CLI plus Claude Code and Codex campaign harnesses. It needs a Linux/amd64 host with Docker Engine, Python 3.10+, and a Responses API endpoint for the colleague model. Two tasks additionally require a root controller, systemd, cgroup v2, and runc.
Community Discussions
Be the first to start a conversation about SWE-CoWork
Share your experience with SWE-CoWork, ask questions, or help others learn from your insights.
Pricing
Public Benchmark
Download the benchmark and evaluation tools to run on your own infrastructure. Model API usage and compute costs are separate. Task assets retain their upstream licenses.
- 101 software engineering assignments
- Simulated workplace with colleague interactions
- Containerized evaluation environments
- Tools for running tasks and grading results
Capabilities
Key Features
- 101 engineering assignments across 101 repositories, 11 languages, and 12 domains
- 26 simulated colleagues per assignment with bounded knowledge
- 17 workplace tools exposed through one MCP server
- Hidden fail-to-pass and pass-to-pass test grading
- Eight-hour budget per assignment with digest-pinned container images
- Claude Code and Codex campaign harnesses
- Oracle-Spec condition providing full requirements up front
- Baseline and reference-solution validation controls