Xinference
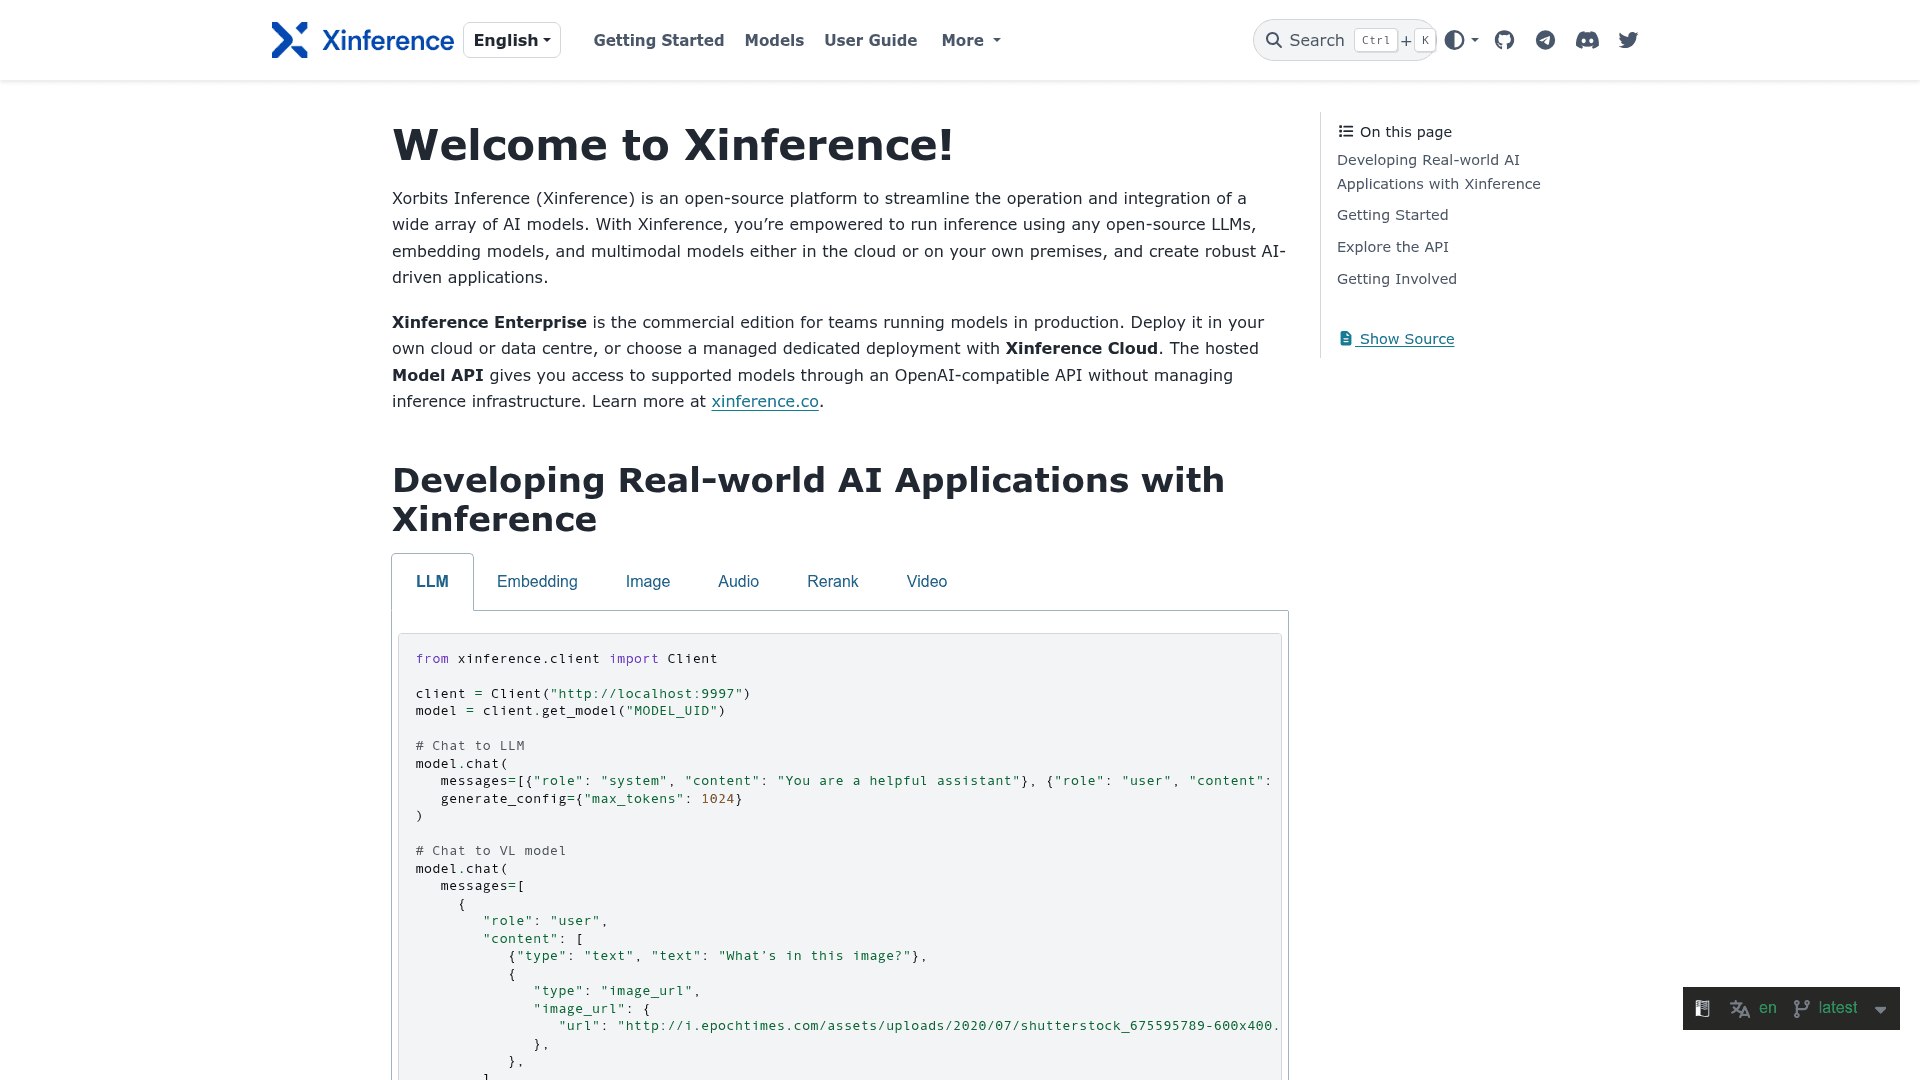
Open-source platform for serving LLM, embedding, image, audio, video and multimodal models through a unified OpenAI-compatible API.
At a Glance
Self-hosted Xinference core under the Apache License 2.0; run models on your own cloud, on-prem, or laptop.
Engagement
Available On
Listed Oct 2026
About Xinference
Xorbits Inference (Xinference) is an open-source platform from Xorbits that runs open-source language, embedding, speech, image, video and multimodal models in the cloud, on-premises or on a laptop. It exposes them through one OpenAI-compatible API, so applications can swap in different models with minimal code changes. The latest release listed on GitHub is v4.0.0, and the project is licensed under Apache 2.0.
What It Is
Xinference is a model-serving layer. You install it with pip, a one-command installer, Docker or Helm on Kubernetes, start a server, and launch built-in or custom models. Applications then talk to those models through the OpenAI-compatible RESTful API (including function calling), RPC, a CLI or a web UI.
Models and Abilities
The documentation covers chat and generation, tool calling, embeddings, rerank, image generation, multimodal input, audio (speech to text and text to speech), video generation, experimental world models, and traditional ML models. Users can also register their own model weights and turn them into an API.
Deployment and Performance
The README describes use of heterogeneous hardware (GPUs and CPUs) and distributed inference across workers or machines. Release highlights include automatic batching of concurrent requests, a maintained llama.cpp Python binding (Xllamacpp), shared KV cache across vLLM replicas, and, in 4.0.0, multi-engine Xavier, heterogeneous P/D and runtime model reconfiguration.
Ecosystem and Editions
Xinference integrates with LangChain, LlamaIndex, Dify, FastGPT, RAGFlow, MaxKB, Chatbox and the Xagent agent platform. A commercial Xinference Enterprise edition, Xinference Cloud managed deployments and a hosted Model API are offered alongside the community edition.
Community Discussions
Be the first to start a conversation about Xinference
Share your experience with Xinference, ask questions, or help others learn from your insights.
Pricing
Open Source (Self-hosted)
Self-hosted Xinference core under the Apache License 2.0; run models on your own cloud, on-prem, or laptop.
- Apache License 2.0
- Self-hosted deployment
- Serve LLM, embedding, speech, image, rerank, video and multimodal models
- OpenAI-compatible API
Capabilities
Key Features
- OpenAI-compatible RESTful API with function calling
- Serves LLM, embedding, rerank, image, audio, video and multimodal models
- Single-command model deployment
- Custom model registration
- Distributed multi-node inference
- Heterogeneous GPU/CPU hardware utilization
- Automatic batching of concurrent requests
- CLI, RPC and web UI interfaces
- Docker and Kubernetes Helm deployment