EveryDev.ai
Subscribe
Home
Tools

4,691+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents3426
  • Coding2391
  • Infrastructure1055
  • Projects732
  • Marketing662
  • Research612
  • MCP593
  • Analytics538
  • Design533
  • Testing420
  • Security410
  • Data358
  • Prompts260
  • Integration256
  • Communication250
  • Extensions222
  • Voice201
  • Learning193
  • Commerce173
  • DevOps161
  • Web122
  • Finance36
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai © 2026
    1. Home
    2. Tools
    3. BigCode Evaluation Harness
    BigCode Evaluation Harness icon

    BigCode Evaluation Harness

    LLM Evaluations
    Featured

    A framework for evaluating autoregressive code generation language models on a range of code benchmarks.

    Visit Website

    At a Glance

    Pricing
    Open Source

    Self-hosted evaluation framework released under the Apache License 2.0.

    Engagement

    Available On

    CLI
    Linux
    macOS

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    LLM EvaluationsAutomated TestingAI Development Libraries

    Alternatives

    ReviewBenchBridgeBenchInspect AI
    Developer
    BigCode ProjectNo headquarters identified; BigCode is a distributed community research collaboration jointly led by Hugging Face and ServiceNow.Est. 2022

    Listed Oct 2026

    About BigCode Evaluation Harness

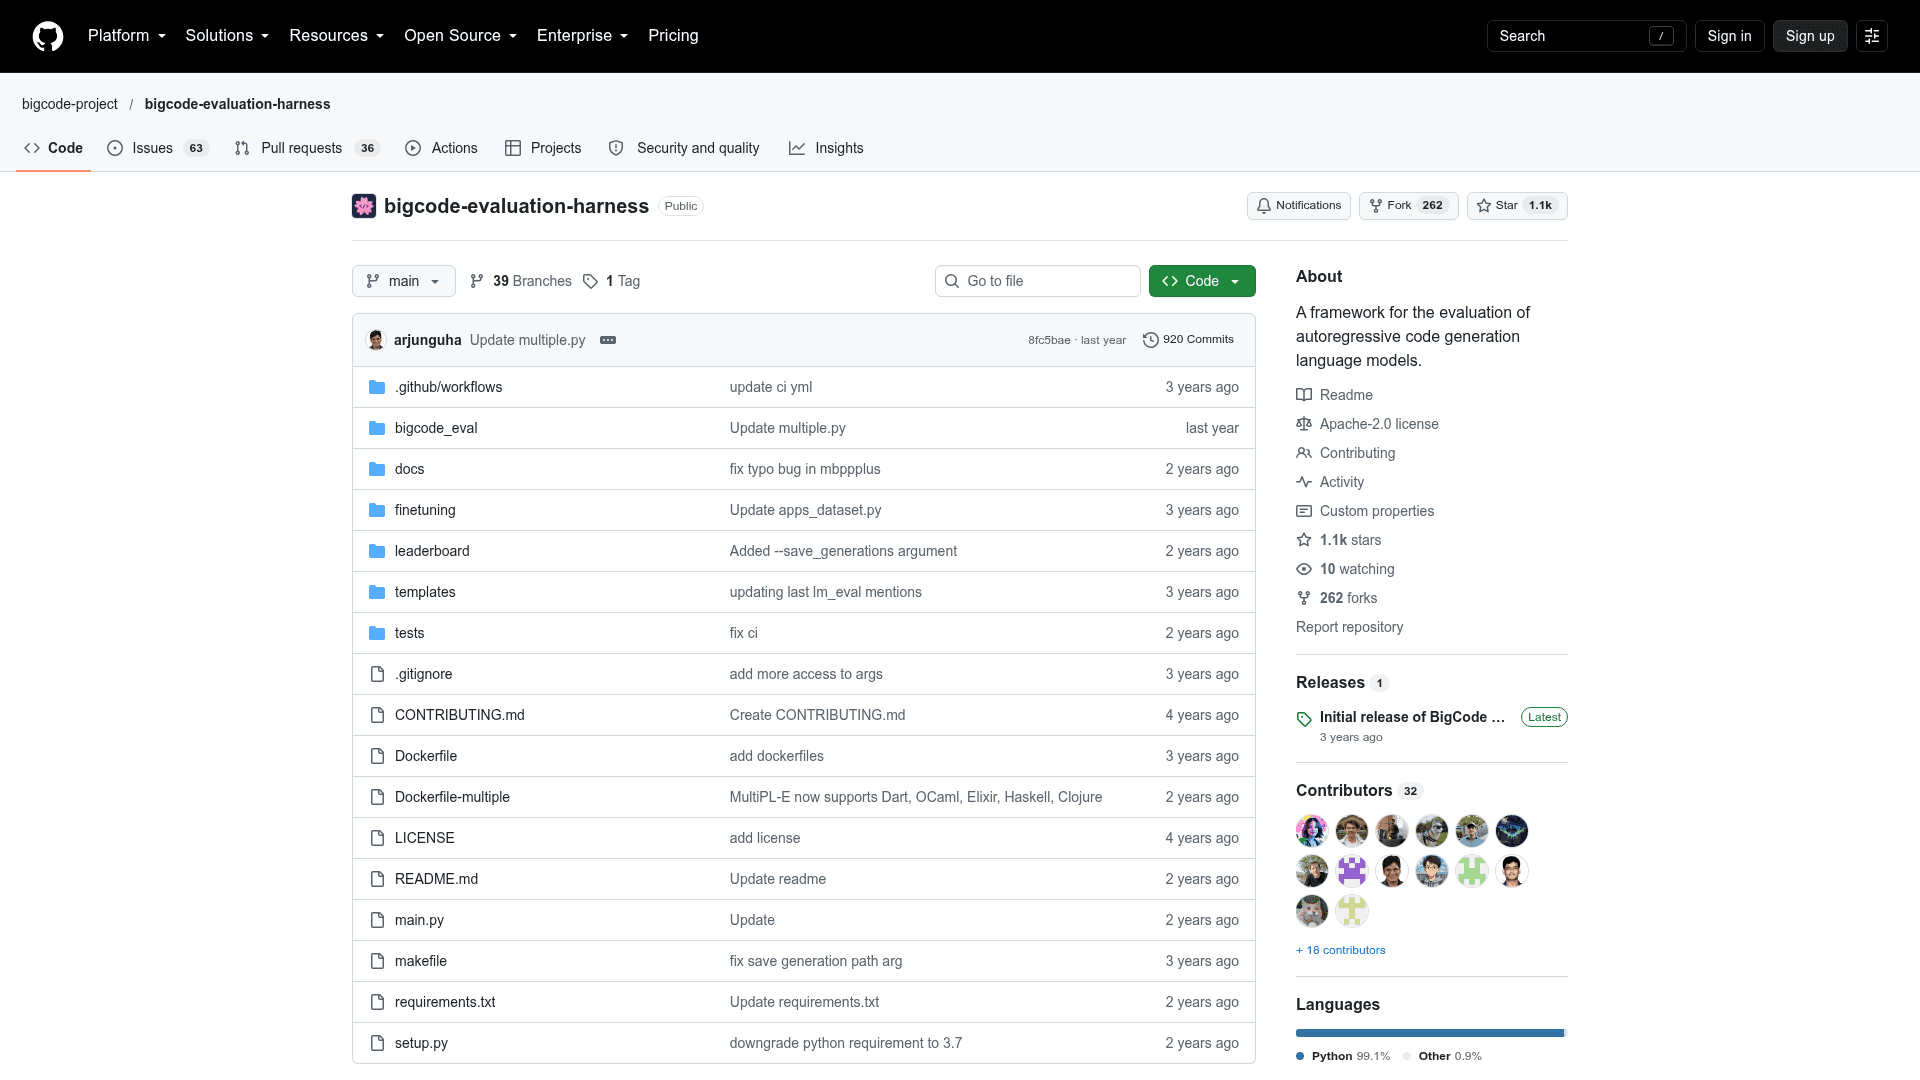
    BigCode Evaluation Harness is an open-source Python framework from the bigcode-project organization for evaluating autoregressive code generation models. It is inspired by EleutherAI's lm-evaluation-harness and runs Hugging Face hub models against code benchmarks, generating solutions and optionally executing them against unit tests.

    What It Is

    The harness is a command-line evaluation framework. Users point it at a model and one or more benchmark tasks, and it generates code or text completions, post-processes them, and scores them. Any autoregressive model on the Hugging Face hub can be used, though the README recommends models trained on code such as SantaCoder, InCoder and CodeGen.

    Supported Tasks

    The README lists Python tasks with unit tests (HumanEval, HumanEval+, InstructHumanEval, APPS, MBPP, MBPP+, DS-1000) in completion and fill-in-the-middle modes. It also covers HumanEvalPack, MultiPL-E (HumanEval translated into 18 languages), Recode for robustness, PAL for GSM8K and GSM-HARD math problems, CodeXGLUE code-to-text, CoNaLa, Concode, and three classification tasks. SantaCoder-FIM and Mercury, which measures computational efficiency, are also included.

    Workflow and Execution Safety

    Generation and evaluation can run together, or separately with generation-only and evaluation-only modes. This lets users generate on GPUs and execute the code on CPU machines or in Docker containers. Code execution is off by default and must be enabled with a flag. Multi-GPU generation uses accelerate, and models can be loaded at reduced precision or in 8-bit or 4-bit. Dockerfiles are provided, including one with the extra dependencies MultiPL-E needs. Contributors can add new tasks by following the guide in the docs.
    BigCode Evaluation Harness - 1

    Community Discussions

    Be the first to start a conversation about BigCode Evaluation Harness

    Share your experience with BigCode Evaluation Harness, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    Self-hosted evaluation framework released under the Apache License 2.0.

    • Apache License 2.0
    • Multi-GPU text generation with accelerate
    • Dockerfiles for evaluating on Docker containers
    • Code generation benchmarks including HumanEval, MBPP, APPS and MultiPL-E

    Capabilities

    Key Features

    • Evaluates any autoregressive Hugging Face hub model
    • Multi-GPU text generation with accelerate
    • Docker images for sandboxed code execution
    • Generation-only and evaluation-only modes
    • Python benchmarks with unit tests (HumanEval, MBPP, APPS, DS-1000)
    • MultiPL-E multilingual evaluation
    • Fill-in-the-middle evaluation tasks
    • Code-to-text, classification and robustness tasks
    • 8-bit and 4-bit model loading
    • Extensible with new task implementations

    Integrations

    Hugging Face Hub
    accelerate
    Docker
    PyTorch
    bitsandbytes

    Ratings & Reviews

    No ratings yet

    Be the first to rate BigCode Evaluation Harness and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    BigCode Project

    BigCode Project is an open scientific collaboration run by Hugging Face and ServiceNow Research, focused on open and responsible development of LLMs for code.

    Founded 2022
    No headquarters identified; BigCode is a distributed community research collaboration jointly led by Hugging Face and ServiceNow.
    Read more about BigCode Project
    WebsiteGitHubX / Twitter
    1 tool in directory

    Similar Tools

    ReviewBench icon

    ReviewBench

    An open, reproducible benchmark and leaderboard for evaluating AI code review agents on real-world pull requests.

    BridgeBench icon

    BridgeBench

    BridgeBench ranks AI coding models across UI generation, security, refactoring, hallucination, debugging, and speed benchmarks.

    Inspect AI icon

    Inspect AI

    An open-source Python framework for large language model evaluations developed by the UK AI Security Institute, supporting agentic tasks, tool use, multi-turn dialog, and 200+ pre-built benchmarks.

    Browse all tools

    Related Topics

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    172 tools

    Automated Testing

    AI-powered platforms that automate end-to-end testing processes with intelligent test case generation, execution, and reporting for faster, more reliable software delivery.

    171 tools

    AI Development Libraries

    Programming libraries and frameworks that provide machine learning capabilities, model integration, and AI functionality for developers.

    395 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions