
Can I Run AI
Free browser tool that estimates which open-weight LLMs your PC, GPU, or Mac can run locally, including memory, quantization, context, and speed.
At a Glance
Free browser-based local LLM compatibility checker; no account or install required.
Engagement
Available On
Alternatives
Listed Nov 2026
About Can I Run AI
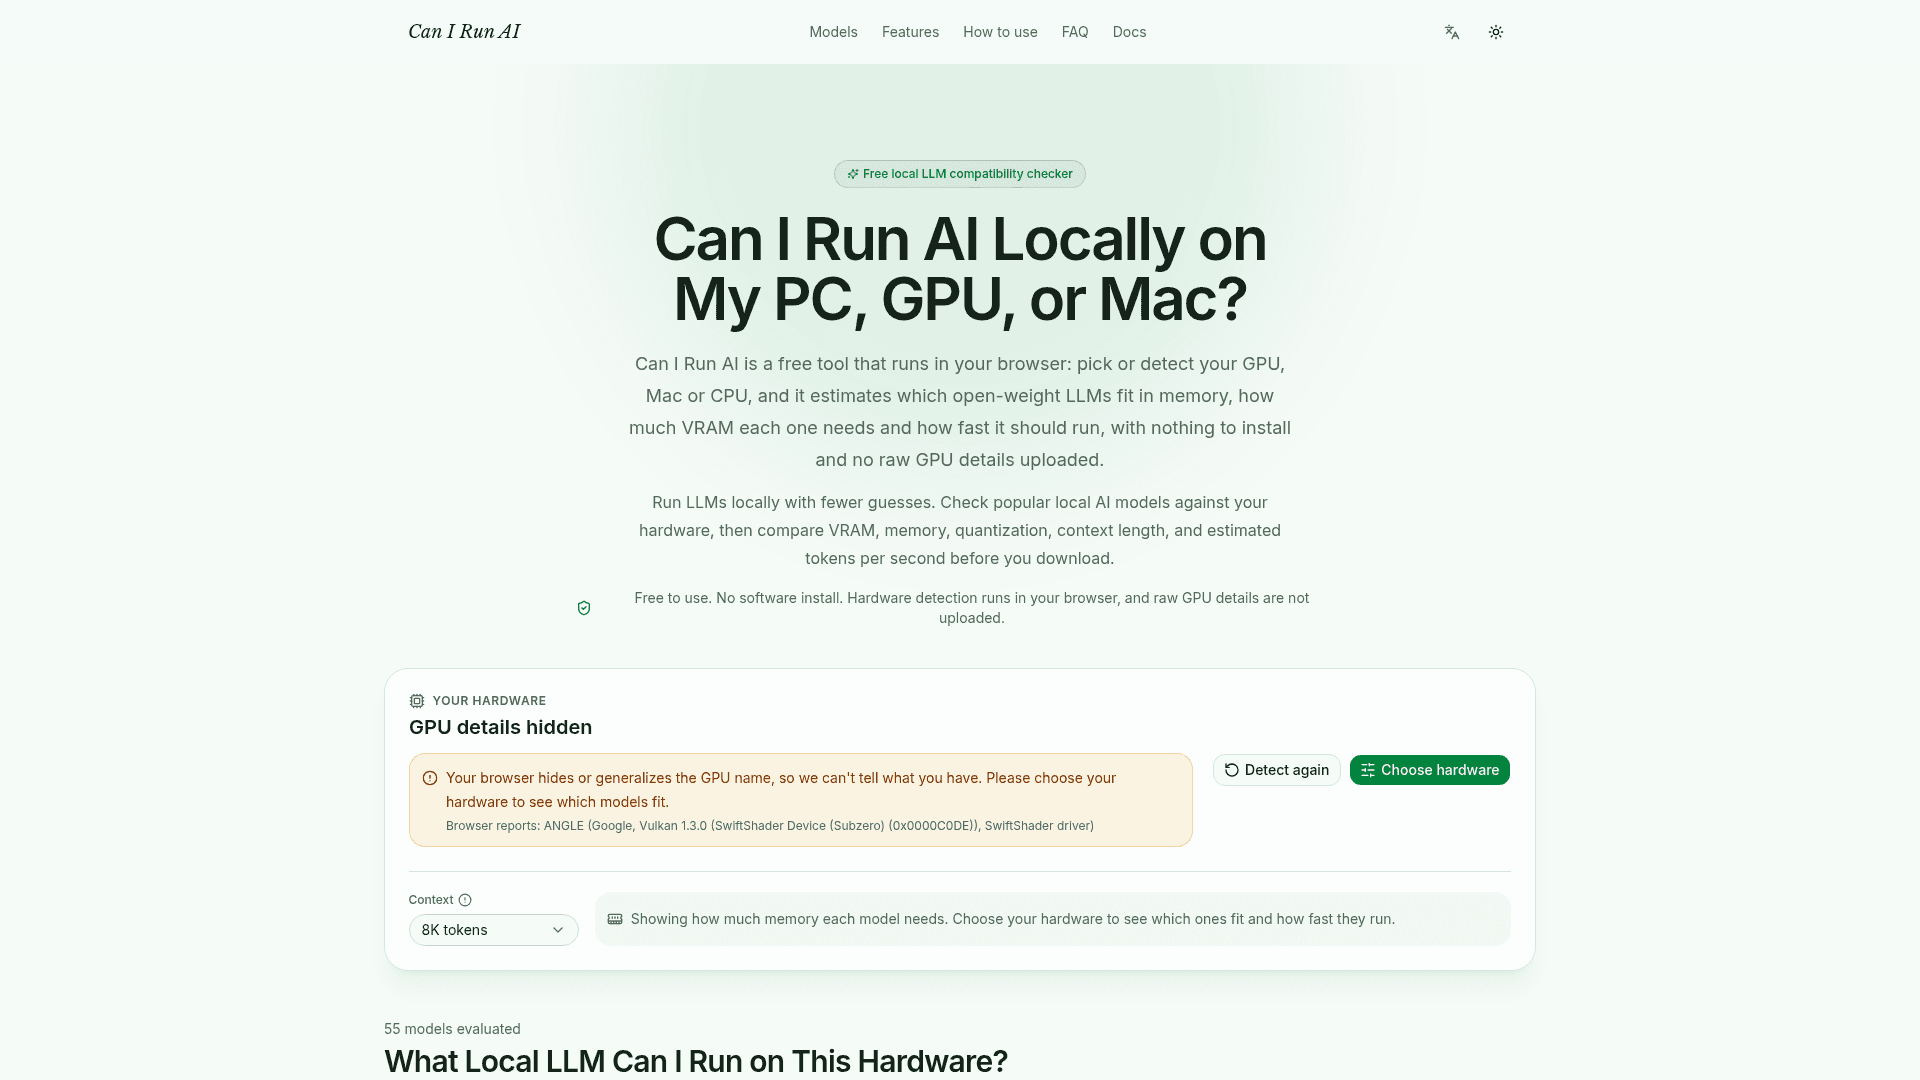
Can I Run AI is a free website that estimates which open-weight LLMs a computer can run locally. Users pick or detect a GPU, Mac, or CPU, and the checker returns a fit verdict, memory estimate, and expected speed range for each model in its catalog. It runs in the browser without an account or install, and the site states it never downloads or runs a model itself.
What It Is
It is a local LLM compatibility checker and VRAM calculator. Hardware is detected through WebGPU or WebGL in the browser, or chosen from a profile list, or entered manually (accelerator memory, system memory, bandwidth). The site says raw GPU adapter details are not uploaded. The catalog lists 55 open-weight text-generation models from 12 publishers, including Llama, Qwen, Gemma, DeepSeek R1 distills, Mistral, Phi, and GPT-OSS.
How the Estimates Work
Memory is the sum of model weights, a KV cache sized from each model's architecture and the selected context, and runtime overhead. It is compared with usable memory for the hardware type: discrete GPU VRAM, Apple Silicon unified memory, or system RAM for CPU-only setups. Results are labelled runs comfortably, tight fit, runs with offload, or won't fit. Speed is a tokens-per-second range derived from memory bandwidth, and the docs state it is a planning estimate rather than a benchmark.
Quantization and Runtimes
The checker covers Q4_K_M, Q5_K_M, Q8_0, BF16, FP8, and NVFP4. FP8 and NVFP4 are disabled with a stated reason on hardware that lacks the required NVIDIA architecture. For models that fit, the detail view lists copyable commands for Ollama, llama.cpp, LM Studio, and MLX on a Mac.
Evidence and Rankings
Each model records its source URL, retrieval date, and confidence, favoring official model cards. Where an exact model-version match exists, the list also shows an open-source rank from the public Arena Text Leaderboard dataset. Shared results freeze the catalog version used when the link was created.
Community Discussions
Be the first to start a conversation about Can I Run AI
Share your experience with Can I Run AI, ask questions, or help others learn from your insights.
Pricing
Free
Free browser-based local LLM compatibility checker; no account or install required.
- Estimates which open-weight LLMs fit in memory
- VRAM, quantization, context length and estimated tokens per second
- Hardware detection runs in browser; raw GPU details not uploaded
- No account or software install
- 55 models from 12 publishers
Capabilities
Key Features
- Browser-based GPU, Mac, and CPU hardware detection
- Manual hardware profiles and custom memory and bandwidth values
- Fit verdicts: runs comfortably, tight fit, runs with offload, won't fit
- Memory estimate covering weights, KV cache, and runtime overhead
- Quantization options: Q4_K_M, Q5_K_M, Q8_0, BF16, FP8, NVFP4
- Estimated tokens-per-second range
- Context length selection and longest-fitting-context display
- Catalog of 55 open-weight text-generation models
- Copyable Ollama, llama.cpp, LM Studio, and MLX commands
- Arena open-source ranking for exactly matched models
- Shareable results with frozen catalog and engine versions
- Interface in six languages