Compute:Arena
Community-driven benchmark leaderboard for local AI models on edge hardware, with a CLI tool to run, sign, and submit throughput results.
At a Glance
About Compute:Arena
Compute:Arena is a community leaderboard of throughput benchmarks for AI models running on local edge hardware, operated by Base Compute Pty. Ltd. Every result on the leaderboard comes from a cryptographically signed report produced on community-owned hardware, browsable by model, quantization level, and chip. The CLI client is open source under Apache-2.0 and written in Rust.
What It Is
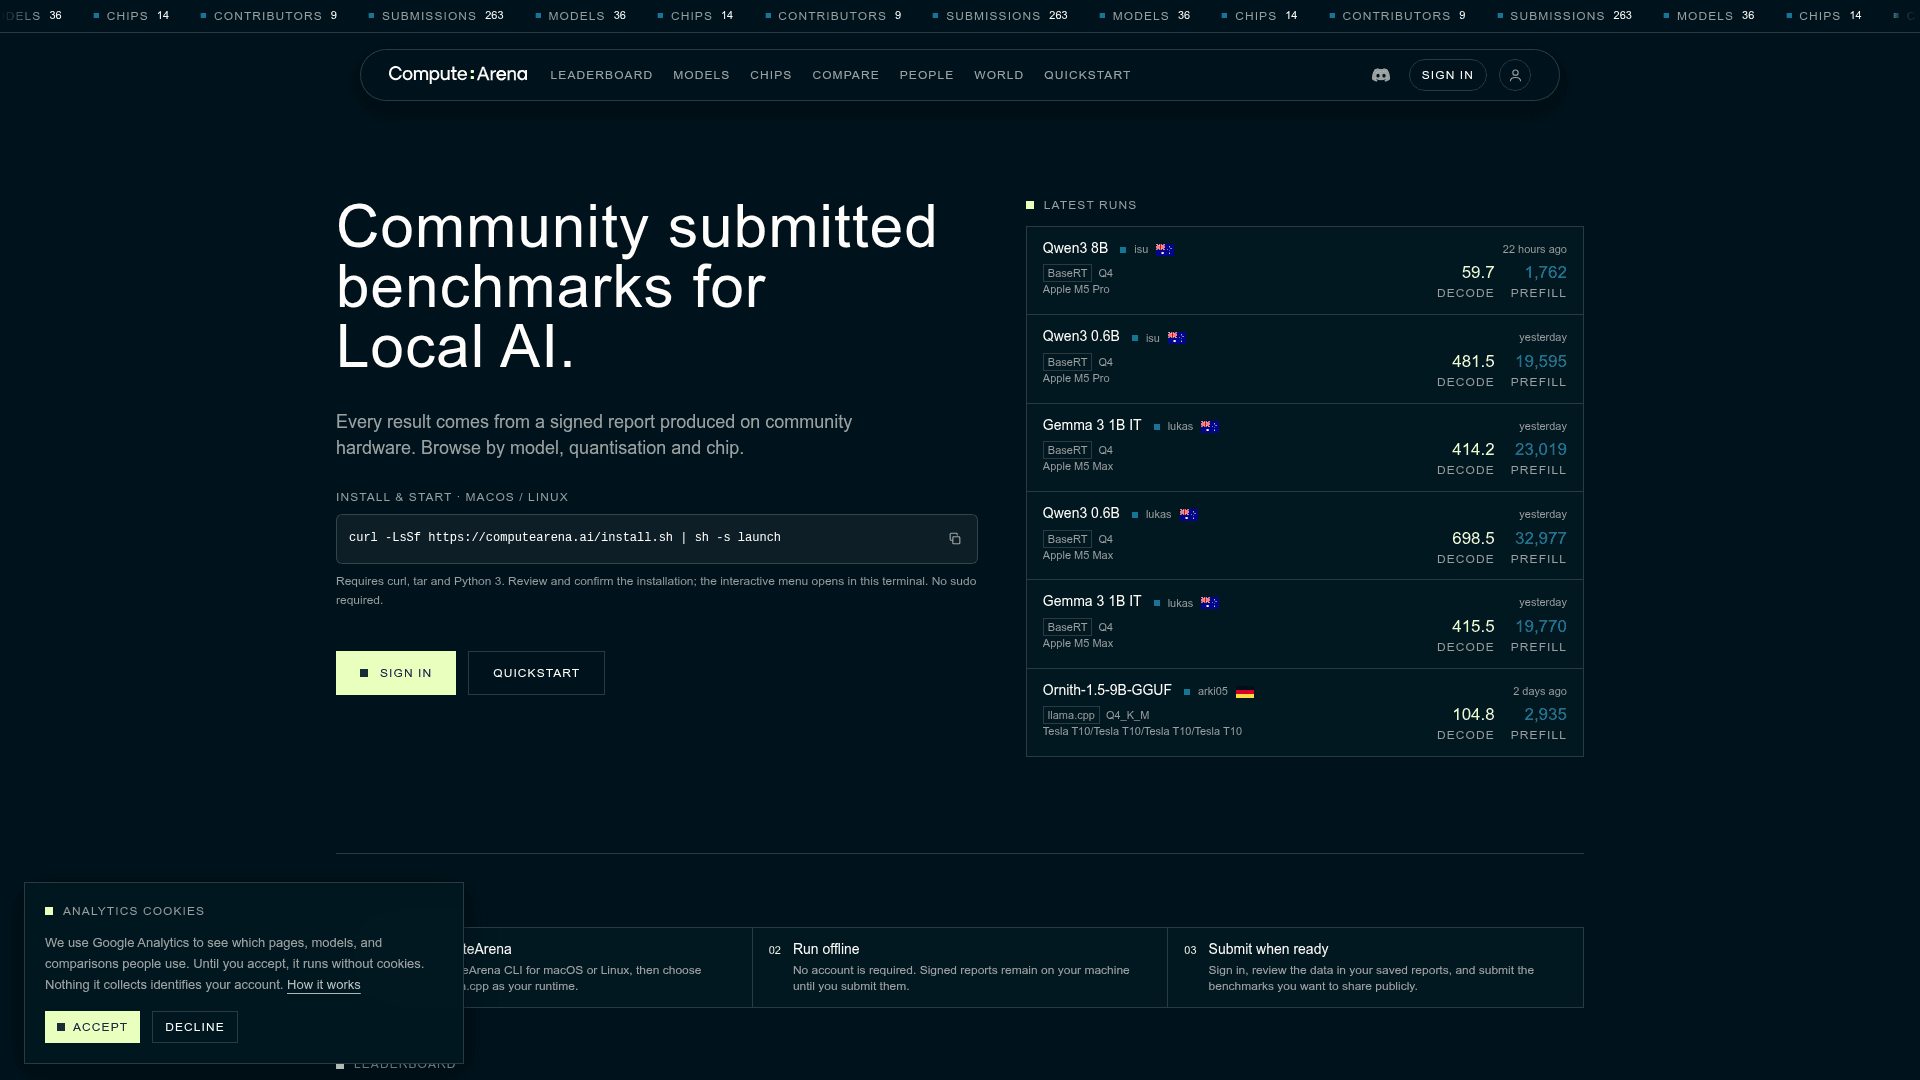
Compute:Arena fills a specific gap: there is no neutral, community-sourced database of how fast local AI models actually run on real consumer and prosumer silicon. The platform collects prefill and decode throughput measurements — expressed as tokens per second — across combinations of model, quantization format, runtime, and chip. Headline rankings compare PP512 prefill and TG128 decode workloads so every submission is comparable at a standard size. As of the latest data visible on the site, the leaderboard holds 263 submissions covering 36 models and 14 chips contributed by 9 community members.
How the Benchmark Workflow Works
The workflow is designed around offline-first, verifiable measurement:
- Install: A one-line curl installer sets up the
computearenaCLI on macOS (Apple Silicon) or Linux (x86_64, arm64). No sudo is required. - Run offline: The CLI launches a separate benchmark executable — either BaseRT or llama.cpp — measures prefill and decode throughput, and saves a signed JSON report locally. No account or network connection is needed at this stage.
- Sign and verify: Each report is an Ed25519-signed envelope (
computearena-benchmark/1) that records the runtime executable hash, model file hash, chip identity, telemetry, and raw per-repetition timings. The signature confirms the report has not changed since the installation signed it. - Submit when ready: After logging in via a device flow, the CLI previews the exact JSON that will become public and asks for confirmation before uploading.
Two runtimes are supported through a common adapter interface: BaseRT (using .base model bundles) and llama.cpp (using .gguf files). The README notes that MLX and vLLM adapters could be added behind the same interface in the future.
Chip and Model Coverage
The leaderboard currently tracks results across Apple Silicon (M1 Pro through M5 Max), AMD Radeon RX 7900 XT (via ROCm and Vulkan), NVIDIA GeForce RTX 4060 Laptop GPU (CUDA), and Tesla T10 multi-GPU configurations. Models benchmarked include Qwen3 (0.6B through 30B), Gemma 3 and 4, Llama 3.2, GPT-OSS 20B, and community fine-tunes. Quantization variants — Q4, Q8, Q4_K_M, Q2_K, and others — are tracked as distinct leaderboard entries so users can compare the throughput cost of different precision levels on the same hardware.
Trust Model and Limitations
The signed report design is explicit about what the signature does and does not guarantee. The README states: "What the signature means: the report has not changed since this installation signed it. What it does not mean: that the runtime, driver, operating system, or client reported the truth." The server checks submitted runtime checksums against a catalogue of official builds; unrecognized or custom builds are accepted and flagged rather than rejected. Model identity is tracked at three levels — canonical Hugging Face model class, converted artifact repository and revision, and SHA-256 of the local file bytes — to prevent ambiguous grouping by filename alone.
Update: CLI v0.1.3
The CLI repository on GitHub shows version 0.1.3 as the latest stable release, published in September 2026. The project moved from a basert/computearena data directory layout to a top-level computearena directory in the 0.1.0 release, with automatic migration of saved reports, signing keys, and sessions. Recent protocol additions include computearena-throughput/3 for headline-first BaseRT capacity benchmarks and native same-run telemetry support (basert-telemetry/4). The CLI is built with Rust 1.85 or newer and can also be compiled from source via cargo install.
Community Discussions
Be the first to start a conversation about Compute:Arena
Share your experience with Compute:Arena, ask questions, or help others learn from your insights.
Pricing
Open Source
Fully free and open-source CLI and leaderboard under Apache-2.0. No cost to run benchmarks, submit results, or browse the leaderboard.
- Unlimited local benchmark runs
- Community leaderboard access
- Signed report generation and verification
- BaseRT and llama.cpp runtime support
- Leaderboard submission
Capabilities
Key Features
- Community-submitted throughput benchmarks for local AI models
- Leaderboard filterable by model, quantization, runtime, and chip
- Offline-first benchmark workflow — no account required to run
- Ed25519-signed JSON reports with executable and model file hashes
- Support for BaseRT and llama.cpp runtimes via a common adapter interface
- Prefill (PP512) and decode (TG128) throughput measurements
- Model identity tracking at class, artifact, and file-hash levels
- Telemetry: memory, temperature sensors, power state, NVIDIA/ROCm snapshots
- Interactive full-screen CLI with arrow-key navigation
- Device-flow login and submission preview before any data is uploaded
- Compare view for cross-chip and cross-runtime analysis
- Chip normalization and alias resolution for consistent leaderboard entries
- Build from source with Rust 1.85+
- Sigstore signatures on release archives for supply-chain verification