EveryDev.ai
Subscribe
Home
Tools

4,536+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents3274
  • Coding2275
  • Infrastructure1000
  • Projects696
  • Marketing636
  • Research587
  • MCP532
  • Design508
  • Analytics506
  • Testing394
  • Security376
  • Data327
  • Integration244
  • Prompts244
  • Communication235
  • Extensions217
  • Voice193
  • Learning190
  • Commerce170
  • DevOps153
  • Web103
  • Finance36
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai © 2026
    1. Home
    2. Tools
    3. Claw-Eval
    Claw-Eval icon

    Claw-Eval

    LLM Evaluations

    Open-source evaluation harness and benchmark for testing LLMs as autonomous agents on 300 human-verified tasks.

    Visit Website

    At a Glance

    Pricing
    Open Source

    Claw-Eval evaluation harness released under the MIT License; self-hosted. Users supply their own model API keys (e.g., OpenRouter), which are external costs.

    Engagement

    Available On

    macOS
    Linux
    API
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    LLM EvaluationsAgent HarnessPerformance Metrics

    Alternatives

    VitaBenchFeatherbenchAgentBench
    Developer
    claw-evalEst. 2026

    Listed Oct 2026

    About Claw-Eval

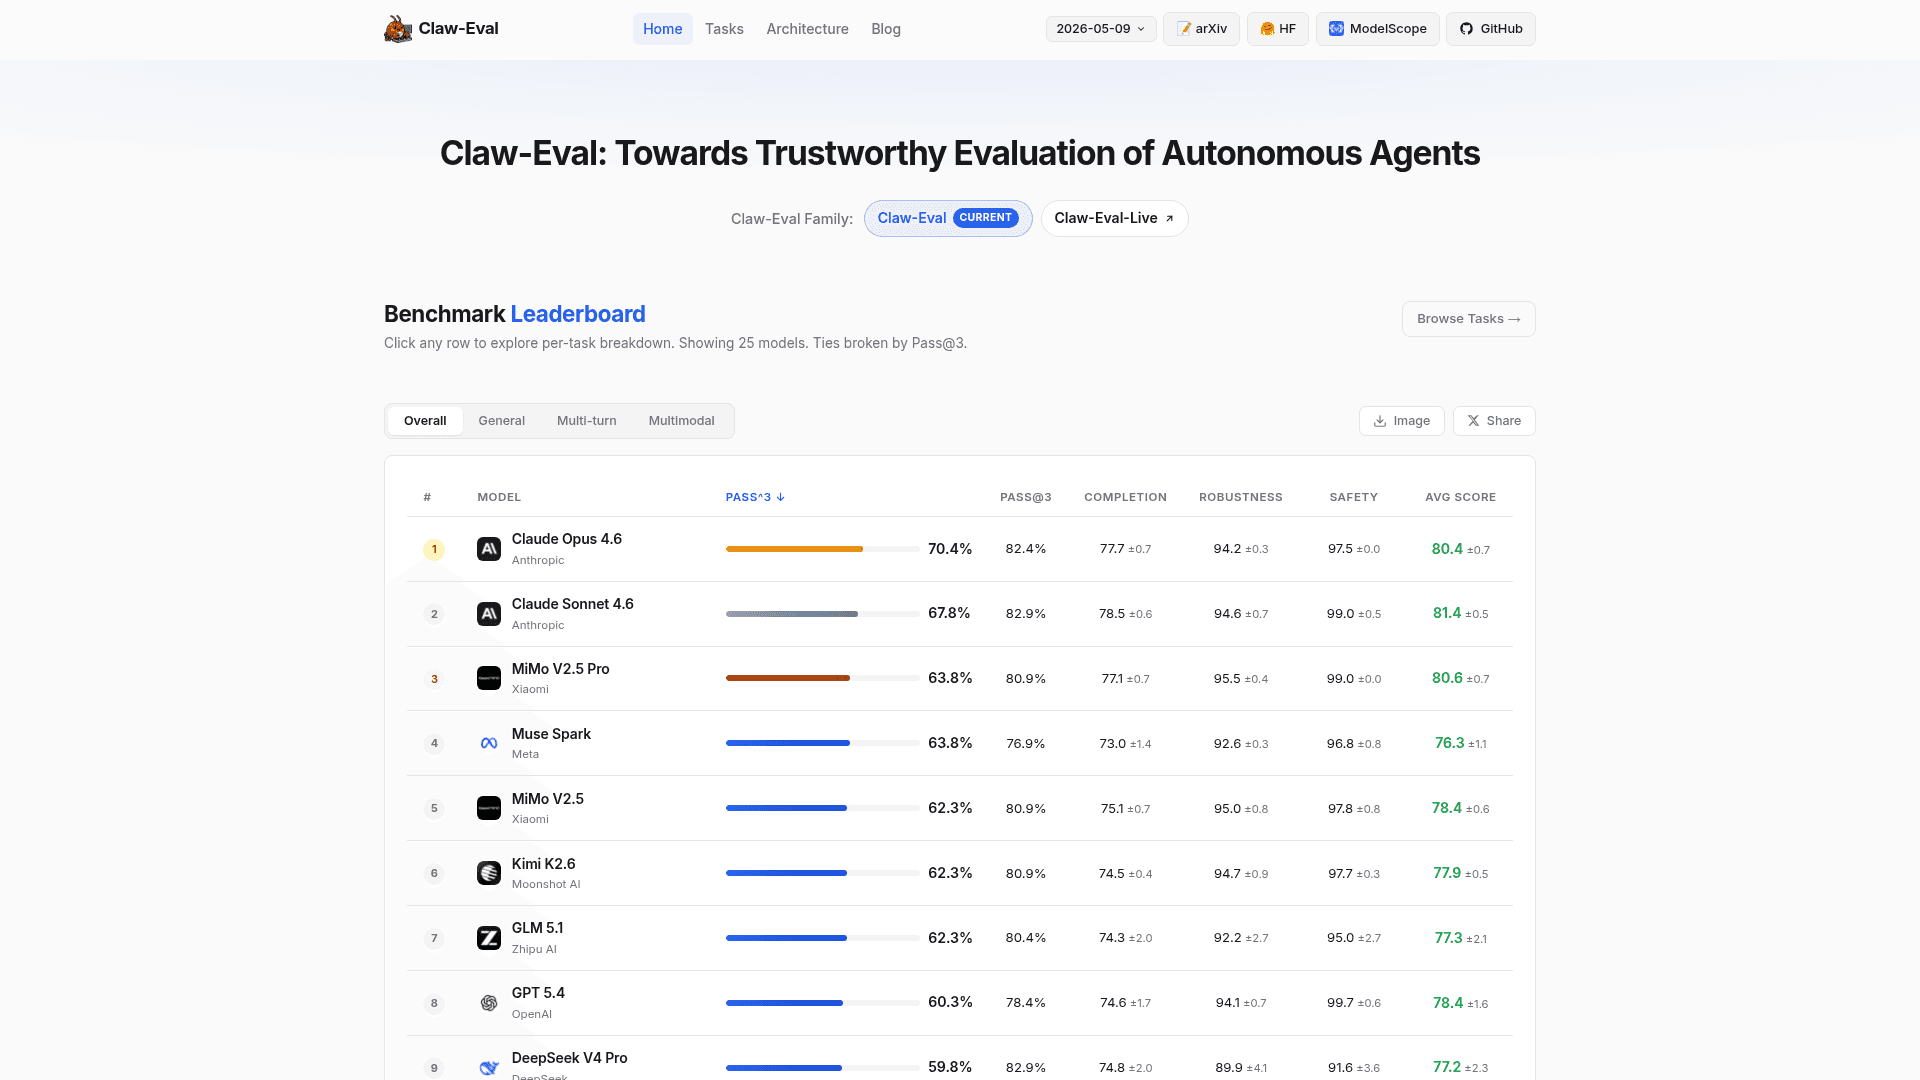
    Claw-Eval is an open-source evaluation harness and benchmark for LLM-based autonomous agents, published by the claw-eval organization under the MIT License. It provides 300 human-verified tasks with 2,159 rubrics across 9 categories, and a public leaderboard at claw-eval.github.io. Agents are graded on completion, safety and robustness.

    What It Is

    Claw-Eval is a Python benchmark harness that runs models as agents against tasks and audits their full trajectories. The README describes the title as "Towards Trustworthy Evaluation of Autonomous Agents" and links an arXiv paper and datasets on Hugging Face and ModelScope. Tasks are split into general (161), multimodal (101) and multi-turn (38) sets. General tasks cover communication, finance, ops and productivity. Multimodal tasks cover webpage generation, video QA and document extraction. Multi-turn tasks use simulated user personas.

    How Scoring Works

    The primary metric is Pass^3: a task counts as passed only if the model meets the success criteria in all three independent trials. The site gives the per-task score as safety × (0.8 × completion + 0.2 × robustness), with a pass threshold of 75. The leaderboard reports Pass^3, Pass@3, completion, robustness, safety and average score, plus a view of Pass^3 against token efficiency on general tasks. According to the README, graders are gemini-3-flash for general and multimodal tasks and claude opus4.6 for multi-turn tasks.

    Running It

    Setup uses uv with Python 3.11. Users set an OPENROUTER_API_KEY, optionally a SERP_DEV_KEY for tasks needing real web search, and run scripts/test_sandbox.sh. Evaluations are launched with the claw-eval batch command using a model config YAML, with options such as sandbox mode, number of trials and parallelism. Full fixtures, including videos, are hosted on Hugging Face. EvalScope also supports running Claw-Eval against OpenAI-compatible endpoints.

    Current Status

    The README lists v1.1.0 with 300 human-verified tasks in 9 categories. It states that the codebase is being audited so leaderboard results can be community-verified. Teams wanting to submit results to the leaderboard are directed to the listed contact emails.
    Claw-Eval - 1

    Community Discussions

    Be the first to start a conversation about Claw-Eval

    Share your experience with Claw-Eval, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source (MIT)

    Claw-Eval evaluation harness released under the MIT License; self-hosted. Users supply their own model API keys (e.g., OpenRouter), which are external costs.

    • MIT License
    • 300 human-verified tasks across 9 categories
    • Run via CLI: claw-eval batch
    • Dataset on Hugging Face and ModelScope
    • External costs: BYOK model API keys (e.g., OPENROUTER_API_KEY)

    Capabilities

    Key Features

    • 300 human-verified tasks with 2,159 rubrics across 9 categories
    • General, multimodal and multi-turn task splits
    • Pass^3 metric requiring success in three independent trials
    • Scoring on completion, safety and robustness
    • Full-trajectory auditing
    • Sandboxed batch evaluation with parallel runs
    • Public leaderboard with per-task breakdown
    • Token efficiency comparison
    • Dataset on Hugging Face and ModelScope
    • Simulated user personas for multi-turn tasks

    Integrations

    OpenRouter
    Hugging Face
    ModelScope
    EvalScope
    uv
    Novada
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate Claw-Eval and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    claw-eval Team

    Founded 2026
    Read more about claw-eval Team
    WebsiteGitHub
    1 tool in directory

    Similar Tools

    VitaBench icon

    VitaBench

    An open-source benchmark for evaluating LLM agents on versatile interactive tasks grounded in real-world life-serving applications like food delivery, in-store consumption, and online travel.

    Featherbench icon

    Featherbench

    A single-file Python harness for building private LLM benchmarks from JSON tasks and comparing models on pass rate, cost and latency via OpenRouter.

    AgentBench icon

    AgentBench

    AgentBench is an open-source benchmark framework for evaluating LLMs as autonomous agents across 8 diverse environments including OS, database, web, and knowledge graph tasks.

    Browse all tools

    Related Topics

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    156 tools

    Agent Harness

    Infrastructure, orchestrators, and task runners that wrap around LLM coding agents — covering session management, context delivery, worktree isolation, architecture enforcement, and issue-to-PR pipelines.

    244 tools

    Performance Metrics

    Specialized tools for measuring, evaluating, and optimizing AI model performance across accuracy, speed, resource utilization, and other critical parameters.

    77 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions