EveryDev.ai
Subscribe
Home
Tools

4,691+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents3426
  • Coding2391
  • Infrastructure1055
  • Projects732
  • Marketing662
  • Research612
  • MCP593
  • Analytics538
  • Design533
  • Testing420
  • Security410
  • Data358
  • Prompts260
  • Integration256
  • Communication250
  • Extensions222
  • Voice201
  • Learning193
  • Commerce173
  • DevOps161
  • Web122
  • Finance36
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai © 2026
    1. Home
    2. Tools
    3. EvalPlus
    EvalPlus icon

    EvalPlus

    LLM Evaluations

    Open-source evaluation framework that rigorously tests LLM-generated code for correctness and efficiency using HumanEval+, MBPP+ and EvalPerf.

    Visit Website

    At a Glance

    Pricing
    Open Source

    EvalPlus evaluation framework released under the Apache License 2.0; self-hosted, no-charge license grant.

    Engagement

    Available On

    macOS
    Linux
    API
    SDK
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    LLM EvaluationsAI Development LibrariesAutomated Testing

    Alternatives

    LM Evaluation HarnessFeatherbenchClaw-Eval
    Developer
    evalplusEst. 2023

    Listed Oct 2026

    About EvalPlus

    EvalPlus is an open-source evaluation framework for LLMs on code tasks, published by the evalplus organization on GitHub with an accompanying benchmarks site and leaderboards. It extends the HumanEval and MBPP benchmarks with far more tests and adds an efficiency benchmark called EvalPerf. The latest documented release is v0.3.1, dated 2024-10-20.

    What It Is

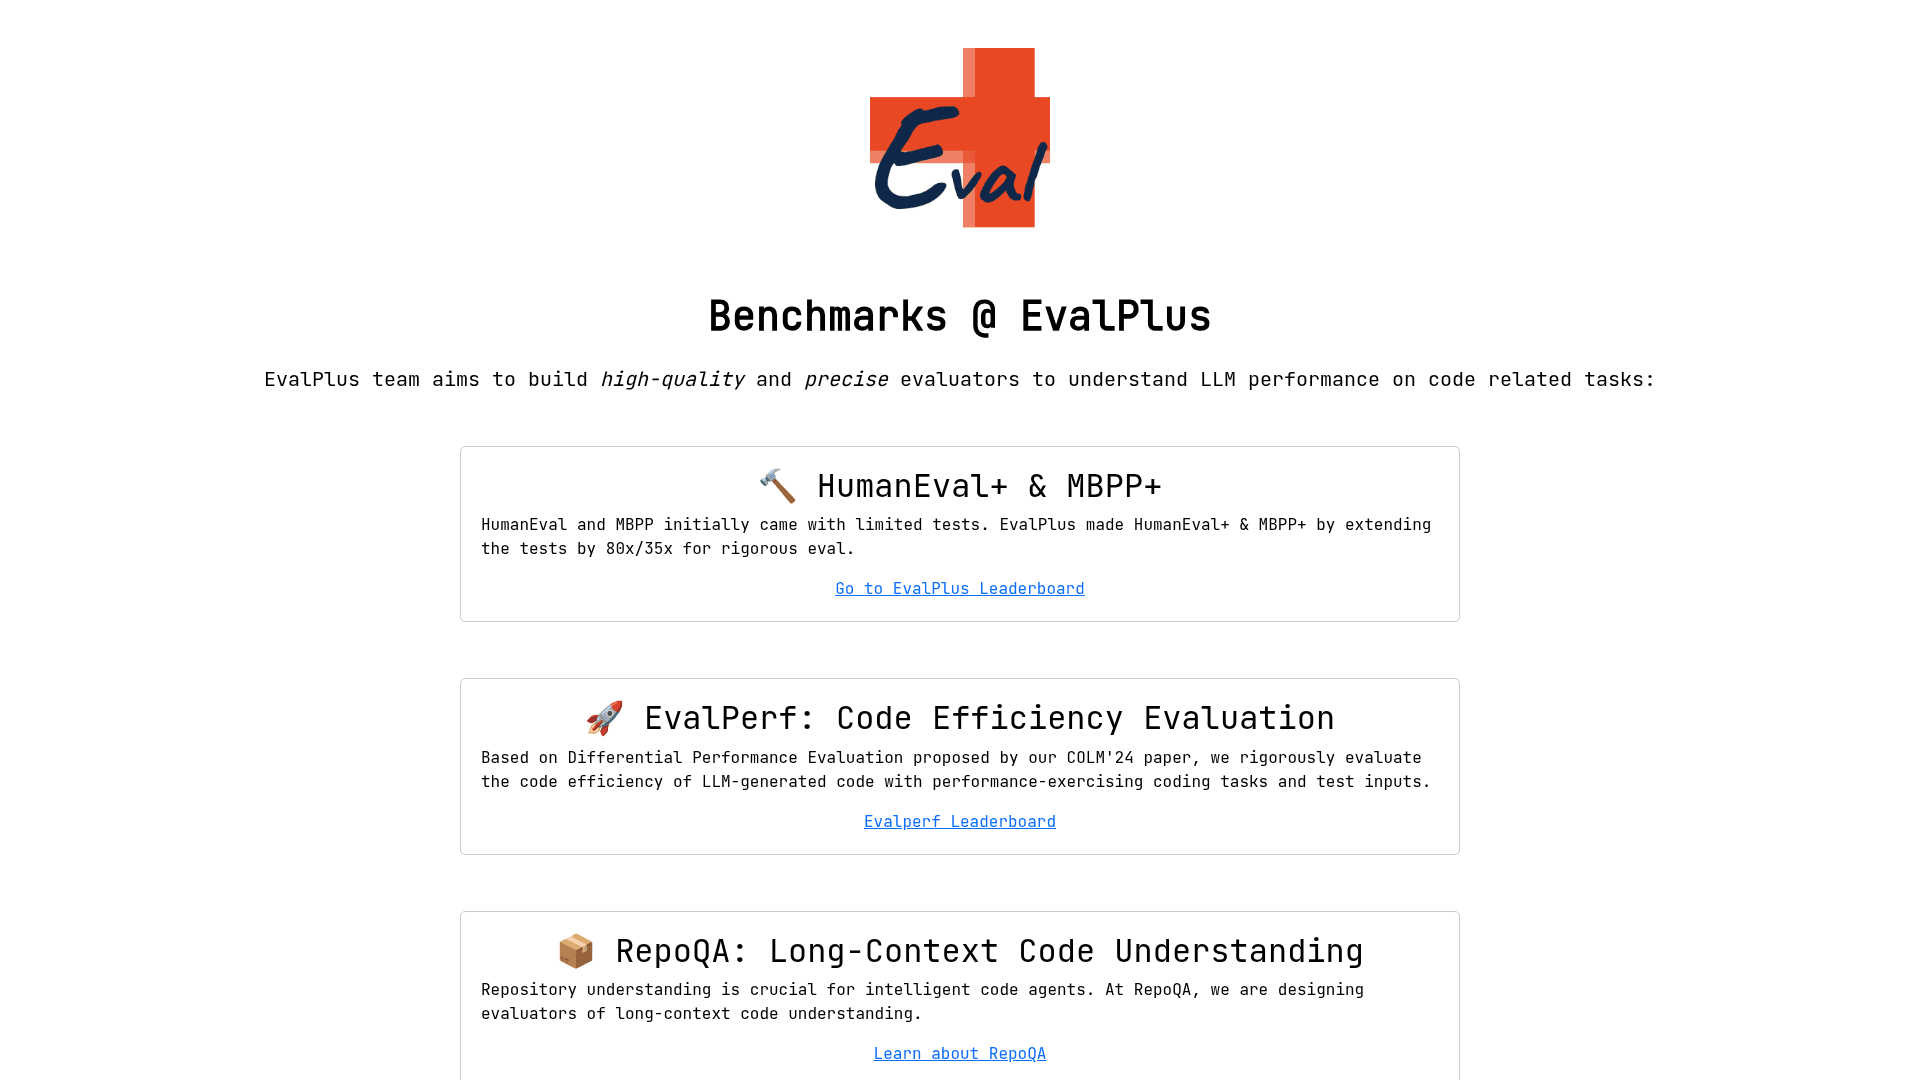
    EvalPlus is a Python package and Docker image for measuring how well language models write code. It provides HumanEval+ (80x more tests than the original HumanEval) and MBPP+ (35x more tests than the original MBPP) for correctness. EvalPerf evaluates the efficiency of generated code using performance-exercising coding tasks and test inputs, based on Differential Performance Evaluation from a COLM'24 paper. The project is associated with NeurIPS 2023 and COLM 2024 papers.

    How the Evaluation Workflow Works

    Users install the package with pip and run commands such as evalplus.evaluate, choosing a model, a dataset (humaneval or mbpp), and an inference backend. evalplus.codegen generates samples, and evalplus.evalperf runs efficiency evaluation (Unix-like systems only, with perf enabled). Generated code can be executed inside Docker for safer execution. Results and generations are written to an evalplus_results directory. A single command can run generation, post-processing and evaluation. Base and chat models use different prompts, detected from the tokenizer chat template for the hf and vllm backends.

    Backends and Model Access

    Supported backends include Hugging Face transformers, vLLM, OpenAI-compatible servers, OpenAI, Anthropic, Google Gemini, Amazon Bedrock, Ollama, GPTQModel and Intel Gaudi (hf_gaudi). OpenAI-compatible endpoints can be used with services such as DeepSeek and Grok via a base URL.

    Leaderboards and Wider Benchmarks

    The EvalPlus site hosts a leaderboard comparing scores before and after the extended tests, and an EvalPerf leaderboard. The README says the datasets have been used by teams behind models such as Meta Llama 3.1, Qwen2.5-Coder and StarCoder2. The site also describes RepoQA, an effort on long-context code understanding.
    EvalPlus - 1

    Community Discussions

    Be the first to start a conversation about EvalPlus

    Share your experience with EvalPlus, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source (Apache-2.0)

    EvalPlus evaluation framework released under the Apache License 2.0; self-hosted, no-charge license grant.

    • Apache License 2.0 (OSI-approved)
    • HumanEval+ and MBPP+ evaluation
    • EvalPerf code efficiency evaluation
    • Install via PyPI or Docker
    • Files under evalplus/eval/ additionally comply with the MIT License

    Capabilities

    Key Features

    • HumanEval+ benchmark with 80x more tests
    • MBPP+ benchmark with 35x more tests
    • EvalPerf code efficiency evaluation
    • One command for generation, post-processing and evaluation
    • Docker-based safe code execution
    • Multiple LLM inference backends
    • Public leaderboards for correctness and efficiency
    • RepoQA long-context code understanding evaluators

    Integrations

    Hugging Face Transformers
    vLLM
    OpenAI
    Anthropic
    Google Gemini
    Amazon Bedrock
    Ollama
    GPTQModel
    Intel Gaudi
    DeepSeek
    Grok
    Docker
    bigcode-evaluation-harness
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate EvalPlus and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    evalplus Team

    Founded 2023

    Used by

    Google, Meta, and Amazon are cited by…
    Read more about evalplus Team
    WebsiteGitHub
    1 tool in directory

    Similar Tools

    LM Evaluation Harness icon

    LM Evaluation Harness

    Open-source framework from EleutherAI for few-shot evaluation of language models across many academic benchmarks.

    Featherbench icon

    Featherbench

    A single-file Python harness for building private LLM benchmarks from JSON tasks and comparing models on pass rate, cost and latency via OpenRouter.

    Claw-Eval icon

    Claw-Eval

    Open-source evaluation harness and benchmark for testing LLMs as autonomous agents on 300 human-verified tasks.

    Browse all tools

    Related Topics

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    172 tools

    AI Development Libraries

    Programming libraries and frameworks that provide machine learning capabilities, model integration, and AI functionality for developers.

    395 tools

    Automated Testing

    AI-powered platforms that automate end-to-end testing processes with intelligent test case generation, execution, and reporting for faster, more reliable software delivery.

    171 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions