club-3090
Community recipes and Docker Compose configs for serving LLMs locally on RTX 3090s and other NVIDIA GPUs, with an OpenAI-compatible API via vLLM, SGLang, llama.cpp, and more.
At a Glance
Fully free and open-source under Apache 2.0. Clone, use, modify, and distribute freely.
Engagement
Available On
Alternatives
Listed Oct 2026
About club-3090
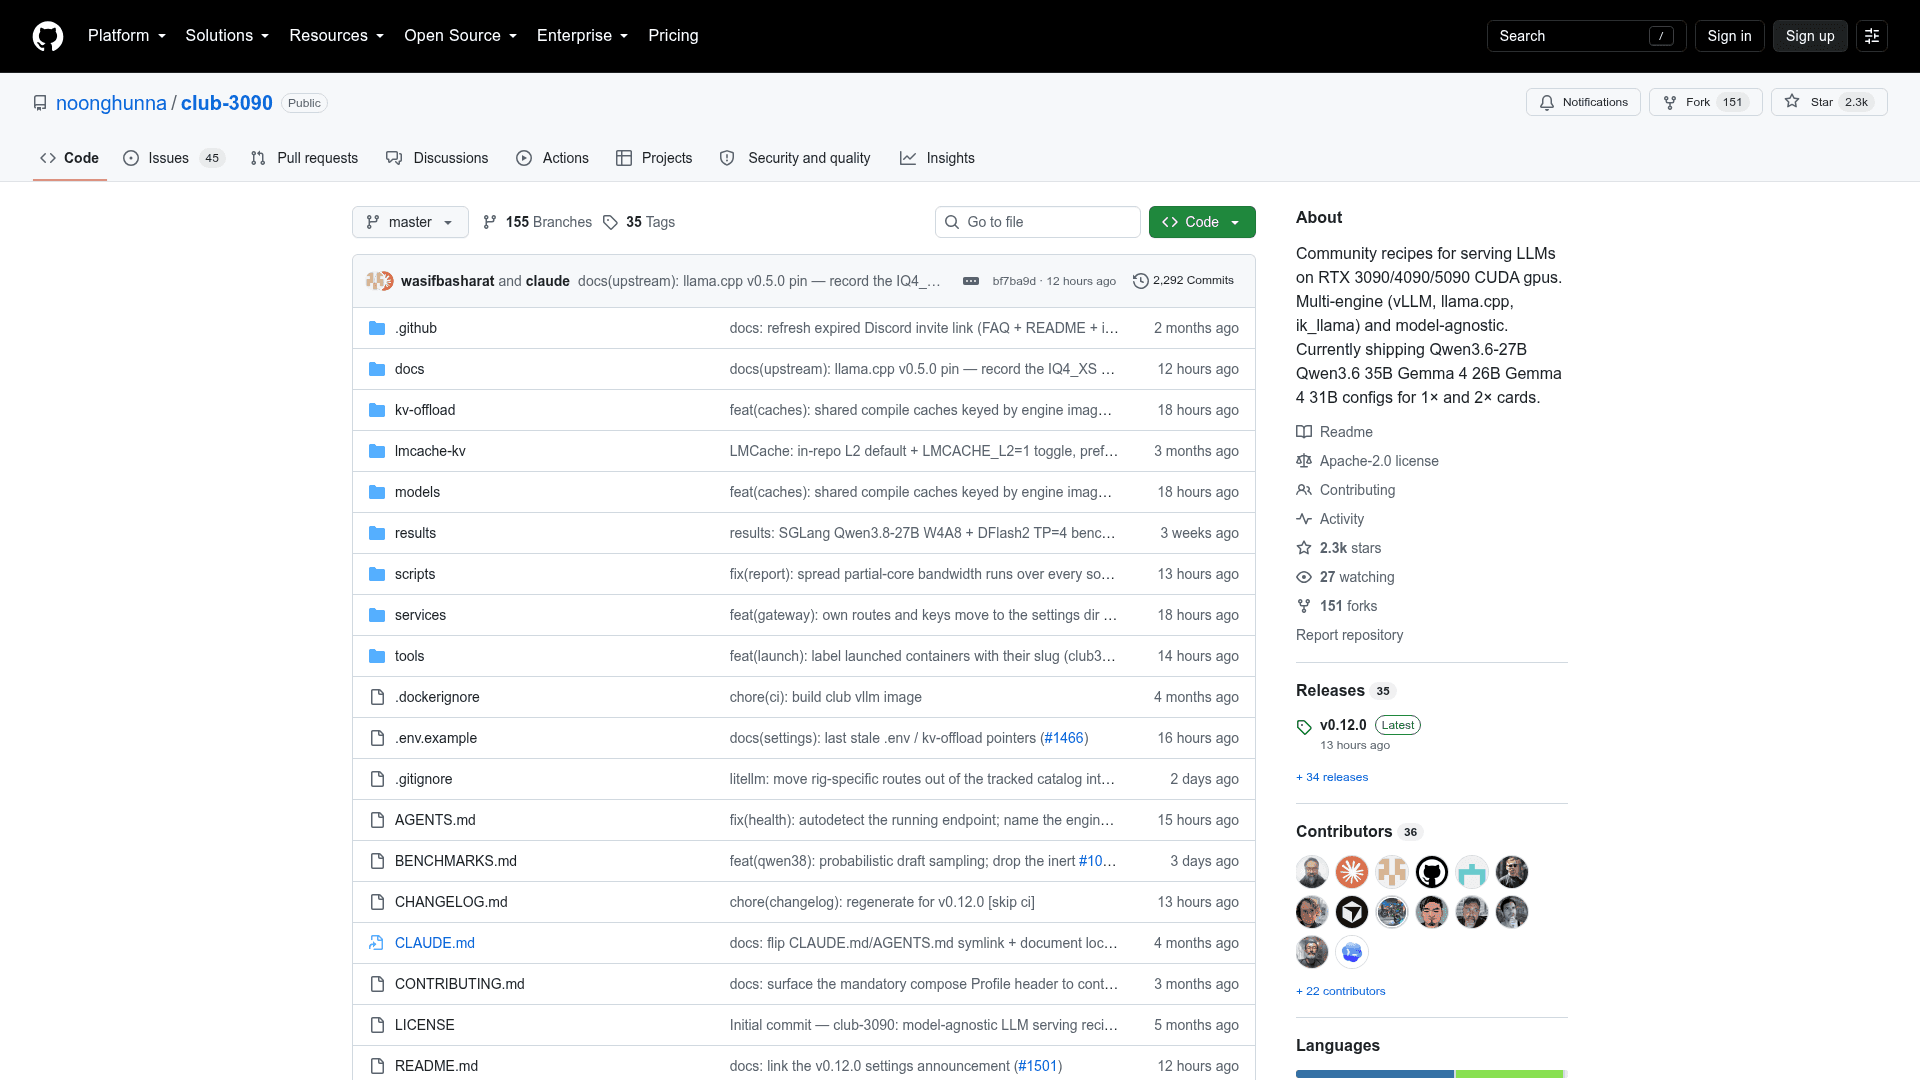
Club-3090 is an open-source collection of working Docker Compose configurations, patches, and benchmark data for running large language models locally on consumer NVIDIA GPUs — primarily the RTX 3090, but also tested on 4090s, 5090s, and A-series cards. Maintained by the GitHub user noonghunna and licensed under Apache 2.0, the project lets users pick a model, launch it with a single command, and get an OpenAI-compatible API endpoint on their own hardware.
What It Is
Club-3090 is a local inference recipe library: a structured repository of per-model, per-engine, per-topology Docker Compose files that abstract away the complexity of running quantized LLMs on consumer GPUs. It is not a new inference engine itself — it sits on top of established engines (vLLM, SGLang, llama.cpp, ik_llama, exllamav3) and provides the glue: verified compose configs, vendored patches, setup scripts, and a benchmark table so users know what performance to expect before they download anything.
How the Workflow Works
The setup path is designed to go from clone to first reply in about five minutes:
scripts/setup.sh— picks a model, downloads weights, and SHA-verifies themscripts/launch.sh— selects a config for the detected GPU topology and boots it with a health checkscripts/switch.sh— lists all configs the current machine can run and switches between themscripts/update.sh— pulls the latest stack and re-runs setup
A terminal cockpit called c3 (installable via uv pip install -e tools/serve-cockpit) provides a screen-based UI for browsing the catalog, launching configs, watching GPU and container state, and running health checks — all without touching the CLI directly.
Multi-Engine and Multi-GPU Architecture
Configs are organized under models/<model>/<engine>/compose/<topology>/<quant>/<serving>.yml, making the structure explicit: one compose file per "slug" (a unique combination of model, engine, topology, and quantization). The repository currently ships configs for:
- Single-card (1× RTX 3090) — documented in
docs/SINGLE_CARD.md - Dual-card (2× RTX 3090) — documented in
docs/DUAL_CARD.md - Multi-card (4× and 8× GPUs) — documented in
docs/MULTI_CARD.md
Supported engines include vLLM, SGLang, llama.cpp, ik_llama, and exllamav3. The configs are hardware-class aware, and contributors have validated them on 4090s, 5090s, and mixed-architecture rigs (e.g., 5090 + 3090 Ti in one box).
Beyond Chat: AI Studio
The repository includes a Club 3090 AI Studio extension (docs/ai-studio/) that adds open-weight image, video, and audio generation alongside a chat model, driven from Open WebUI. The image bundle launches with a single script: bash scripts/setup-image-studio.sh.
Update: v0.12.0
The latest release is v0.12.0, published on 2026-09-29. The repository was created in April 2026 and has seen active development since, with the GitHub About description noting current configs for Qwen3.6-27B, Qwen3.6 35B, Gemma 4 26B, and Gemma 4 31B across 1× and 2× card topologies. The repo's Announcements discussion category is the canonical source for the newest slugs and benchmark numbers, with the docs catching up afterward. A community project, VykosX/club-3090-server, adds a browser admin panel, OpenAI-compatible reverse proxy, and GPU-aware multi-instance orchestration on top of the base repo.
Community and Contribution Model
The project uses GitHub Discussions for async benchmark sharing and cross-rig comparisons, GitHub Issues for bug reports, and a Discord server for synchronous Q&A and hardware questions. Benchmark results from community contributors across different GPU rigs are collected in BENCHMARKS.md, with a standardized Results Card format (including per-pack dispersion and p50/p95 latency) adopted from community input.
Community Discussions
Be the first to start a conversation about club-3090
Share your experience with club-3090, ask questions, or help others learn from your insights.
Pricing
Open Source
Fully free and open-source under Apache 2.0. Clone, use, modify, and distribute freely.
- All Docker Compose configs for vLLM, SGLang, llama.cpp, ik_llama, exllamav3
- Setup, launch, switch, and update scripts
- Benchmark data and results cards
- Terminal cockpit (c3)
- AI Studio for image/video/audio generation
Capabilities
Key Features
- Working Docker Compose configs for vLLM, SGLang, llama.cpp, ik_llama, and exllamav3
- OpenAI-compatible API endpoint out of the box
- Single-command setup, launch, and switch scripts
- SHA-verified model weight downloads
- Hardware-class-aware configs for 1×, 2×, 4×, and 8× GPU topologies
- Terminal cockpit (c3) for browsing catalog and managing serving
- Benchmark table with measured TPS and latency numbers
- AI Studio extension for image, video, and audio generation via Open WebUI
- Bring-your-own-model support with VRAM pre-check
- Quality and health check eval scripts
- Troubleshooting guide, FAQ, glossary, and quantization reference docs