llmrun
Web tool that shows which local LLMs your GPU or Mac can run, with VRAM needs per quantization, estimated speed, and fit ratings.
At a Glance
Public access to llmrun's hardware compatibility checker, model rankings and reference pages without an account or payment. Hardware purchases, cloud providers and third-party model licenses have separate costs or terms.
Engagement
Available On
Alternatives
Listed Oct 2026
About llmrun
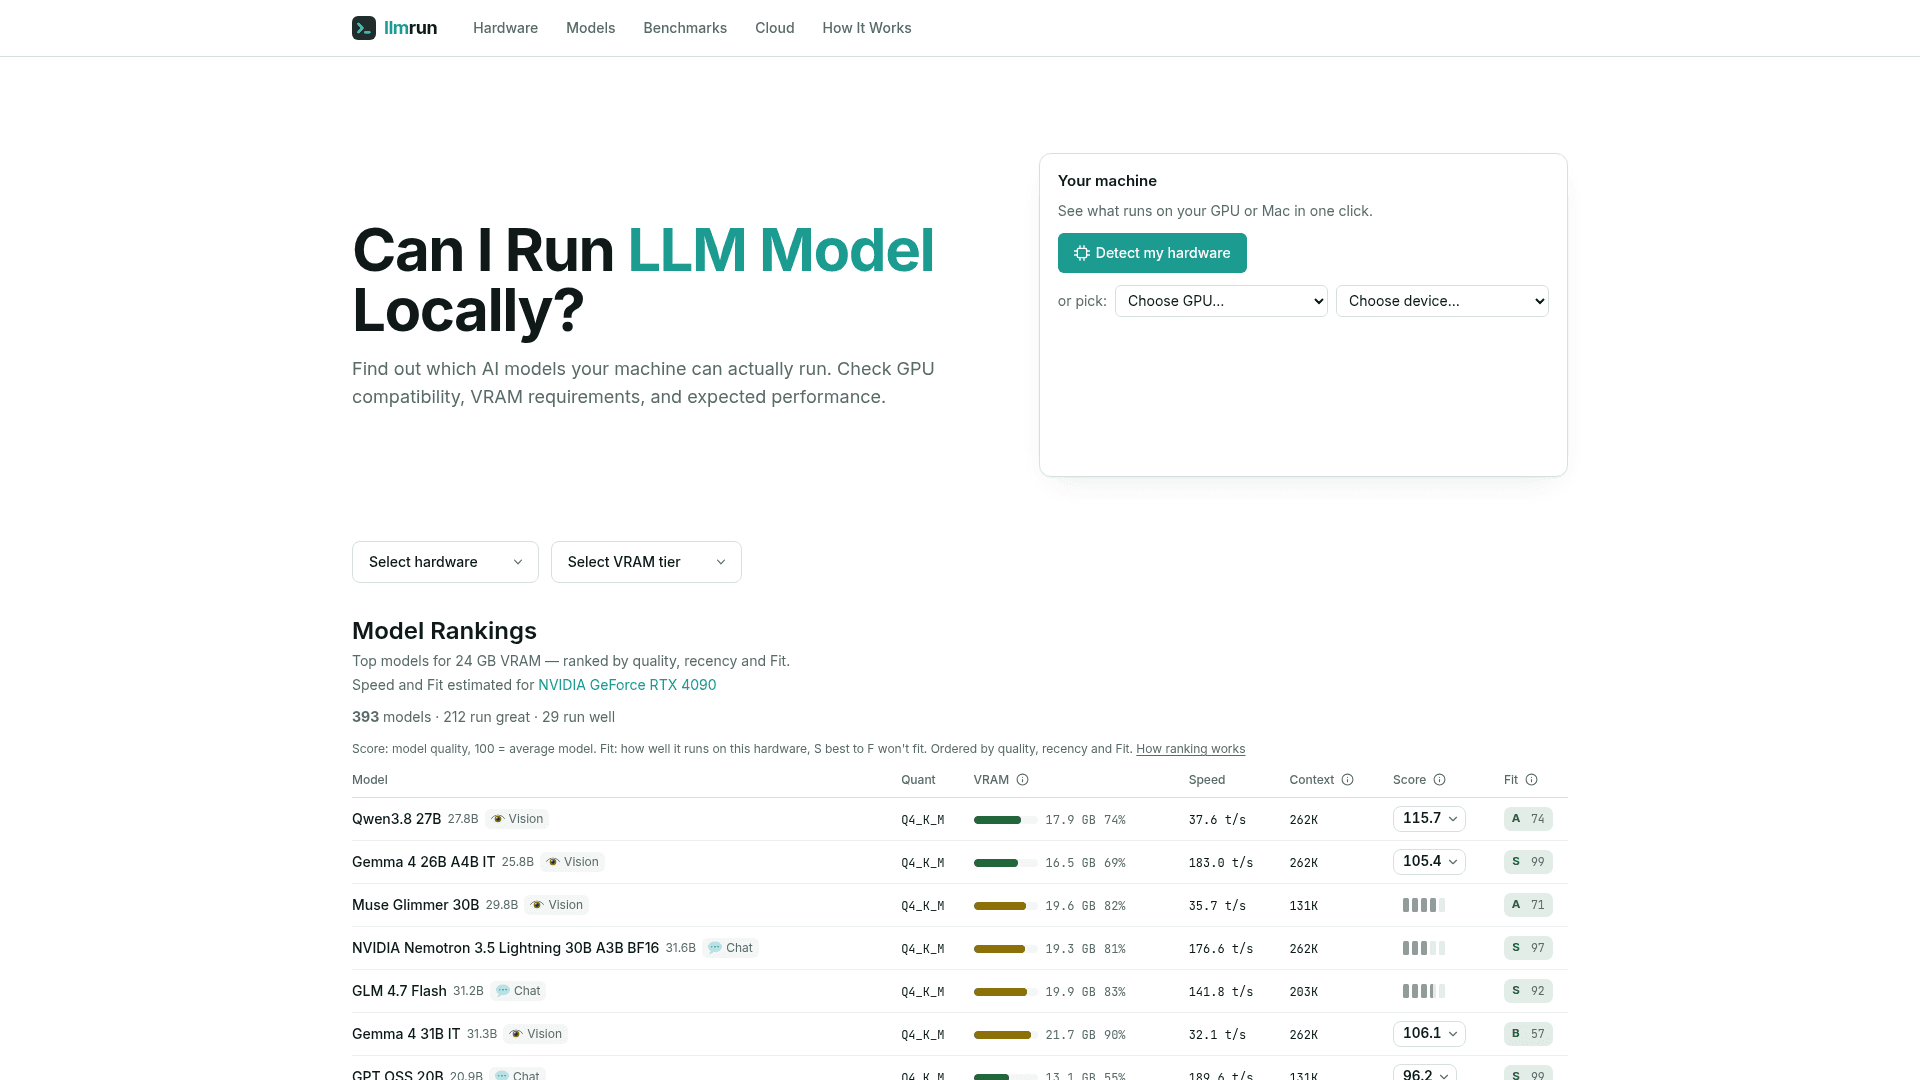
llmrun is a web tool for checking which open-weight language models a given GPU or Apple Silicon device can run locally. Users detect their hardware or pick a GPU, device, or VRAM tier, then get a ranked model list with quantization, VRAM use, estimated speed, context length, and a fit rating.
What It Is
llmrun answers the question of whether a model will run on a particular machine. The site covers desktop GPUs from NVIDIA, AMD, and Intel, data-center cards, Apple Silicon Macs, mini PCs, Jetson boards, and phones and tablets. For each model it lists the quantization (for example Q4_K_M), the memory required, estimated tokens per second, and context window.
How the Ranking Works
Models are ordered by quality score, recency, and Fit. Fit is a letter grade from S (best) to F (won't fit), with labels such as Runs great, Runs well, and Decent. Speed and fit figures are estimates for the selected hardware. Model pages carry short descriptions covering parameters, modality (vision or chat), license, and context length.
Browsing and Setup Path
Users can browse by VRAM tier (8, 12, 16, 24, and 48 GB), by hardware, or by model. The site's How It Works steps are to select hardware, check compatibility, and then install via Ollama or LM Studio or download the GGUF file. The site also has benchmark and cloud sections.
Community Discussions
Be the first to start a conversation about llmrun
Share your experience with llmrun, ask questions, or help others learn from your insights.
Pricing
Free web access
Public access to llmrun's hardware compatibility checker, model rankings and reference pages without an account or payment. Hardware purchases, cloud providers and third-party model licenses have separate costs or terms.
- Browse hardware and VRAM tiers
- Check model fit and estimated inference speed
- Compare quantization and memory requirements
- Browse model rankings and benchmark references
Capabilities
Key Features
- One-click hardware detection
- GPU and device picker covering NVIDIA, AMD, Intel, Apple Silicon, and AI boxes
- VRAM requirements per quantization
- Estimated tokens-per-second speed
- Fit rating from S to F
- Model rankings by quality, recency, and fit
- Browse by VRAM tier
- Model pages with context length, license, and modality
- Public benchmarks section