Crawlee for Python
Open-source Python library for web scraping and browser automation with proxy rotation, HTTP and headless browser crawlers, and persistent storage.
At a Glance
Crawlee for Python is a free, open-source web scraping and browser automation library licensed under Apache License 2.0.
Engagement
Available On
Alternatives
Listed Oct 2026
About Crawlee for Python
Crawlee for Python is an open-source web scraping and browser automation library developed by Apify. It lets developers build crawlers that fetch pages, extract data, and store results in machine-readable formats. The latest release listed is v1.10.4, and the project is licensed under Apache 2.0.
What It Is
Crawlee is a Python library installed from PyPI as the crawlee package, with optional extras for features such as BeautifulSoup and Playwright. Crawlers are regular Python scripts built on asyncio. They work with Parsel, BeautifulSoup, Playwright, and raw HTTP, in headful or headless mode. The project's GitHub description says the extracted data can be used for AI, LLM, and RAG workflows, and that files such as HTML, PDF, JPG, and PNG can be downloaded.
How a Crawl Works
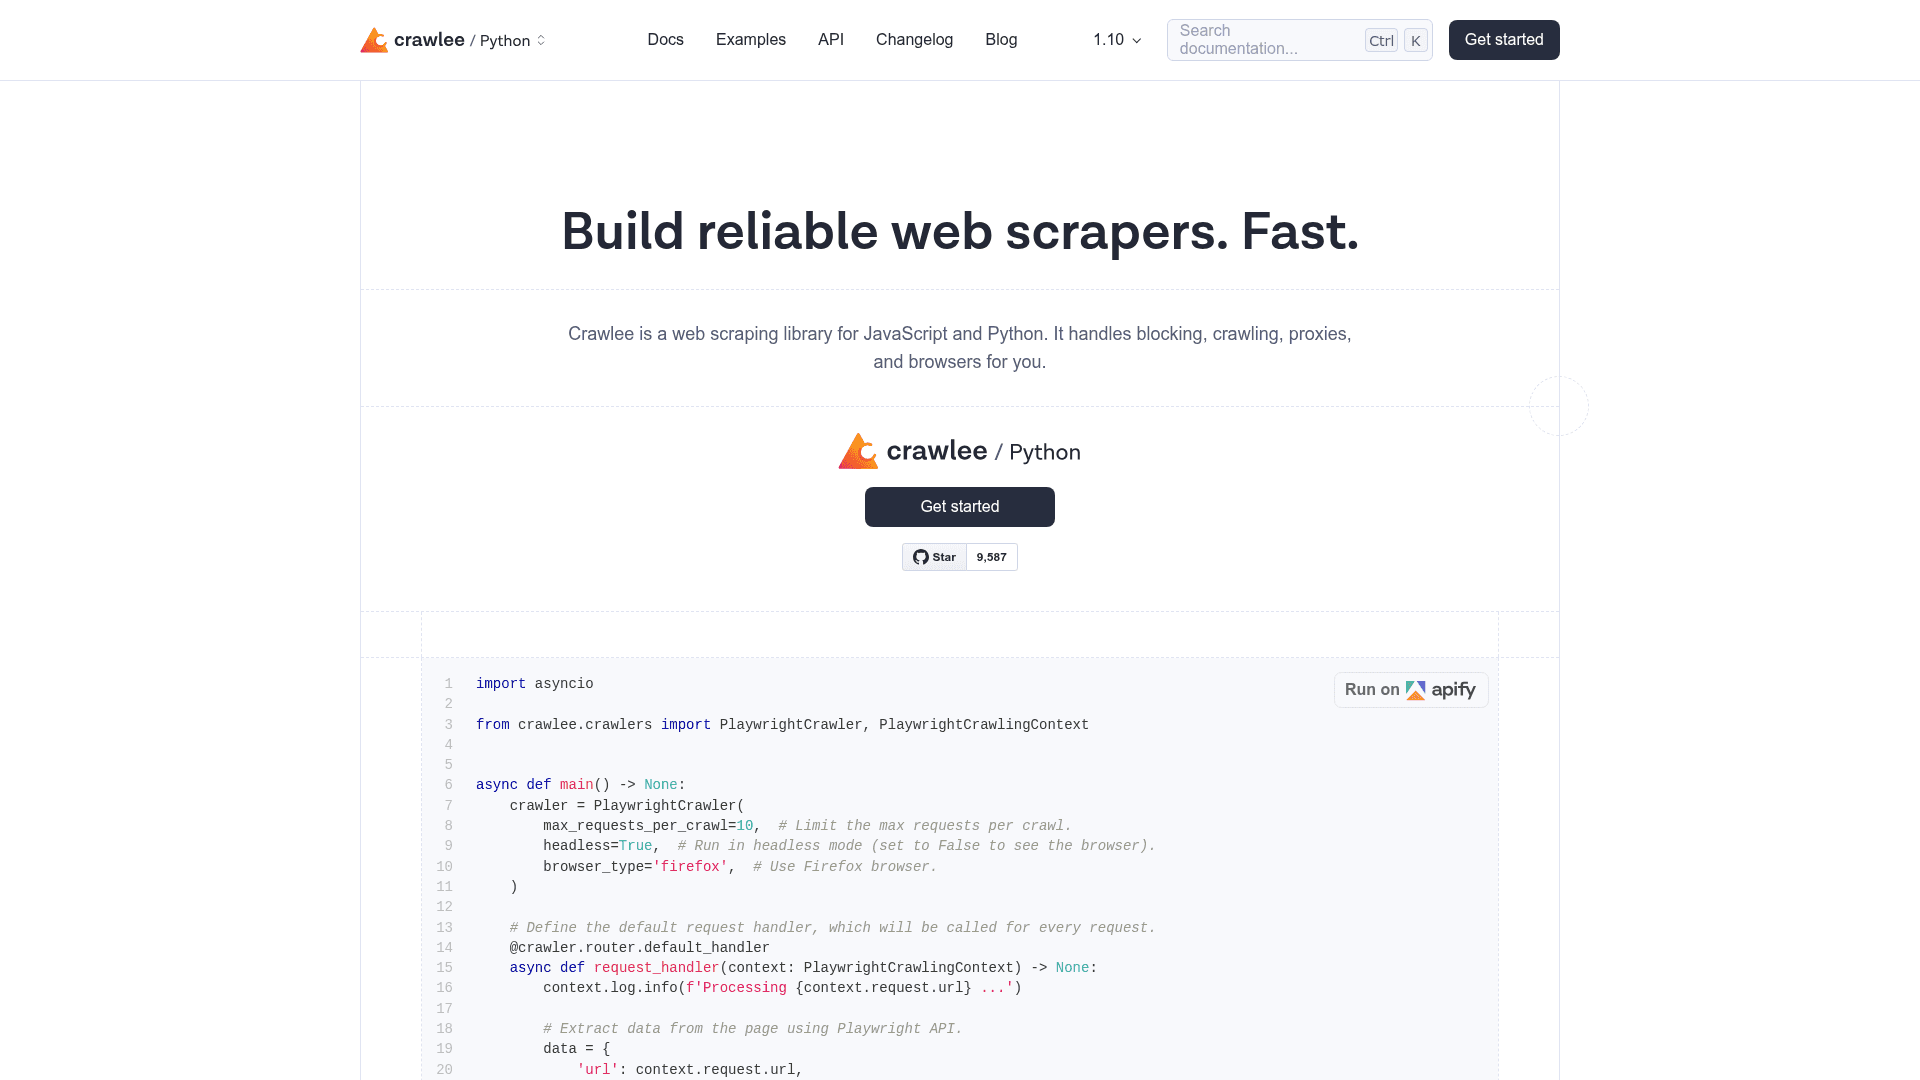
You define a crawler, register a request handler on its router, and run it with a list of start URLs. In the handler you extract data, push it to a dataset, and enqueue discovered links. A run creates a storage/ directory, and results can be exported to CSV or read directly in code. BeautifulSoupCrawler uses an HTTP client and HTML parsing, so it avoids the overhead of a browser. PlaywrightCrawler uses a headless browser for pages that depend on client-side JavaScript. An adaptive Playwright crawler can decide whether JavaScript rendering is needed.
Reliability Features
The documentation lists automatic retries, proxy rotation with session management, and the removal of blocked proxies from the pool. Browser fingerprint generation is configurable. Crawlers scale concurrency automatically based on available system resources. A persistent URL queue lets crawls be paused and resumed, and storage covers both datasets and key-value stores. Utilities for sitemaps, infinite scroll, contact extraction, and blocking large assets are included.
Setup and Deployment
The Crawlee CLI (uvx 'crawlee[cli]' create my-crawler) generates a project from templates. Crawlee runs anywhere, and it can also be deployed to the Apify platform as an Actor using the Apify SDK and CLI. The README compares it with Scrapy, citing its asyncio base, full type hints, and state persistence across interruptions.
Community Discussions
Be the first to start a conversation about Crawlee for Python
Share your experience with Crawlee for Python, ask questions, or help others learn from your insights.
Pricing
Open Source
Crawlee for Python is a free, open-source web scraping and browser automation library licensed under Apache License 2.0.
- Apache License 2.0
- Unified interface for HTTP and headless browser crawling
- Automatic parallel crawling based on available system resources
- Proxy rotation and session management
- Persistent URL queue and pluggable storage
Capabilities
Key Features
- Unified API for HTTP and headless browser crawling
- Adaptive crawler that decides whether JS rendering is needed
- Automatic concurrency scaling based on system resources
- Proxy rotation and session management
- Configurable browser fingerprint generation
- Automatic retries on errors or blocking
- Persistent request queue with pause and resume
- Datasets and key-value stores for data and files
- Request router and middleware
- Scraping utilities for sitemaps, infinite scroll, and contact extraction
- CLI project templates
- Full type hint coverage