
Flide
Open-source inference engine that serves decision models through the /v1/systemone API using exact state forking.
At a Glance
Self-hosted Flide inference engine released under the Apache License 2.0; install with pip and serve on your own GPUs.
Engagement
Available On
Listed Nov 2026
About Flide
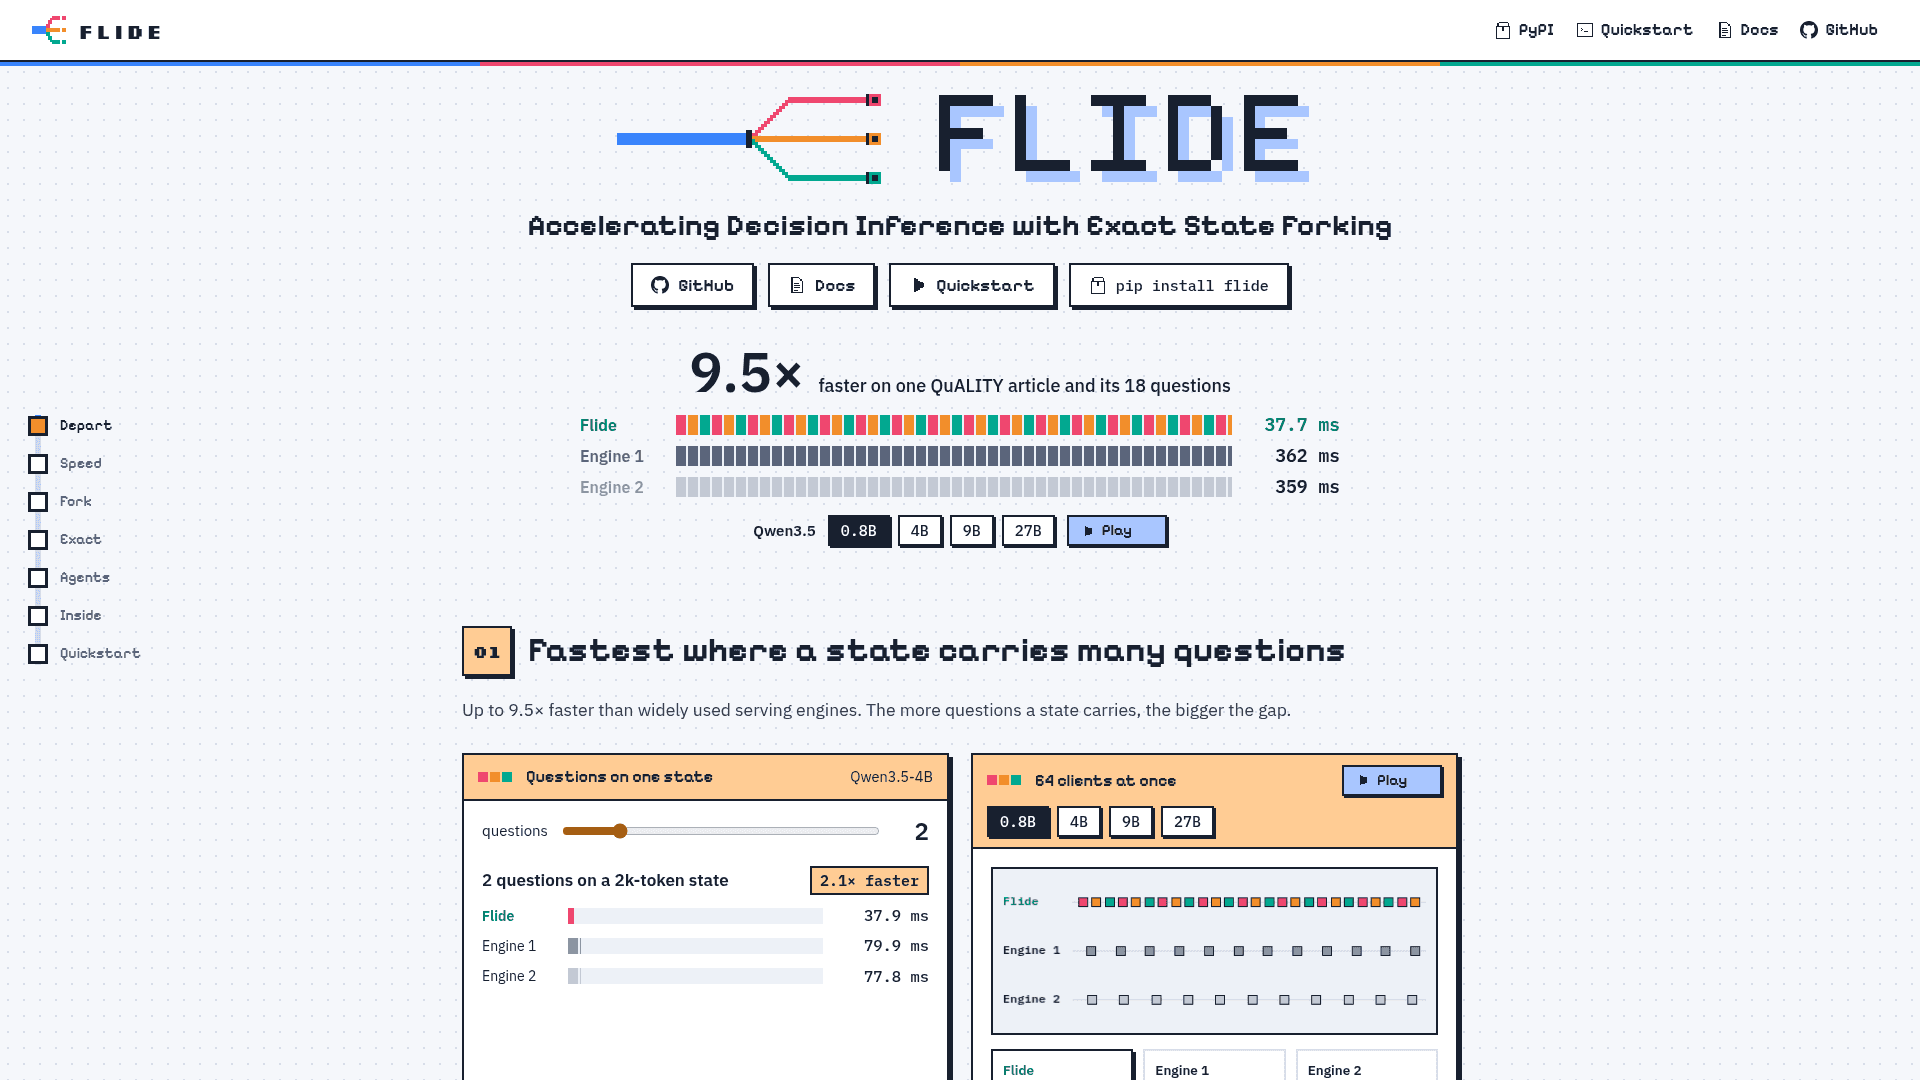
Flide is an open-source inference engine for decision models, published by OmniJev under the Apache-2.0 license and installable from PyPI. It reads a shared context once and forks that state into every question asked about it, serving the /v1/systemone API. The project says it is up to 9.5 times faster than vLLM and SGLang on its benchmarks.
What It Is
Flide is serving infrastructure for Jev-style decision models. A request carries a "state" (for example, a support ticket) and a set of named questions, such as a choice among criteria or a yes/no check. Flide returns a probability for every option. It serves Qwen3.5 and Gemma 4 chat models as well as many community decision-model families, with text, image and, for some models, video inputs.
How Exact State Forking Works
Instead of recomputing the shared context for each question, Flide computes it once and forks it into all of its questions, so each question reads the state in place. The project says each answer matches what the model gives when asked alone. It reports staying within 1.1 points of a float32 reference. A --batch-invariant option gives a request the same bits however it is batched. Hybrid models with Gated DeltaNet layers start each question from the exact shared-context state.
Agents and Throughput
With --session-cache-gb, Flide keeps states from earlier requests so an agent's next step reads only new tokens. Requests of any mix run as one flat token stream replayed by CUDA graphs, and --frontends 2 runs HTTP, rendering and tokenizing in separate processes for many clients. The repository includes an email triage demo that, per the README, tags 10,000 emails with eight questions each in 28 seconds on one H200.
Setup Path
Install with pip install flide, then run flide serve --model <model> and send requests to http://localhost:8000/v1/systemone. Prebuilt kernels cover A40, A10, RTX 30, H100 and H200 GPUs, and --quantize fp8 runs Qwen3.5 in FP8 on Ada, Hopper and Blackwell GPUs. The README lists Python 3.10+ and PyTorch 2.12+.
Community Discussions
Be the first to start a conversation about Flide
Share your experience with Flide, ask questions, or help others learn from your insights.
Pricing
Open Source (Apache-2.0)
Self-hosted Flide inference engine released under the Apache License 2.0; install with pip and serve on your own GPUs.
- Apache License 2.0 (OSI-approved)
- Install via pip install flide
- Self-hosted; GPU/hardware costs are external
- Serves the /v1/systemone API
Capabilities
Key Features
- Exact state forking: one pass for a state and all its questions
- /v1/systemone API returning a probability for every option
- Batch-invariant mode for identical bits under any batching
- Session cache to resume agent steps from saved states
- FP8 quantization for Qwen3.5 on Ada, Hopper and Blackwell GPUs
- Multimodal inputs (text, images, video) depending on model
- Multi-process frontends for many concurrent clients
- Prebuilt kernels for A40, A10, RTX 30, H100 and H200
- flide verify to check exact forking on your own model
- LoRA adapters served as they are