Hister
Hister is a self-hosted, private search engine that indexes the full content of web pages you visit and local files you keep, making them searchable from a web interface, terminal, or AI assistant via MCP.
At a Glance
Free and open-source under AGPLv3. Self-host on your own machine or server with no usage fees.
Engagement
Available On
Alternatives
Listed Sep 2026
About Hister
Hister is a self-hosted personal search engine built in Go, licensed under AGPLv3, and developed by asciimoo. It indexes the full text of web pages you visit and local files you store, keeping everything on a server you control — with no telemetry and no mandatory cloud service. The project is actively maintained on GitHub and available as a binary, Docker image, Homebrew package, or Nix derivation.
What It Is
Hister sits in the category of personal knowledge retrieval tools. Its core job is to build a private, full-content search index from the pages you browse and the files you keep, then let you find that information again through multiple interfaces: a web UI, a terminal client, a CLI, an HTTP API, and an MCP server for AI assistants. Unlike bookmarking tools or browser history, Hister stores extracted document content alongside the index and displays it as a readable preview in search results, so you can read the page without revisiting the original URL.
How Indexing Works
Content enters Hister through several collection paths:
- Browser extensions (Chrome and Firefox) capture pages as you visit them and send content to your configured Hister server.
- File watching monitors local directories and indexes supported document formats automatically.
- History and bookmark import brings in existing browser data, archives, and supported reading services.
- Website crawler indexes individual URLs or runs persistent, resumable crawls with scope rules and optional browser backends.
Once collected, Hister extracts structured content using built-in extractors, builds a full-text index (with optional language-aware indexes), and stores a readable preview of each document. Skip and priority rules let you control what gets indexed and how results are ranked. Versioning can retain earlier document content when pages change.
Search and Query Capabilities
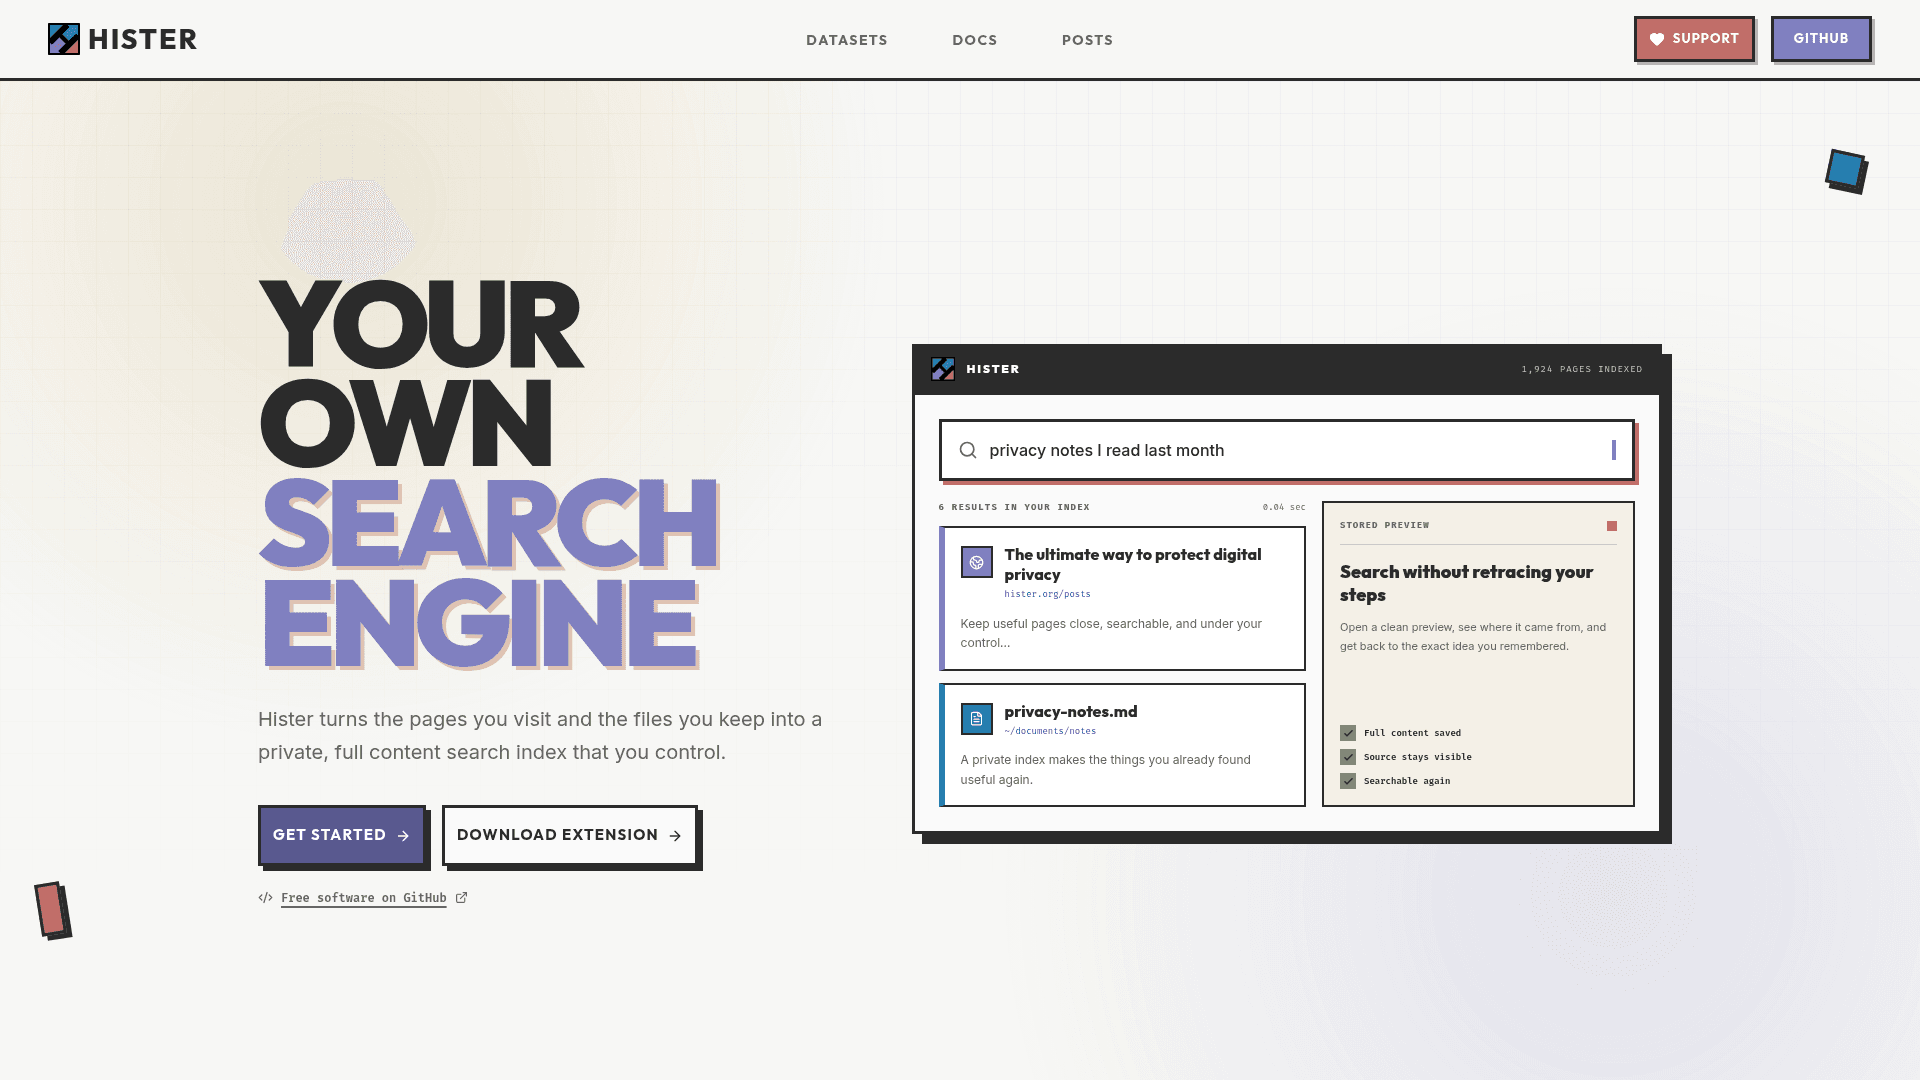
Hister's query language supports field filters, quoted phrases, wildcards, negation, date ranges, result priorities, and user-defined query aliases. Searches run against the full text of indexed documents, not just titles and URLs. Optional semantic search sends document text to an embeddings endpoint you configure, enabling meaning-based retrieval alongside keyword search. Results include a stored preview panel so you can read the content in context without leaving the search interface.
Deployment and Architecture
A single binary with no required configuration can run a local personal setup. For shared or server deployments, Hister supports SQLite or PostgreSQL, multi-user access with scoped document ownership, authentication tokens, and TLS with reverse proxy support. Docker Compose and Nix configurations are documented. The MCP server endpoint lets AI assistants query the index, retrieve previews, and access history through an authenticated connection.
Update: v0.20.0
The latest release is v0.20.0, published on 2026-09-24, with the repository last pushed on 2026-09-24. The project was created in January 2026 and has accumulated over 5,600 GitHub stars and 240 forks as of the last recorded update. The roadmap published on the support page outlines three major planned directions: federation and distributed search between trusted Hister instances, content-specific extractors for more file and web formats, and thematic pre-indexed importable databases built from public datasets such as the Open Search Foundation and the Internet Archive.
Privacy Model
Hister's privacy design is explicit: the server has no telemetry and does not phone home. The browser extension sends indexed content only to the Hister server the user configures, with the only external connection being optional favicon downloads. Optional semantic search requires sending document text to a remote embeddings endpoint, which the user selects and enables deliberately. The source code is public and auditable under AGPLv3.
Community Discussions
Be the first to start a conversation about Hister
Share your experience with Hister, ask questions, or help others learn from your insights.
Pricing
Open Source
Free and open-source under AGPLv3. Self-host on your own machine or server with no usage fees.
- Full text indexing of web pages and local files
- Browser extensions for Chrome and Firefox
- Web interface, terminal client, CLI, and HTTP API
- MCP server for AI assistant integration
- Multi-user support
Capabilities
Key Features
- Full text indexing of visited web pages and local files
- Browser extensions for Chrome and Firefox
- Self-hosted with no telemetry or mandatory cloud
- Powerful query language with field filters, phrases, wildcards, negation, date ranges, and aliases
- Optional semantic search via configurable embeddings endpoint
- Website crawler with scope rules and resumable jobs
- Browser history and bookmark import
- Local file and directory watching
- Stored document previews alongside search results
- Web interface, terminal client, CLI, and HTTP API
- MCP server for AI assistant integration
- Multi-user support with scoped document ownership
- SQLite and PostgreSQL backends
- Docker, Nix, and Homebrew installation options
- Skip and priority indexing rules
- Content versioning
- Language-aware indexes