
Humming
A JIT-compiled GEMM kernel library for quantized inference on NVIDIA GPUs, supporting dense and MoE GEMM.
At a Glance
Humming JIT-compiled GEMM kernel library for quantized inference, released under the Apache License 2.0.
Engagement
Available On
Alternatives
Listed Oct 2026
About Humming
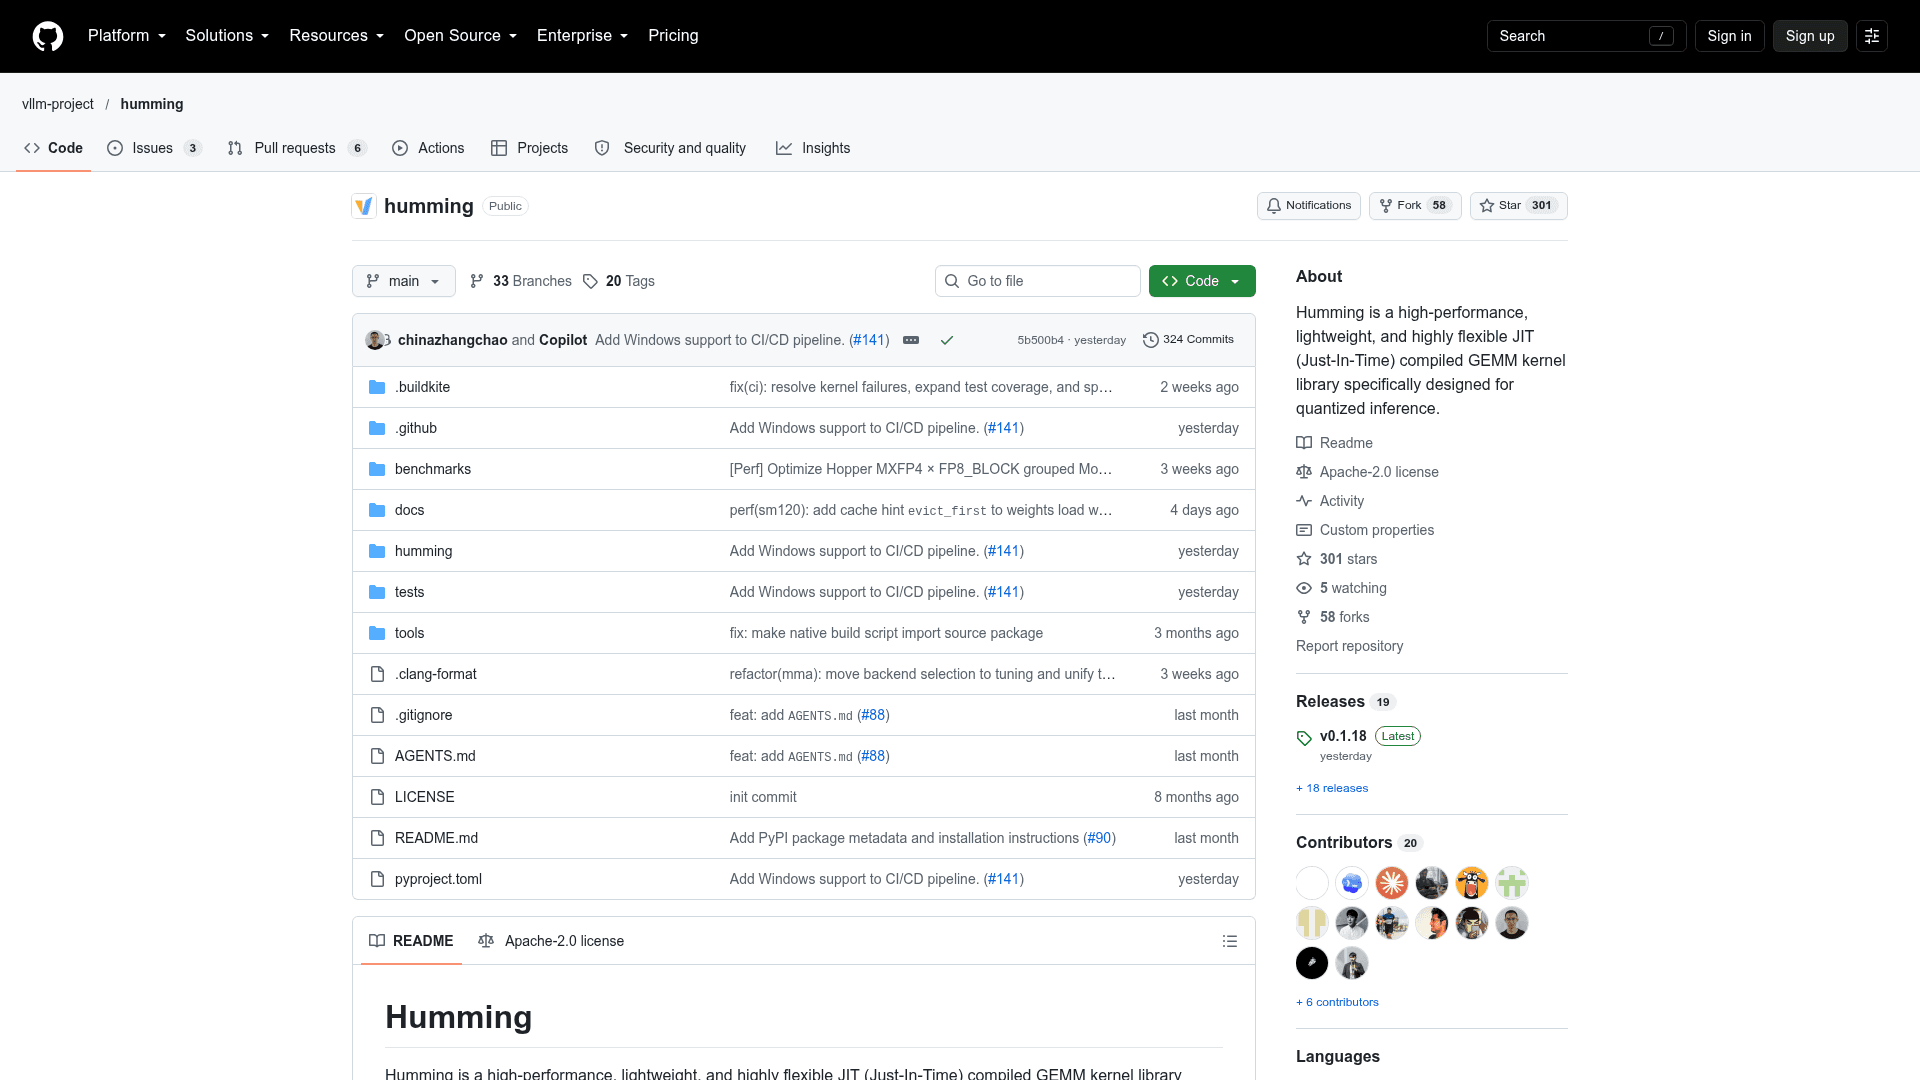
Humming is an open-source library from the vllm-project organization that provides JIT (Just-In-Time) compiled GEMM kernels for quantized inference. It targets NVIDIA GPUs from SM75 (Turing) onward and requires only PyTorch and NVCC. The latest release listed is v0.1.18.
What It Is
Humming is a kernel library that runs quantized matrix multiplication for neural network inference. Developers define a layer with a weight configuration (for example int6), load an unquantized weight, transform it into Humming's format, and call the layer to run quantized GEMM on CUDA devices. Kernels are prepared automatically, and a tuning configuration is optional.
Quantization and Hardware Coverage
The README documents support for any weight type under 8 bits across FP16, BF16, FP8, FP4 and INT8/INT4 activations, provided the activation's dynamic range covers the weight type. It covers several quantization strategies and scale types (BF16, FP16, E4M3, E5M2, UE8M0), and both dense and MoE GEMM. A support matrix maps activation types to minimum GPU architectures, such as SM75+ for FP16 and SM120+ for FP4, and to supported weight formats including symmetric integers, integers with dynamic zero point, and arbitrary signed floating-point types.
Setup Path
Install with pip as humming-kernels, with optional extras for CUDA 12 or CUDA 13, or install from source via GitHub. The README describes the package as around 100 KB and says it is inspired by DeepGEMM, Marlin, lmdeploy's GEMM kernel, and CUTLASS.
Community Discussions
Be the first to start a conversation about Humming
Share your experience with Humming, ask questions, or help others learn from your insights.
Pricing
Open Source
Humming JIT-compiled GEMM kernel library for quantized inference, released under the Apache License 2.0.
- Apache License 2.0
- Install via pip install humming-kernels
- Dense GEMM and MoE GEMM
- Supports NVIDIA GPUs SM75+
- Requires only PyTorch and NVCC
Capabilities
Key Features
- JIT-compiled GEMM kernels for quantized inference
- Weight types under 8-bit with FP16/BF16/FP8/FP4/INT8/INT4 activations
- Dense GEMM and MoE GEMM support
- Multiple quantization strategies and scale types (BF16, FP16, E4M3, E5M2, UE8M0)
- Supports NVIDIA GPUs SM75 and newer
- Minimal dependencies: PyTorch and NVCC
- Optional kernel tuning configuration with automatic selection by default