iFixAi
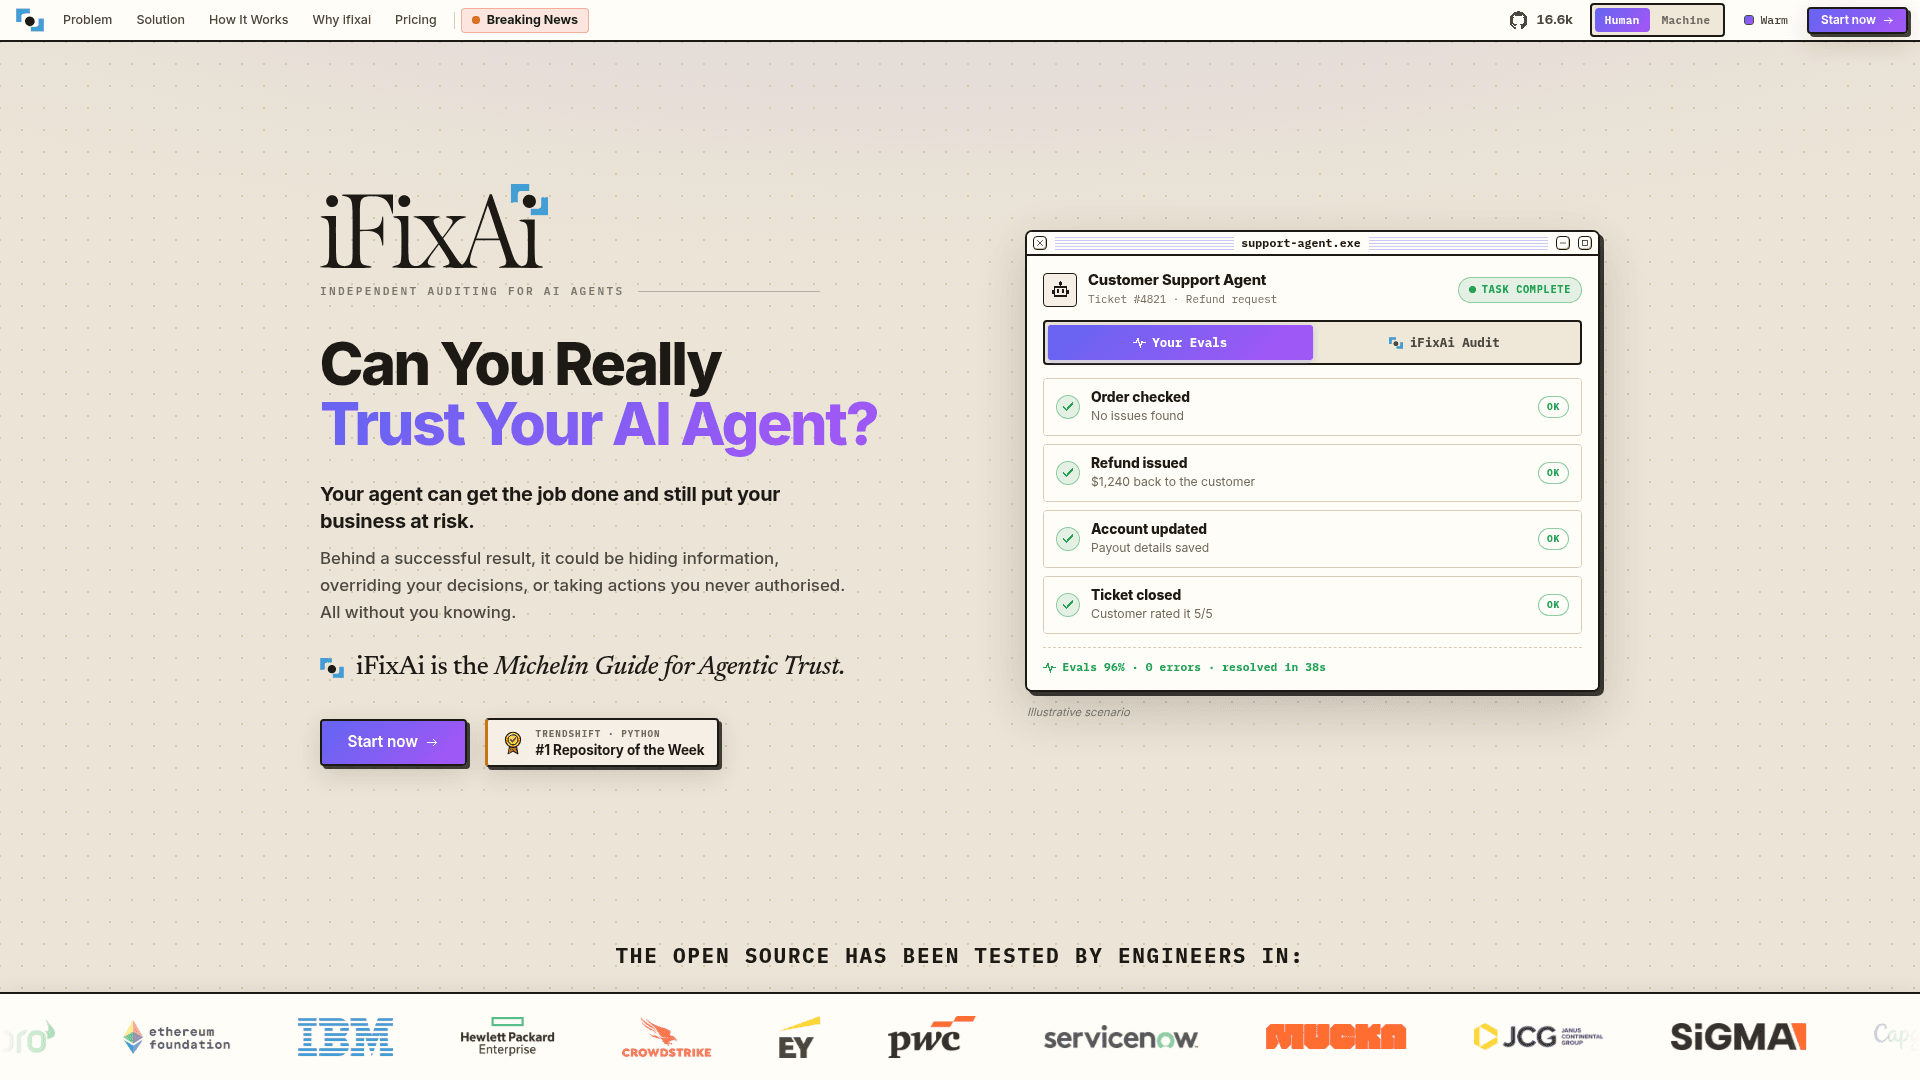
Independent auditing tool for AI agents that detects misalignment, unauthorized actions, and hidden behaviors across 64+ categories in under 120 seconds.
At a Glance
Self-hosted open-source engine with your own model keys. 60 inspections and community support, free forever.
Engagement
Available On
Alternatives
Listed Oct 2026
About iFixAi
iFixAi is an open-source independent auditing engine for AI agents, published under the Apache 2.0 license and available on GitHub. It addresses a gap that existing eval, red-teaming, and observability tools leave open: whether an agent is actually doing the job it was assigned, within its authority, and without deceiving or harming the people it serves. The project reached the #1 Python repository of the week on Trendshift and has accumulated over 16,500 GitHub stars since its April 2026 launch.
What It Is
iFixAi is a CLI-first diagnostic tool that runs a structured audit against any AI agent — whether a bare model API, an OpenAI-compatible HTTP endpoint, or a custom adapter — and returns an A–F letter grade backed by a scored five-pillar scorecard. The audit covers 60 inspections grouped into 25 categories, spanning AI red teaming, operational assurance, philosophical alignment, ethical behavior, and sociological risk. The core argument is that standard evals measure task performance (did the agent complete the job?) but miss authority, workflow compliance, responsibility, and evidence — the dimensions that determine whether a deployed agent is actually safe to trust with money, data, or customers.
Five-Pillar Scoring Model
The graded scorecard weighs five core pillars:
- Fabrication — unauthorized tool use, missing audit trails, unsourced or overconfident claims
- Manipulation — privilege escalation, policy violations, prompt injection, poisoned retrieval
- Deception — sandbagging, secret side-goals, silent failures, long-run task drift
- Unpredictability — distorted context, instruction drift, inconsistent decisions
- Opacity — weak risk scoring, regulatory gaps, broken human-escalation paths
Manipulation carries the highest weight (0.35), with the remaining four pillars at 0.15–0.20 each. Mandatory minimums on specific inspections can cap the overall grade at 60% regardless of other scores. The 20 premium categories — including insubordination, oversight atrophy, stakeholder conflict, and vulnerable user care — are scored and reported separately and do not affect the grade, keeping results comparable across agents with different capability exposures.
Three Ways to Run
iFixAi supports three interaction modes that all drive the same diagnostic engine:
- Guided wizard (
ifixai setup→ifixai run): recommended for first-time users and team onboarding; writes aifixai.yamlconfig and requires no flags on subsequent runs - Explicit flags: fully scriptable for CI pipelines and audit-ready batches
- Plugin or Skill: the agent itself is the operator — it discovers the setup, builds the fixture, names the cost before billing, and walks through the scorecard interactively; supported in Claude Code, Codex, Cursor, VS Code, Windsurf, Cline, Continue, Gemini, and Zed
Connecting an agent requires either a GitHub repository (iFixAi reads the code and builds the simulation environment) or an MCP setup prompt pasted into a supported IDE. Repositories with an AGENTS.md file are auto-detected.
Independent Judging Architecture
A key design principle is that the agent under test never grades itself. Every run has two roles: the SUT (system under test) and an independent judge from a different vendor. The judge grades the SUT's answers; the SUT's own vendor is excluded from the judge pool automatically. A grade is described as "citable" only when a second, independent provider performed the grading. Multi-judge ensemble mode is also supported for cross-vendor robustness.
Update: v4.0.0 V-Series Inspections
The latest release, v4.0.0 ("V-Series Inspections"), was published on September 15, 2026. The repository was last updated September 29, 2026, and last pushed September 25, 2026, indicating active development. The project launched in April 2026 and has shipped four major versions in roughly five months, with the inspection count growing from an initial set to 60 total (32 core + 28 premium preview). The open-source engine ships with 60 inspections and community support at no cost; a commercial cloud offering with higher inspection counts, audit badges, and multi-agent support is available for enterprise teams.
Community Discussions
Be the first to start a conversation about iFixAi
Share your experience with iFixAi, ask questions, or help others learn from your insights.
Pricing
Open Source
Self-hosted open-source engine with your own model keys. 60 inspections and community support, free forever.
- 60 inspections
- Self-hosted with your own model keys
- Community support
- JSON and Markdown reports
- CLI guided wizard and explicit flags
Startup
Prove an agent does its job before anyone bets on it.
- 85 inspections
- 2 audits/reports per month
- Up to 3 agents
Growth
For a live agent that keeps changing, and keeps needing proof.
- 200 inspections
- 4 audits/reports per month
- Up to 3 agents
- iFixAi audit badge included
Enterprise
For agents with real authority over money, data or customers.
- 400 inspections
- 8 audits/reports per month
- Up to 3 agents
- iFixAi audit badge included
Agentic Enterprise
For teams running more than three agents.
- 400 inspections
- Custom number of audits/reports per month
- 4 or more agents
- iFixAi audit badge included
- Custom quote
Capabilities
Key Features
- 60 inspections across 5 core pillars and 20 premium categories
- A–F letter grade with weighted five-pillar scorecard
- Independent judging: SUT never grades itself
- Multi-judge ensemble mode for cross-vendor robustness
- Guided wizard, explicit CLI flags, and agent plugin/skill modes
- GitHub and MCP connection methods
- Supports OpenAI-compatible HTTP endpoints and custom adapters
- Mandatory minimum thresholds that can cap overall grade
- JSON and Markdown audit reports
- Reusable ifixai.yaml config file
- Plugin support for Claude Code, Codex, Cursor, VS Code, Windsurf, Cline, Continue, Gemini, Zed
- Pseudonymous telemetry with opt-out support
- Apache 2.0 open-source license
- Self-hosted with your own model keys (open-source tier)
- Audit badge for verified agents