
llama-modchip
Kernel patches, quantization transcoders, and runtime tools for running large Mixture-of-Experts models such as DeepSeek-V4-Flash 284B and 30B MoEs on CPU-only systems.
At a Glance
Self-hosted llama-modchip kernel patches, quantization transcoders and runtime tools, licensed under Apache License 2.0.
Engagement
Available On
Alternatives
Listed Nov 2026
About llama-modchip
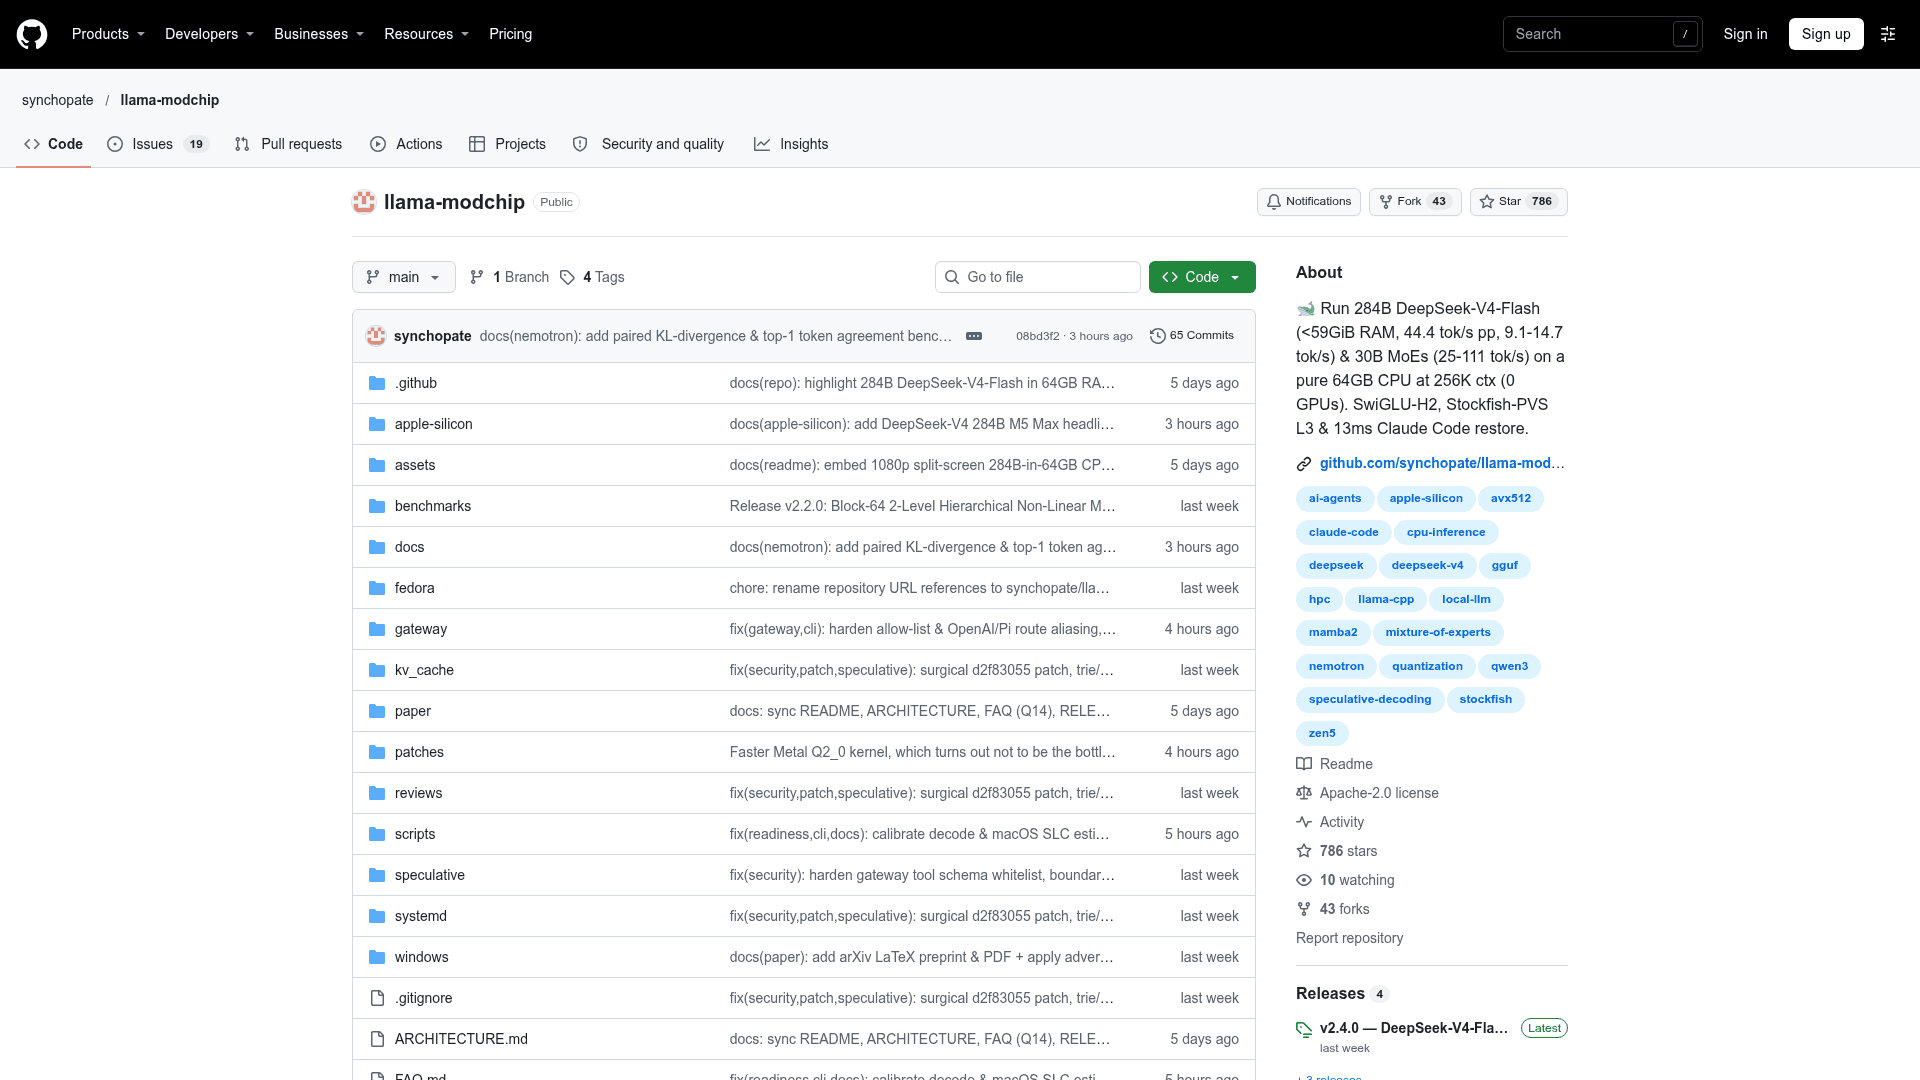
llama-modchip is an open-source set of ggml/llama.cpp kernel patches, quantization transcoders, and runtime tools published by synchopate. It is designed to run sparse Mixture-of-Experts checkpoints entirely in system RAM on x86_64 and ARM64 processors, including a 284B DeepSeek-V4-Flash build that the README says fits in 64 GB of RAM. The latest listed release is v2.4.0.
What It Is
llama-modchip targets people who want to run large MoE language models locally without a GPU. It combines patched llama.cpp/ggml kernels, custom GGUF quantization formats (Fractal-64 and Fractal-MXFP4), and a unified modchip command-line tool. Supported model families listed include DeepSeek-V4-Flash, NVIDIA Nemotron-3.5-30B-A3B, Qwen3-30B-A3B and Qwen3-14B, and Nemotron-H-8B.
How the Workflow Runs
On Linux and macOS, cloning the repository and running ./modchip chat performs automated setup and opens a chat. The same CLI offers a web chat with a telemetry HUD, a benchmark scorecard, a quality and tool-calling evaluation gate, a quantizer that transcodes BF16, Q4_0, or UD-IQ1_S GGUFs, and a launcher for Claude Code wired to the local engine. A prebuilt Linux x86_64 server binary is also available with models hosted on Hugging Face. Windows 10/11 has a hybrid GPU and CPU pack that detects cores, RAM, and VRAM and sets the MoE CPU split.
Performance Techniques
The README describes multi-column register and cache tiling for prefill, register-stationary MQA8 FlashAttention, and non-temporal MoE streaming to protect KV cache lines in L3. It also describes a small n-gram drafter (Stockfish-PVS v2) for self-speculative decoding and /dev/shm KV slot snapshots for fast context restore. Throughput figures in the README are the author's and community-submitted measurements on specific hardware.
Compatibility Note
Fractal-64 models use a custom tensor type (GGML_TYPE_Q2_0, ID 40), so unpatched llama.cpp, Ollama, or LM Studio will reject them. Users need the modchip tooling or the included prebuilt binary.
Hardware Coverage
Documented platforms include AMD Zen 5, Zen 4 multi-CCD, and Zen 3 chips, Intel Core processors, Apple Silicon with Metal and NEON, AWS Graviton ARM64, and hybrid CPU plus GPU setups using Vulkan or CUDA. A community leaderboard collects benchmark submissions.
Community Discussions
Be the first to start a conversation about llama-modchip
Share your experience with llama-modchip, ask questions, or help others learn from your insights.
Pricing
Open Source (Apache 2.0)
Self-hosted llama-modchip kernel patches, quantization transcoders and runtime tools, licensed under Apache License 2.0.
- Apache License 2.0 (OSI-approved)
- CPU-first inference of 284B and 30B MoE models with 0 GPUs required
- Windows 10/11 hybrid GPU + CPU MoE pack
- Stockfish-PVS v2 speculative drafter and /dev/shm KV slot restore
Capabilities
Key Features
- CPU-only inference of 284B DeepSeek-V4-Flash in about 64 GB RAM
- Fractal-64 and Fractal-MXFP4 GGUF quantization transcoding
- AVX-512 and AVX2 multi-column prefill tiling kernels
- Register-stationary MQA8 FlashAttention
- Self-speculative drafting with Stockfish-PVS v2 n-gram drafter
- /dev/shm KV slot snapshots for fast agent context restore
- Unified modchip CLI: chat, web, bench, eval, quantize, claude, status, stop
- Terminal chat and dark-mode web chat with live telemetry
- Hybrid GPU plus CPU MoE expert split for Windows (CUDA/Vulkan)
- Apple Silicon Metal and ARM64 NEON support
- Quality and tool-calling evaluation gate
- Community CPU benchmark leaderboard
- Prebuilt Linux x86_64 server binary