EveryDev.ai
Subscribe
Home
Tools

4,741+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents3426
  • Coding2391
  • Infrastructure1055
  • Projects732
  • Marketing662
  • Research612
  • MCP593
  • Analytics538
  • Design533
  • Testing420
  • Security410
  • Data358
  • Prompts260
  • Integration256
  • Communication250
  • Extensions222
  • Voice201
  • Learning193
  • Commerce173
  • DevOps161
  • Web122
  • Finance36
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai © 2026
    1. Home
    2. Tools
    3. AWQ (llm-awq)
    AWQ (llm-awq) icon

    AWQ (llm-awq)

    Model Management
    Featured

    Activation-aware Weight Quantization toolkit for low-bit (INT3/INT4) compression and acceleration of LLMs and multi-modal models.

    Visit Website

    At a Glance

    Pricing
    Open Source

    AWQ core quantization library released under the MIT License; free to use, copy, modify, and distribute.

    Engagement

    Available On

    Linux
    API
    SDK
    CLI

    Resources

    WebsiteGitHubllms.txt

    Topics

    Model ManagementLocal InferenceCompute Optimization

    Alternatives

    llmfitshoehornOpenVINO
    Developer
    MIT HAN LabCambridge, MA

    Listed Oct 2026

    About AWQ (llm-awq)

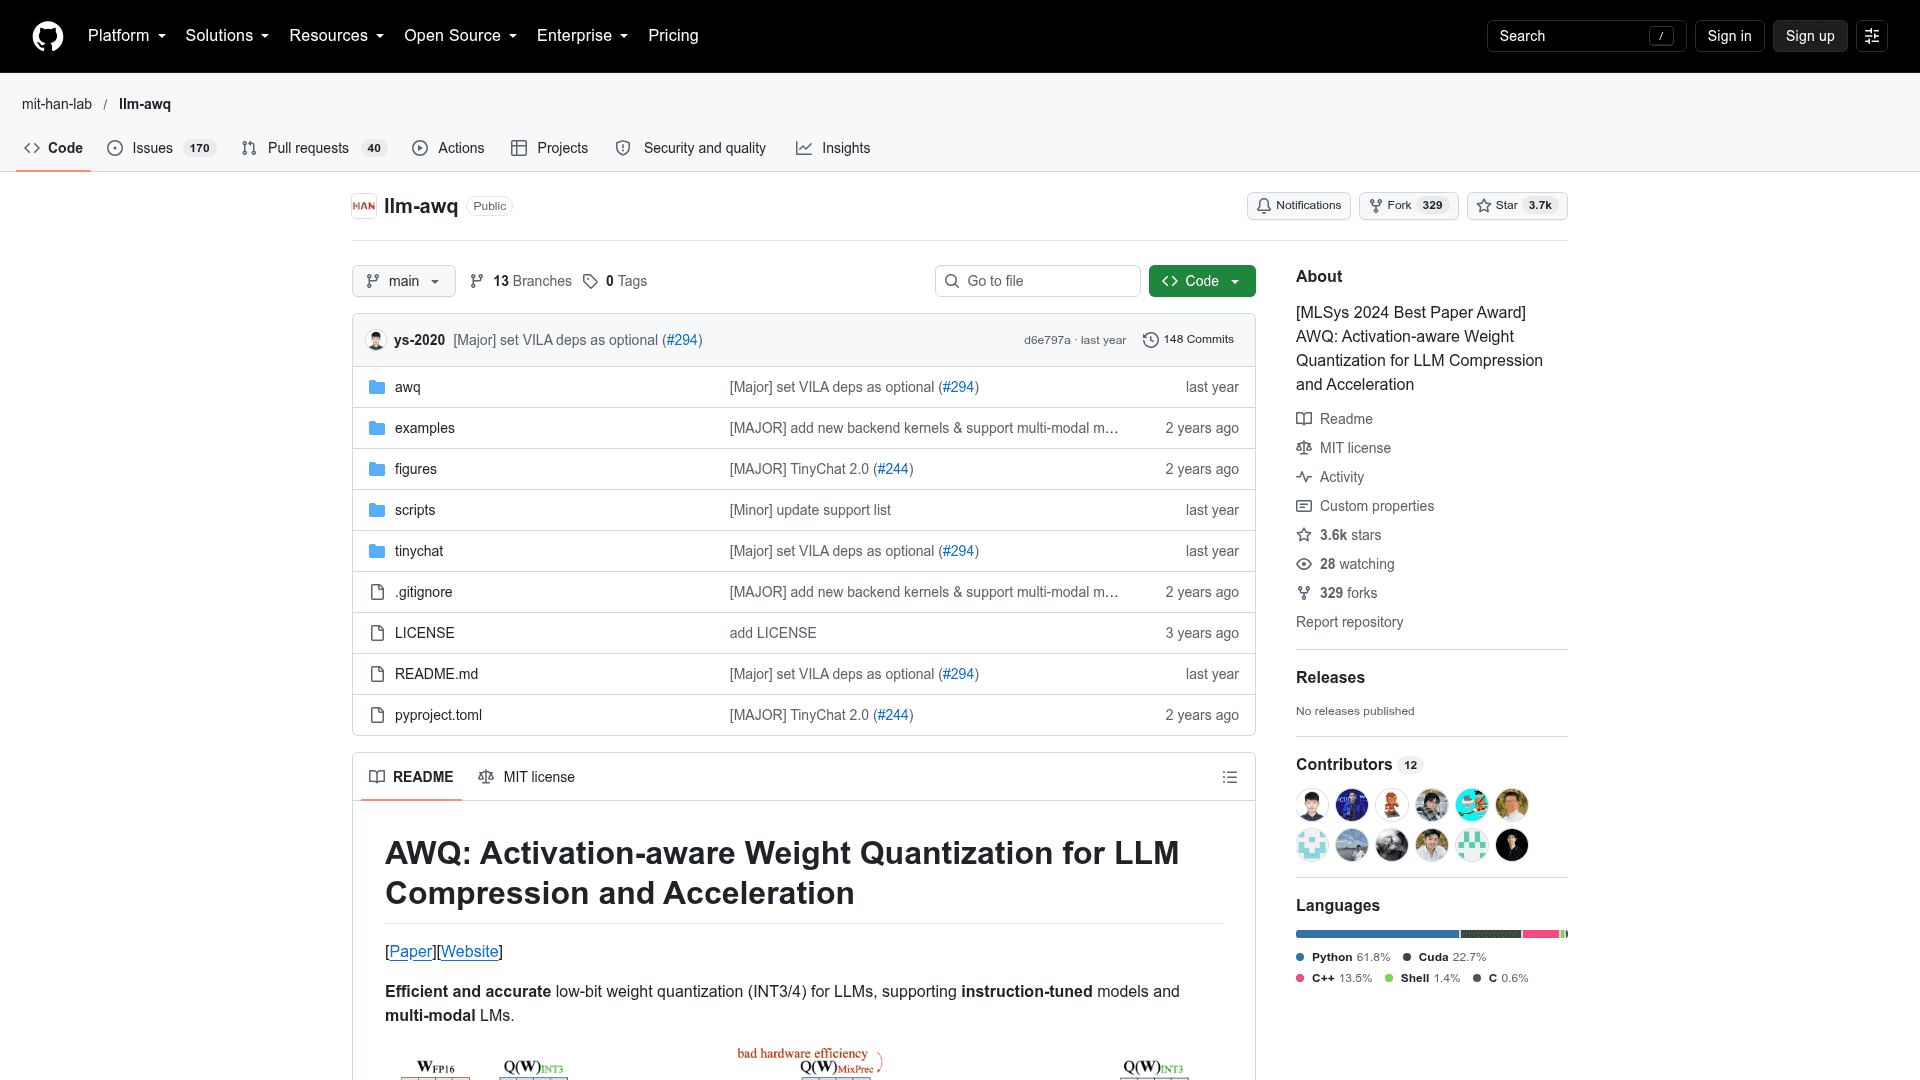
    AWQ (Activation-aware Weight Quantization) is an open-source toolkit from MIT HAN Lab for compressing large language models to low-bit weights (INT3/INT4) and accelerating their inference. It supports instruction-tuned and multi-modal models, and the repository is MIT-licensed. The accompanying paper received the Best Paper Award at MLSys 2024, according to the repository.

    What It Is

    AWQ is a post-training weight quantization method packaged as a Python and PyTorch codebase. It searches for quantization settings that preserve accuracy, then produces real 4-bit weights that reduce GPU memory use. The repo also ships CUDA kernels for W4A16 (4-bit weight, 16-bit activation) inference, covering both context and decoding stages, and a memory-efficient 4-bit Linear layer in PyTorch.

    Workflow and Outputs

    The usage flow runs an AWQ search and saves the results, optionally evaluates the model on WikiText-2 with simulated quantization, and generates real INT4 quantized weights. The quantized model can then be loaded and evaluated with lower GPU memory use. Pre-computed search results are provided in an AWQ model zoo on Hugging Face covering Llama-1/2/3, OPT, CodeLlama, StarCoder, Vicuna, VILA, NVILA, LLaVA, Qwen-2.5 and DeepSeek-R1-Distill families. Models not in the zoo can be quantized by running the search yourself. BF16 precision is also supported.

    TinyChat and Edge Inference

    TinyChat is a companion inference interface built on AWQ for running LLMs and vision-language models on cloud GPUs and resource-constrained edge devices such as NVIDIA Jetson Orin. The README reports W4A16 speedups over FP16 for Llama-3-8B on RTX 4090 (2.7x) and Jetson Orin (2.9x). TinyChat 2.0 is described as improving prefilling speed 1.5-1.7x over the previous version and includes chunk prefilling for multi-round Q&A.

    Ecosystem Integrations

    The README notes AWQ integration in Hugging Face transformers, NVIDIA TensorRT-LLM, vLLM, Hugging Face TGI, LMDeploy, FastChat, Intel Neural Compressor, Amazon SageMaker containers and Google Vertex AI.
    AWQ (llm-awq) - 1

    Community Discussions

    Be the first to start a conversation about AWQ (llm-awq)

    Share your experience with AWQ (llm-awq), ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source (MIT)

    AWQ core quantization library released under the MIT License; free to use, copy, modify, and distribute.

    • MIT License
    • AWQ search for accurate quantization
    • Pre-computed AWQ model zoo
    • Memory-efficient 4-bit Linear in PyTorch
    • Efficient CUDA kernel for fast inference

    Capabilities

    Key Features

    • Activation-aware weight quantization search for INT3/INT4
    • Pre-computed AWQ model zoo
    • Memory-efficient 4-bit Linear in PyTorch
    • W4A16 CUDA kernels for context and decoding stages
    • Support for instruction-tuned and multi-modal models
    • BF16 precision support
    • Chunk prefilling for multi-round Q&A
    • TinyChat edge inference for LLMs and VLMs
    • WikiText-2 evaluation of quantized models

    Integrations

    Hugging Face Transformers
    NVIDIA TensorRT-LLM
    vLLM
    Hugging Face TGI
    LMDeploy
    FastChat
    Intel Neural Compressor
    Amazon SageMaker
    Google Vertex AI
    VILA
    LLaVA
    API Available

    Ratings & Reviews

    No ratings yet

    Be the first to rate AWQ (llm-awq) and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    MIT HAN Lab

    Efficient AI Computing. PI: Song Han

    Cambridge, MA
    9 employees
    Read more about MIT HAN Lab
    WebsiteGitHubX / Twitter
    1 tool in directory

    Similar Tools

    llmfit icon

    llmfit

    A terminal tool that detects your hardware and right-sizes LLM models to your system's RAM, CPU, and GPU, ranking hundreds of models by fit, speed, quality, and context.

    shoehorn icon

    shoehorn

    A CLI tool that quantizes LLM models to fit exactly into your available VRAM using per-tensor mixed-precision assignment, maximizing model quality within your hardware's memory budget.

    OpenVINO icon

    OpenVINO

    Open-source toolkit by Intel for optimizing and deploying deep learning models across CPU, GPU, and NPU hardware targets.

    Browse all tools

    Related Topics

    Model Management

    Tools for managing, versioning, and deploying AI models.

    86 tools

    Local Inference

    Tools and platforms for running AI inference locally without cloud dependence.

    263 tools

    Compute Optimization

    Tools for optimizing computational resources and performance.

    57 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions