
LLM Compressor
Python library for quantizing and pruning large language models into compressed-tensors checkpoints for deployment with vLLM.
At a Glance
LLM Compressor library released under the Apache License 2.0 (OSI-approved), free to use, modify and distribute.
Engagement
Available On
Alternatives
Listed Oct 2026
About LLM Compressor
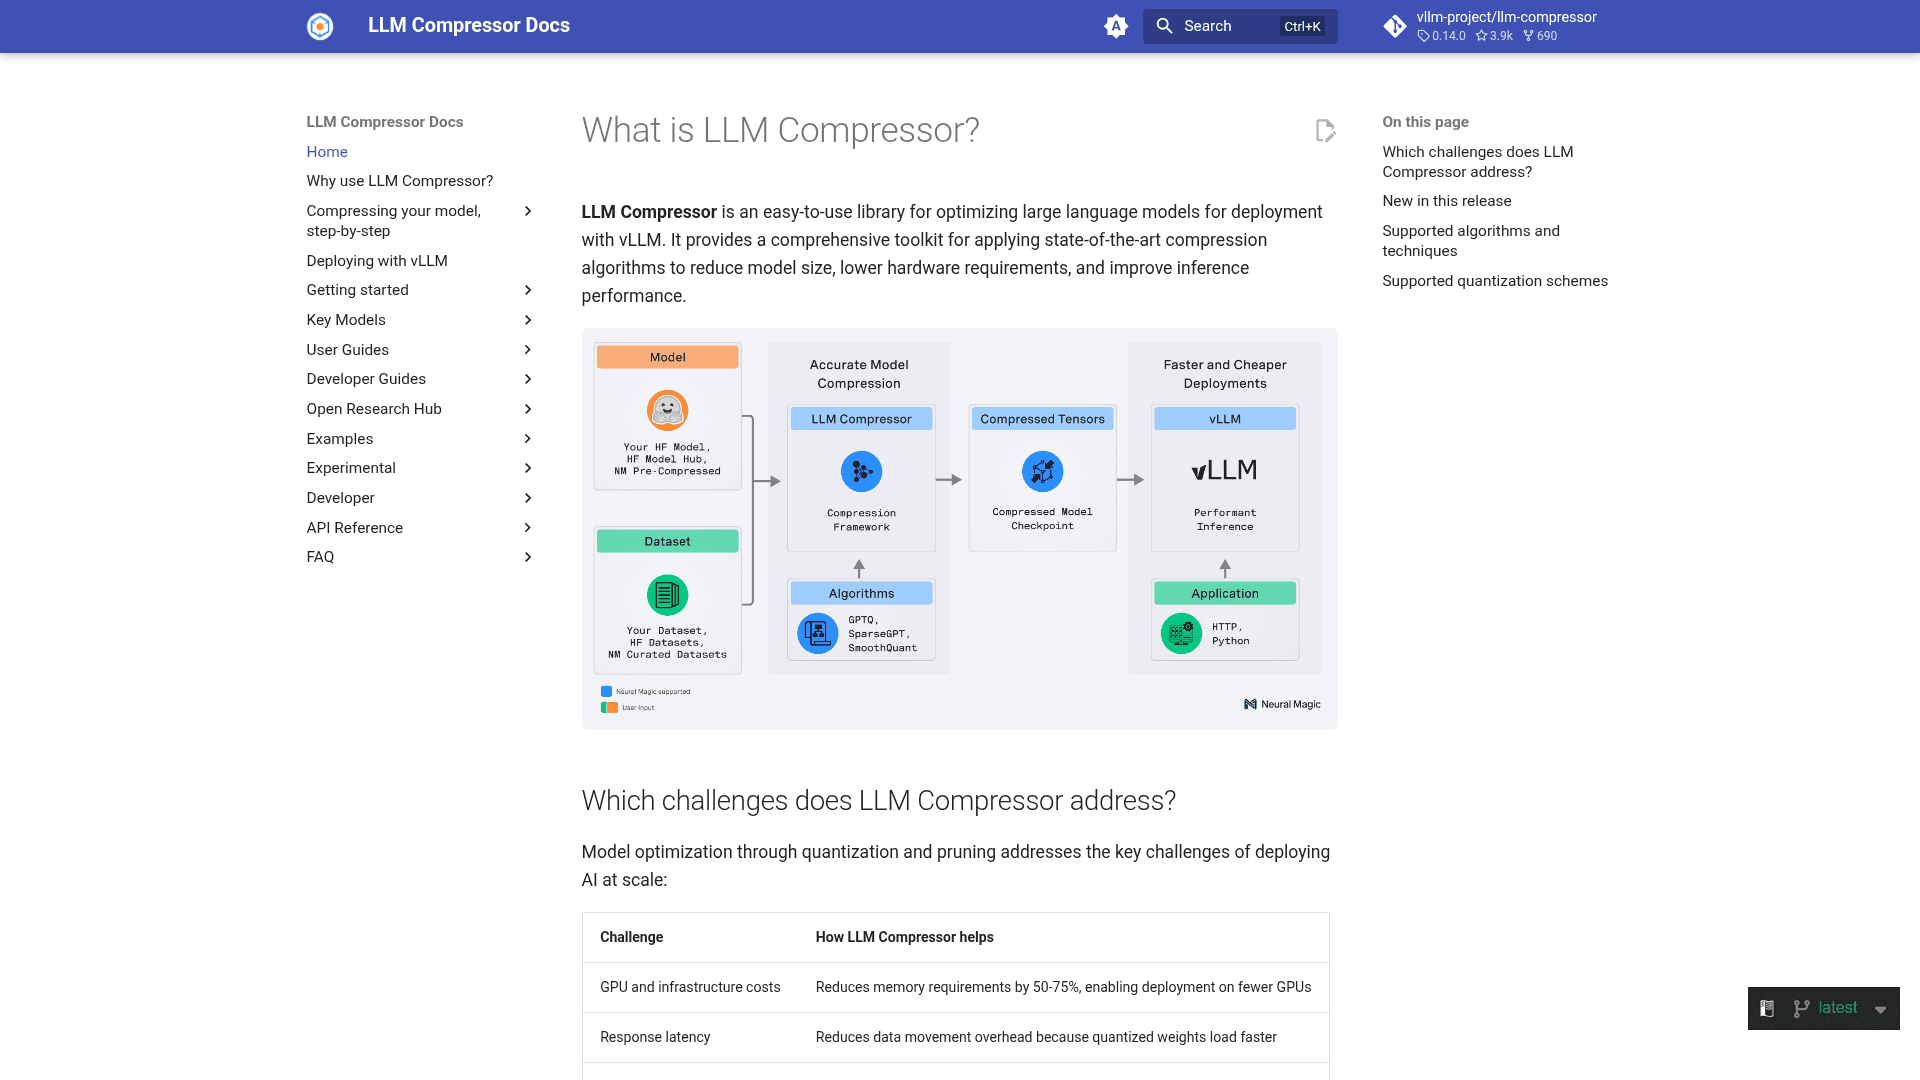
LLM Compressor (llmcompressor) is an open-source Python library from the vLLM project for optimizing large language models for deployment with vLLM. It applies quantization and pruning algorithms to reduce model size and hardware requirements, and saves results in the compressed-tensors format that vLLM can load. The latest documented release is 0.14.0.
What It Is
LLM Compressor is a model-compression toolkit that works with Hugging Face models and repositories. Users select a model, a compression scheme, an algorithm and a calibration dataset, then run the oneshot entrypoint with a recipe such as a QuantizationModifier. The compressed model and tokenizer are saved to disk and can be loaded directly in vLLM. The docs state that quantization and pruning reduce memory requirements by 50-75%, allowing deployment on fewer GPUs.
Algorithms and Schemes
Supported algorithms include round-to-nearest (RTN), GPTQ, AWQ, SmoothQuant, AutoRound, rotation-based transforms (SpinQuant, QuIP), and REAP expert pruning for Mixture-of-Experts models. Supported formats include W4A16/W8A16, W8A8 INT8 and FP8, MXFP8, NVFP4/MXFP4, weight-only microscale variants, and W4AFP8. KV cache and attention quantization are also covered. Sparse compression, including 2of4 sparsity, is documented as no longer supported.
Large and Specialized Models
The library supports distributed (DDP) runs and disk offloading for compressing very large models. It also provides sequential onloading, a model-free post-training quantization entrypoint for checkpoints without a Hugging Face model definition, and examples for MoE, vision-language and audio-language models. Key-model guides cover DeepSeek V4, Kimi, Qwen, Gemma 4, Llama 4 and others.
Update: v0.14.0
The docs list v0.14.0 improvements: a Triton GPTQ kernel (about 15x end-to-end speedup on Llama-3-8B) with batching for MoE models, new NVFP4 observers, a Triton kernel for the MSE observer, REAP support for DDP, and an improved model-free PTQ scheduler.
Community Discussions
Be the first to start a conversation about LLM Compressor
Share your experience with LLM Compressor, ask questions, or help others learn from your insights.
Pricing
Open Source
LLM Compressor library released under the Apache License 2.0 (OSI-approved), free to use, modify and distribute.
- Apache License 2.0
- Quantization algorithms and transforms for weight, activation, KV cache, and attention quantization
- Integration with Hugging Face models and repositories
- Models saved in compressed-tensors format compatible with vLLM
- DDP and disk offloading support for large models
Capabilities
Key Features
- oneshot quantization entrypoint
- Model-free post-training quantization
- GPTQ, AWQ, SmoothQuant, AutoRound, SpinQuant and QuIP algorithms
- REAP expert pruning for MoE models
- Weight, activation, KV cache and attention quantization
- NVFP4, MXFP4, MXFP8, FP8 and INT4/INT8 schemes
- Saves models in compressed-tensors format for vLLM
- DDP and disk offloading for very large models
- Multimodal vision and audio model quantization examples