EveryDev.ai
Subscribe
Home
Tools

4,859+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2464
  • Coding1820
  • Infrastructure853
  • Projects697
  • Research597
  • MCP566
  • Marketing487
  • Analytics474
  • Design401
  • Testing392
  • Data363
  • Security306
  • Integration251
  • Communication239
  • Prompts234
  • Extensions217
  • Commerce167
  • DevOps163
  • Voice162
  • Web118
  • Learning113
  • Finance33
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. llm-d
    llm-d icon

    llm-d

    Container Orchestration
    Featured

    Open-source, Kubernetes-native distributed LLM inference serving stack that orchestrates vLLM and SGLang across accelerators.

    Visit Website

    At a Glance

    Pricing
    Open Source

    llm-d is an open-source, Kubernetes-native stack for distributed LLM inference, licensed under Apache License 2.0 and free to use, modify and distribute.

    Engagement

    Available On

    Linux
    API

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    Container OrchestrationAI InfrastructureCompute Optimization

    Alternatives

    KAI SchedulerKarpenterdstack
    Developer
    llm-dEst. 2025

    Listed Oct 2026

    About llm-d

    llm-d is an open-source distributed inference serving stack for Kubernetes, hosted as a CNCF Sandbox project and founded by Red Hat, Google Cloud, IBM Research, CoreWeave, and NVIDIA. It runs model servers such as vLLM and SGLang across a cluster and adds routing, cache management, and scaling on top. The latest release listed on GitHub is v0.10.0.

    What It Is

    llm-d sits above model servers and turns single-node engines into production-grade distributed inference on infrastructure teams already run. It is described as engine- and hardware-agnostic, targeting GPUs, Google TPUs, Intel XPUs, and CPUs, and is aimed at agentic pipelines, LLMs, multimodal models, and high-throughput serving.

    Well-Lit Paths

    The project ships Well-Lit Paths: tested, benchmarked deployment recipes for common production patterns. Each path includes Helm charts and Kustomize manifests, key tuning knobs, sample workloads and benchmarks against baselines, and monitoring and observability configuration. Paths cover an optimized baseline, predicted-latency routing, precise prefix-cache-aware routing, tiered prefix cache, prefill/decode disaggregation, wide expert parallelism for MoE models, flow control and fairness, and workload autoscaling.

    Capabilities by Theme

    • Intelligent routing with prefix-cache and load-aware balancing, plus predicted-latency scheduling.
    • KV-cache management with tiered offloading to CPU or disk and global indexing of cache state.
    • Serving large models through prefill/decode disaggregation and wide expert parallelism.
    • Operational controls such as multi-tenant flow control and SLO-aware autoscaling.
    • Batch processing through OpenAI-compatible Batch APIs and asynchronous processing.

    Performance Claims

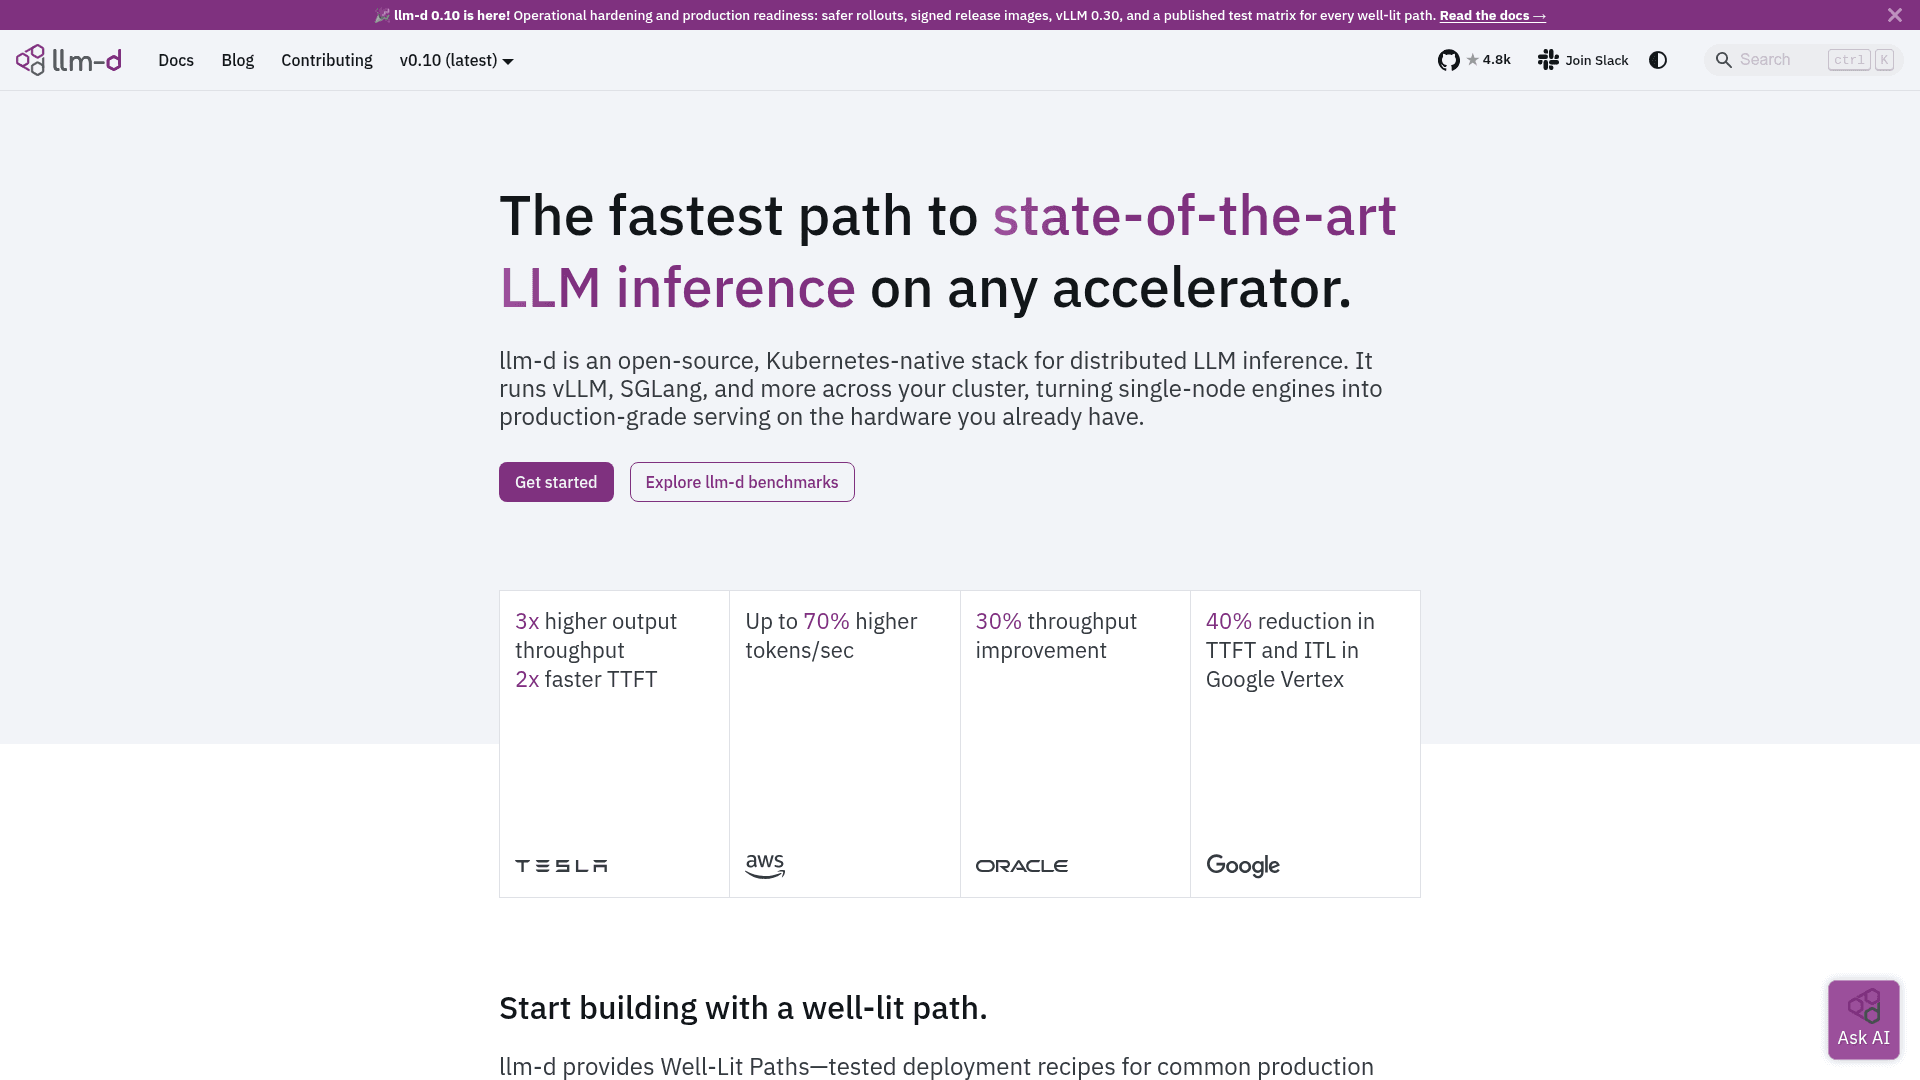
    The README attributes results to partner benchmarks and blogs, for example 3x higher output throughput and 2x faster TTFT with prefix-cache-aware routing versus round-robin in a Red Hat/Tesla test, and up to 70% higher tokens/sec with disaggregation in an AWS test. Reproducible benchmarks are published on the Prism site.
    llm-d - 1

    Community Discussions

    Be the first to start a conversation about llm-d

    Share your experience with llm-d, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    llm-d is an open-source, Kubernetes-native stack for distributed LLM inference, licensed under Apache License 2.0 and free to use, modify and distribute.

    • Apache License 2.0
    • Intelligent routing
    • Advanced KV-cache management
    • Prefill/decode disaggregation
    • Wide expert parallelism

    Capabilities

    Key Features

    • Intelligent prefix-cache and load-aware routing
    • Predicted-latency-based scheduling
    • Tiered KV-cache offloading to CPU or disk
    • Precise global KV-cache indexing
    • Prefill/decode disaggregation
    • Wide expert parallelism for MoE models
    • Flow control and multi-tenant fairness
    • SLO-aware workload autoscaling
    • OpenAI-compatible Batch APIs
    • Well-Lit Paths with Helm charts and Kustomize manifests
    • Monitoring and observability configuration
    • Engine- and hardware-agnostic serving

    Integrations

    Kubernetes
    vLLM
    SGLang
    Helm
    Kustomize
    NVIDIA GPUs
    AMD GPUs
    Google TPU
    Intel XPU
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate llm-d and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    llm-d Team

    llm-d enables high performance distributed inference in production on Kubernetes

    Founded 2025
    Read more about llm-d Team
    WebsiteLinkedInX / Twitter
    1 tool in directory

    Similar Tools

    KAI Scheduler icon

    KAI Scheduler

    Open source Kubernetes-native scheduler that optimizes GPU resource allocation for large-scale AI and machine learning workloads.

    Karpenter icon

    Karpenter

    Karpenter is an open-source Kubernetes node autoscaler that automatically provisions just-in-time compute resources to handle cluster workloads efficiently and cost-effectively.

    dstack icon

    dstack

    Open-source orchestration layer for running AI training and inference workloads across GPU clouds, Kubernetes, Slurm, VMs, and bare-metal clusters.

    Browse all tools

    Related Topics

    Container Orchestration

    AI-enhanced tools for automating deployment, scaling, and management of containerized applications across clusters with intelligent resource allocation.

    41 tools

    AI Infrastructure

    Infrastructure designed for deploying and running AI models.

    489 tools

    Compute Optimization

    Tools for optimizing computational resources and performance.

    65 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions