Lucebox
Open-source speculative inference server with custom CUDA and HIP kernels for running LLMs on consumer GPUs and heterogeneous machines.
At a Glance
About Lucebox
Lucebox is an Apache 2.0 licensed LLM inference engine from Luce-Org, written in C++ with CUDA and HIP kernels. It serves models through an OpenAI-compatible API and uses speculative prefill and decoding tuned for specific models and hardware targets, including consumer NVIDIA and AMD GPUs and APUs.
What It Is
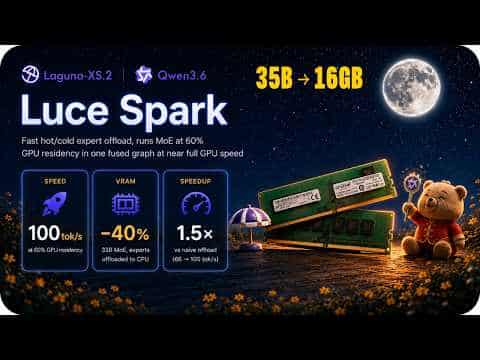
Lucebox is a local inference server for running large language models on consumer and mixed hardware. It pairs a target model with a drafter model for speculative decoding, and offers prompt-compression and KV-cache techniques that the project names PFlash, KVFlash, DFlash, DFlash2, DSpark, Luce Spark and Megakernel. The server can place work across CUDA, HIP, and mixed devices, such as a Radeon AI PRO R9700 combined with a Ryzen AI Max (Strix Halo) machine.
Models, Hardware and Reported Results
The README lists supported models including Qwen 3.5 and 3.8 variants, Laguna XS 2.1, Gemma 4, DeepSeek V4 and V4.1 Flash, and Ling 3.0 Flash. Tested hardware ranges from RTX 2080 Ti, 3090, 4090 and 5090 to R9700, RX 7900 XT/XTX, Strix Halo, DGX Spark and Jetson AGX Thor. The project reports measurements such as 208.1 tok/s average for Qwen 3.8 27B on one R9700 and a 6.1x prefill speedup for Laguna XS 2.1 at 256K context on an RTX 3090. It notes these runs use different prompts, quantizations and policies and are not a cross-hardware ranking. Image input is documented for Qwen 3.8 and DeepSeek V4 Flash Vision.
Setup and Client Harnesses
Prebuilt Docker images for CUDA 12 and ROCm are available on GHCR, or the server can be built with CMake for CUDA or HIP. Weights are downloaded from Hugging Face, and the server exposes OpenAI Chat Completions, Responses and Anthropic Messages APIs. Paged attention with continuous batching supports concurrent requests. A harness directory includes launchers for Claude Code, Codex, OpenCode, Hermes, OMP, Pi, OpenClaw and Open WebUI. PFlash is described as lossy prompt compression, to be disabled for exact-retrieval benchmarks.
Community Discussions
Be the first to start a conversation about Lucebox
Share your experience with Lucebox, ask questions, or help others learn from your insights.
Pricing
Open Source (Apache 2.0)
Self-hosted Lucebox speculative inference server released under the Apache License 2.0.
- Apache License 2.0 (OSI-approved)
- Self-hosted via Docker (CUDA 12 / ROCm) or build from source
- Custom kernels, speculative prefill and decoding
Capabilities
Key Features
- Speculative decoding and speculative prefill
- Custom CUDA and HIP kernels
- Heterogeneous multi-device execution
- Paged attention and continuous batching
- OpenAI Chat Completions, Responses and Anthropic Messages APIs
- Image input for supported vision models
- Prebuilt CUDA and ROCm Docker images
- Client harness launchers for coding agents
- Tensor parallel across NVLink GPUs
- Recommended profiles per model and hardware
Integrations
Demo Video