EveryDev.ai
Subscribe
Home
Tools

5,681+ AI tools

  • Featured
  • Gems
  • Trending
  • New
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2872
  • Coding2155
  • Infrastructure1015
  • Projects796
  • MCP743
  • Research708
  • Analytics549
  • Marketing519
  • Design463
  • Testing460
  • Data430
  • Security393
  • Integration281
  • Communication274
  • Prompts270
  • Extensions234
  • Voice198
  • DevOps187
  • Commerce180
  • Web127
  • Learning116
  • Finance41
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. NeuTTS
    NeuTTS icon

    NeuTTS

    Voice Synthesis

    Open-source on-device text-to-speech speech language models from Neuphonic with instant voice cloning.

    Visit Website

    At a Glance

    Pricing
    Free

    No-charge, royalty-free license for research and commercial use below the $5M annual revenue threshold. NeuTTS-Air is Apache 2.0; Nano and 2E models use the NeuTTS Open License 1.0.

    Engagement

    Available On

    Windows
    macOS
    Linux
    Android
    SDK

    Resources

    WebsiteGitHubllms.txt

    Topics

    Voice SynthesisAudioLocal Inference

    Alternatives

    loudkitSupertonicDia
    Developer
    NeuphonicKing's Cross, EnglandEst. 2021$3.97M+ raised

    Listed Nov 2026

    About NeuTTS

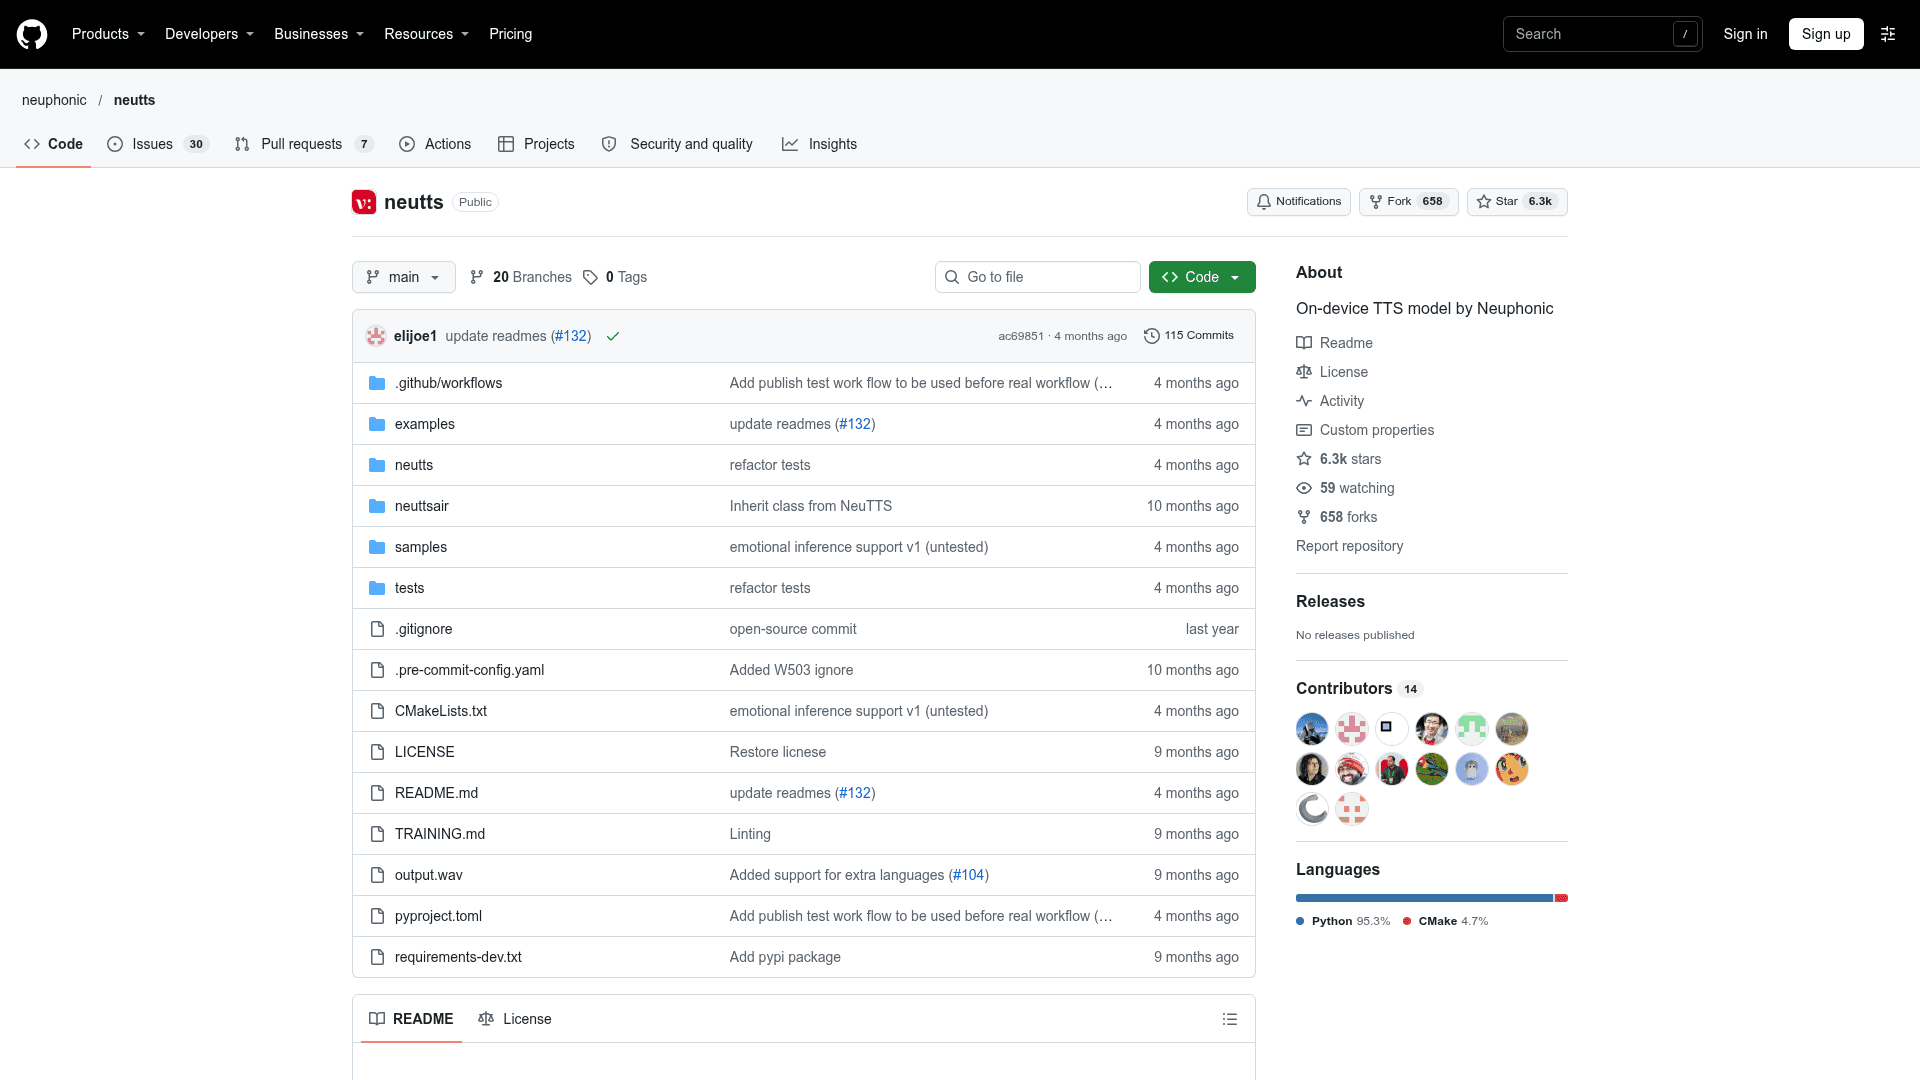
    NeuTTS is a collection of on-device text-to-speech speech language models from Neuphonic, distributed through a GitHub repository and a Python package. It synthesizes speech from text, optionally cloning a voice from a short reference audio clip, and runs locally using PyTorch or quantized GGUF backbones.

    What It Is

    NeuTTS combines small LLM backbones with the NeuCodec neural audio codec to generate speech locally rather than through a web API. The README lists model families including NeuTTS-Air (English), the NeuTTS-Nano multilingual collection (English, French, German, Spanish), and NeuTTS-2E, an English model with emotional control. Outputs are audio files written at 24 kHz, and every generated file carries a Perth watermark by default.

    Voice Cloning and Emotion Control

    Cloning requires a reference .wav sample and its transcript. The README recommends mono audio, 16-44 kHz, 3-15 seconds long, clean and continuous. NeuTTS-2E instead offers four fixed speakers (emily, paul, sophie, steven) and supports angry, disgusted, fearful, happy, neutral, sad and surprised emotions. Generation is sampled, and a seed can be set to reproduce identical audio.

    Running On-Device

    Install with pip, with optional extras for llama-cpp-python (GGUF models) and onnxruntime (ONNX codec decoder). Q4 and Q8 GGUF quantizations are provided, and streaming synthesis works with GGUF backbones. For lower latency, the README suggests GGUF backbones, pre-encoded references and the ONNX decoder. Example scripts cover basic synthesis, streaming, emotional TTS, and fine-tuning. The README publishes throughput benchmarks on CPU devices and an RTX 4090.

    Licensing Notes

    NeuTTS-Air is listed under Apache 2.0, while the Nano and 2E models use the NeuTTS Open License 1.0, which limits commercial use by entities at or above a stated revenue threshold. The README also warns that sites such as neutts.com are not affiliated with Neuphonic.
    NeuTTS - 1

    Community Discussions

    Be the first to start a conversation about NeuTTS

    Share your experience with NeuTTS, ask questions, or help others learn from your insights.

    Pricing

    FREE

    NeuTTS Open License (free tier)

    No-charge, royalty-free license for research and commercial use below the $5M annual revenue threshold. NeuTTS-Air is Apache 2.0; Nano and 2E models use the NeuTTS Open License 1.0.

    • No-charge, royalty-free license grant
    • Commercial use conditioned on annual revenue below $5,000,000 (the Threshold)
    • Qualified non-profits exempt from the Threshold for non-commercial or research use
    • NeuTTS-Air licensed under Apache 2.0
    • NeuTTS-Nano and NeuTTS-2E licensed under NeuTTS Open License 1.0 (source-available, not OSI-approved)

    Capabilities

    Key Features

    • On-device text-to-speech
    • Instant voice cloning from about 3 seconds of audio
    • GGUF Q4 and Q8 quantizations
    • Streaming synthesis with GGUF backbones
    • Multilingual models (English, French, German, Spanish)
    • Emotional control with NeuTTS-2E
    • NeuCodec audio codec with ONNX decoder options
    • Perth watermarking of generated audio
    • Fine-tuning script
    • Seed-based reproducible generation

    Integrations

    Hugging Face
    llama.cpp
    llama-cpp-python
    ONNX Runtime
    PyTorch
    vLLM
    Perth watermarker

    Ratings & Reviews

    No ratings yet

    Be the first to rate NeuTTS and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    Neuphonic

    Founded 2021
    King's Cross, United Kingdom
    $3.97M+ raised
    9 employees

    Used by

    PolyAI
    TheStageAI
    Brilliant Labs
    Rasa
    +2 more
    Read more about Neuphonic
    WebsiteGitHub
    1 tool in directory

    Similar Tools

    loudkit icon

    loudkit

    Open-source, on-device text-to-speech engine with 28 voices across 10 languages, voice cloning from 10 seconds of audio, and SDKs for Python, Swift, Go, Rust, and TypeScript.

    Supertonic icon

    Supertonic

    Lightning-fast, on-device text-to-speech system powered by ONNX Runtime that runs entirely locally with no cloud dependency, supporting 31 languages across Python, JavaScript, mobile, and native runtimes.

    Dia icon

    Dia

    Dia is an open-source text-to-speech model by Nari Labs that generates realistic dialogue audio with multiple speakers, emotions, and non-verbal sounds from transcripts.

    Browse all tools

    Related Topics

    Voice Synthesis

    AI tools that generate human-like speech from text.

    54 tools

    Audio

    AI tools that generate or edit audio — music, sound effects, voice and speech, and podcast production.

    60 tools

    Local Inference

    Tools and platforms for running AI inference locally without cloud dependence.

    350 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions