
PaddleX
Low-code development tool built on PaddlePaddle that bundles pretrained model pipelines for OCR, vision, time series, speech and video, covering training through deployment.
At a Glance
PaddleX core is released under the Apache License 2.0, free to use, modify and distribute.
Engagement
Available On
Alternatives
Listed Nov 2026
About PaddleX
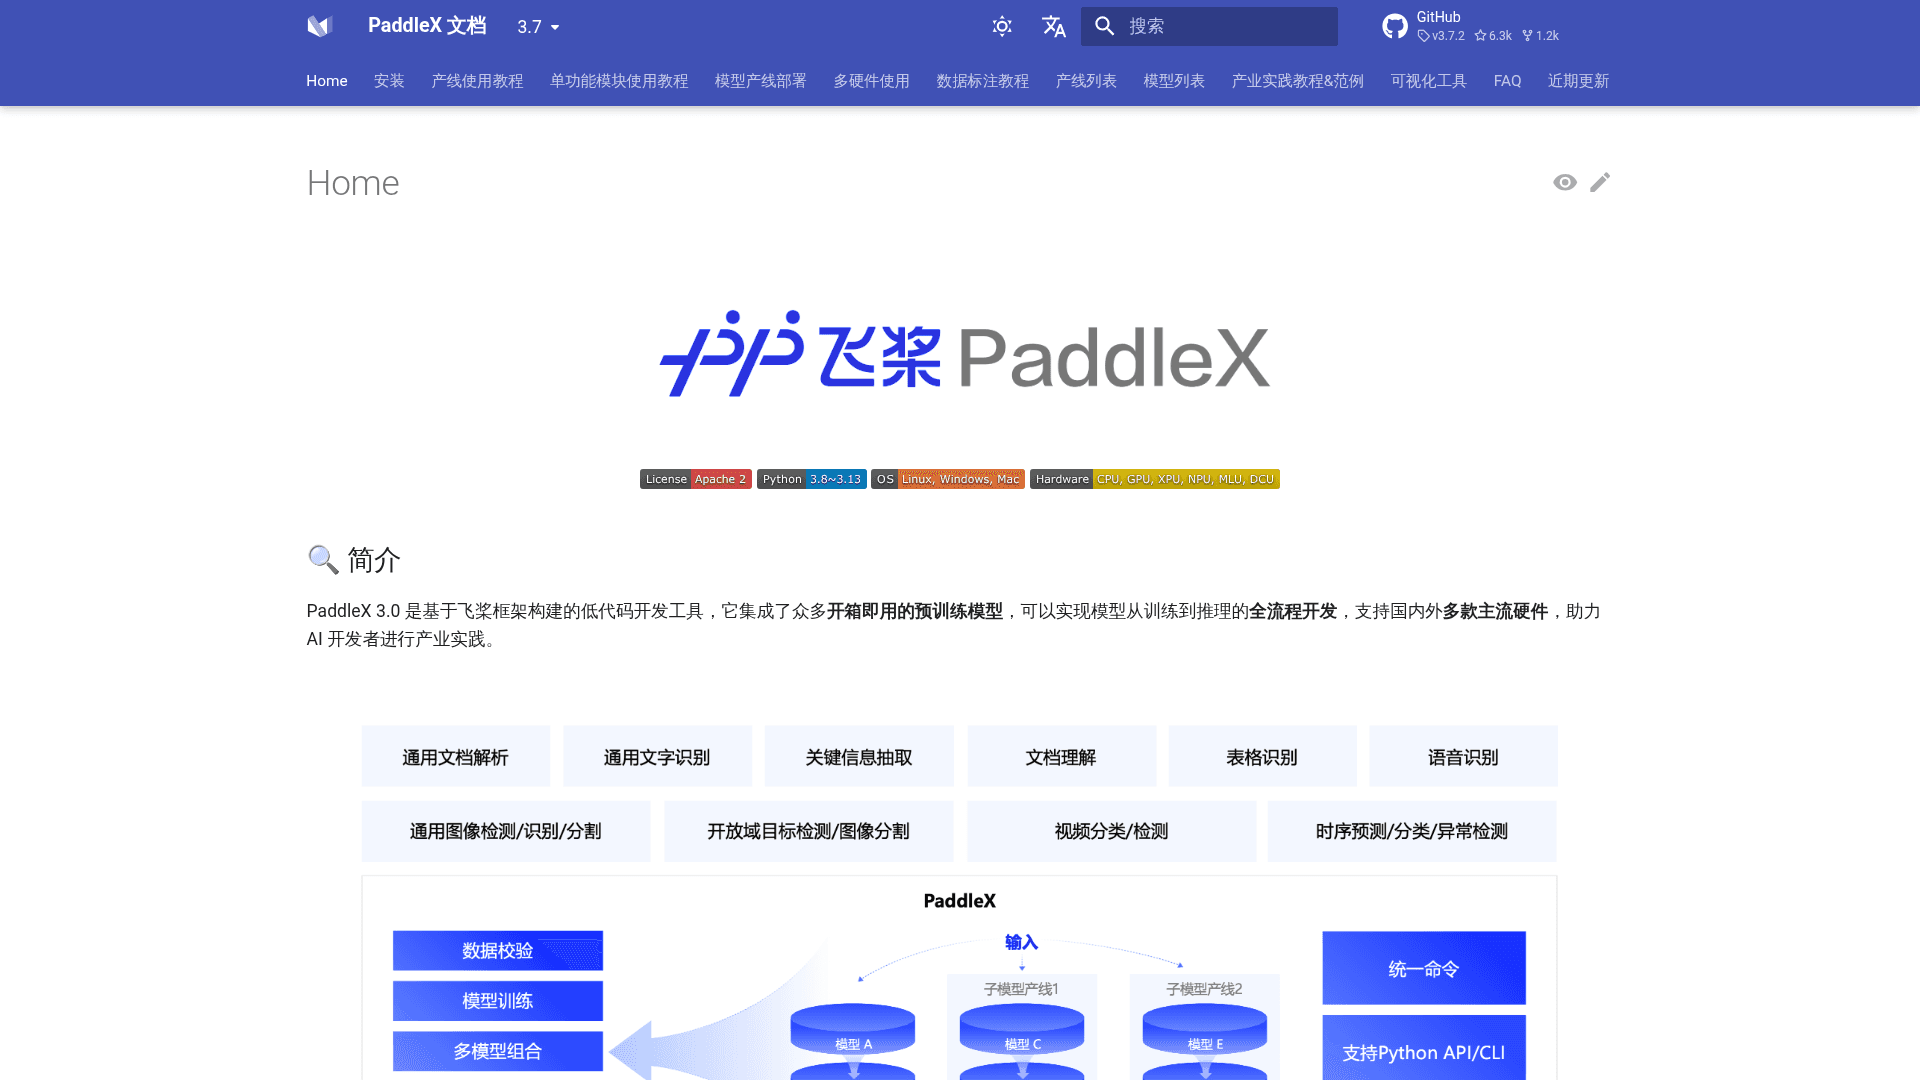
PaddleX 3.0 is a low-code development tool built on the PaddlePaddle framework and published by the PaddlePaddle organization. It integrates pretrained models and supports end-to-end development from training to inference across several mainstream hardware platforms. The project is open source under the Apache 2.0 license, and its documentation lists v3.7.2 as the current release.
What It Is
PaddleX packages models into task-oriented pipelines, meaning predefined workflows that combine one or more single-function modules. According to the README, it covers 200+ PaddlePaddle models organized into 33 pipelines and 39 single-function modules. Areas include text-image analysis, OCR, object detection, time-series forecasting, speech recognition, video analysis and document-oriented vision-language models.
Workflow and Usage
Users install PaddlePaddle and then paddlex[base] with pip, which requires Python 3.8 to 3.13. A pipeline can be run from the command line with paddlex --pipeline <name> --input <file> --device <device>. In Python, create_pipeline() and predict() return results that can be printed or saved as images, JSON, and, for table pipelines, XLSX or HTML. Pipelines can be fine-tuned with the secondary development capability when pretrained results are not sufficient.
Deployment and Hardware
The docs describe high-performance inference, serving deployment, on-device deployment, and ONNX model export. Supported devices include CPU, GPU, Kunlunxin XPU, Ascend NPU, Cambricon MLU and Hygon DCU, selected through the device parameter.
Recent Updates
The README lists v3.3.0 (October 2025) adding inference and deployment support for PaddleOCR-VL and PP-OCRv5 multilingual models. v3.2.0 added CUDA 12 support for high-performance inference and open-sourced the serving solution. v3.1.0 added the PP-DocTranslation pipeline, which uses PP-StructureV3 and ERNIE 4.5 Turbo.
Community Discussions
Be the first to start a conversation about PaddleX
Share your experience with PaddleX, ask questions, or help others learn from your insights.
Pricing
Open Source (Apache 2.0)
PaddleX core is released under the Apache License 2.0, free to use, modify and distribute.
- Apache License 2.0
- 200+ PaddlePaddle models integrated into 33 pipelines
- High-performance inference, serving and edge deployment
- Supports CPU, GPU, XPU, NPU, MLU, DCU hardware
Capabilities
Key Features
- Model pipelines for OCR, table recognition, layout parsing and formula recognition
- Computer vision pipelines for classification, detection and segmentation
- Time-series forecasting, anomaly detection and classification
- Multilingual speech recognition
- Video classification and detection
- Unified CLI and Python API
- High-performance inference, serving and on-device deployment
- ONNX model export
- Secondary development and fine-tuning of pipelines
- Multi-hardware support (CPU, GPU, XPU, NPU, MLU, DCU)