
Phonon on WebGPU
A WebGPU runtime for Gradium's Phonon text-to-speech models that streams speech in the browser with per-word timings.
At a Glance
The WebGPU runtime code is licensed under Apache License 2.0. The default Phonon 31M English model is also Apache-2.0; the Phonon 40M models are CC BY-NC 4.0 (no commercial use).
Engagement
Available On
Alternatives
Listed Nov 2026
About Phonon on WebGPU
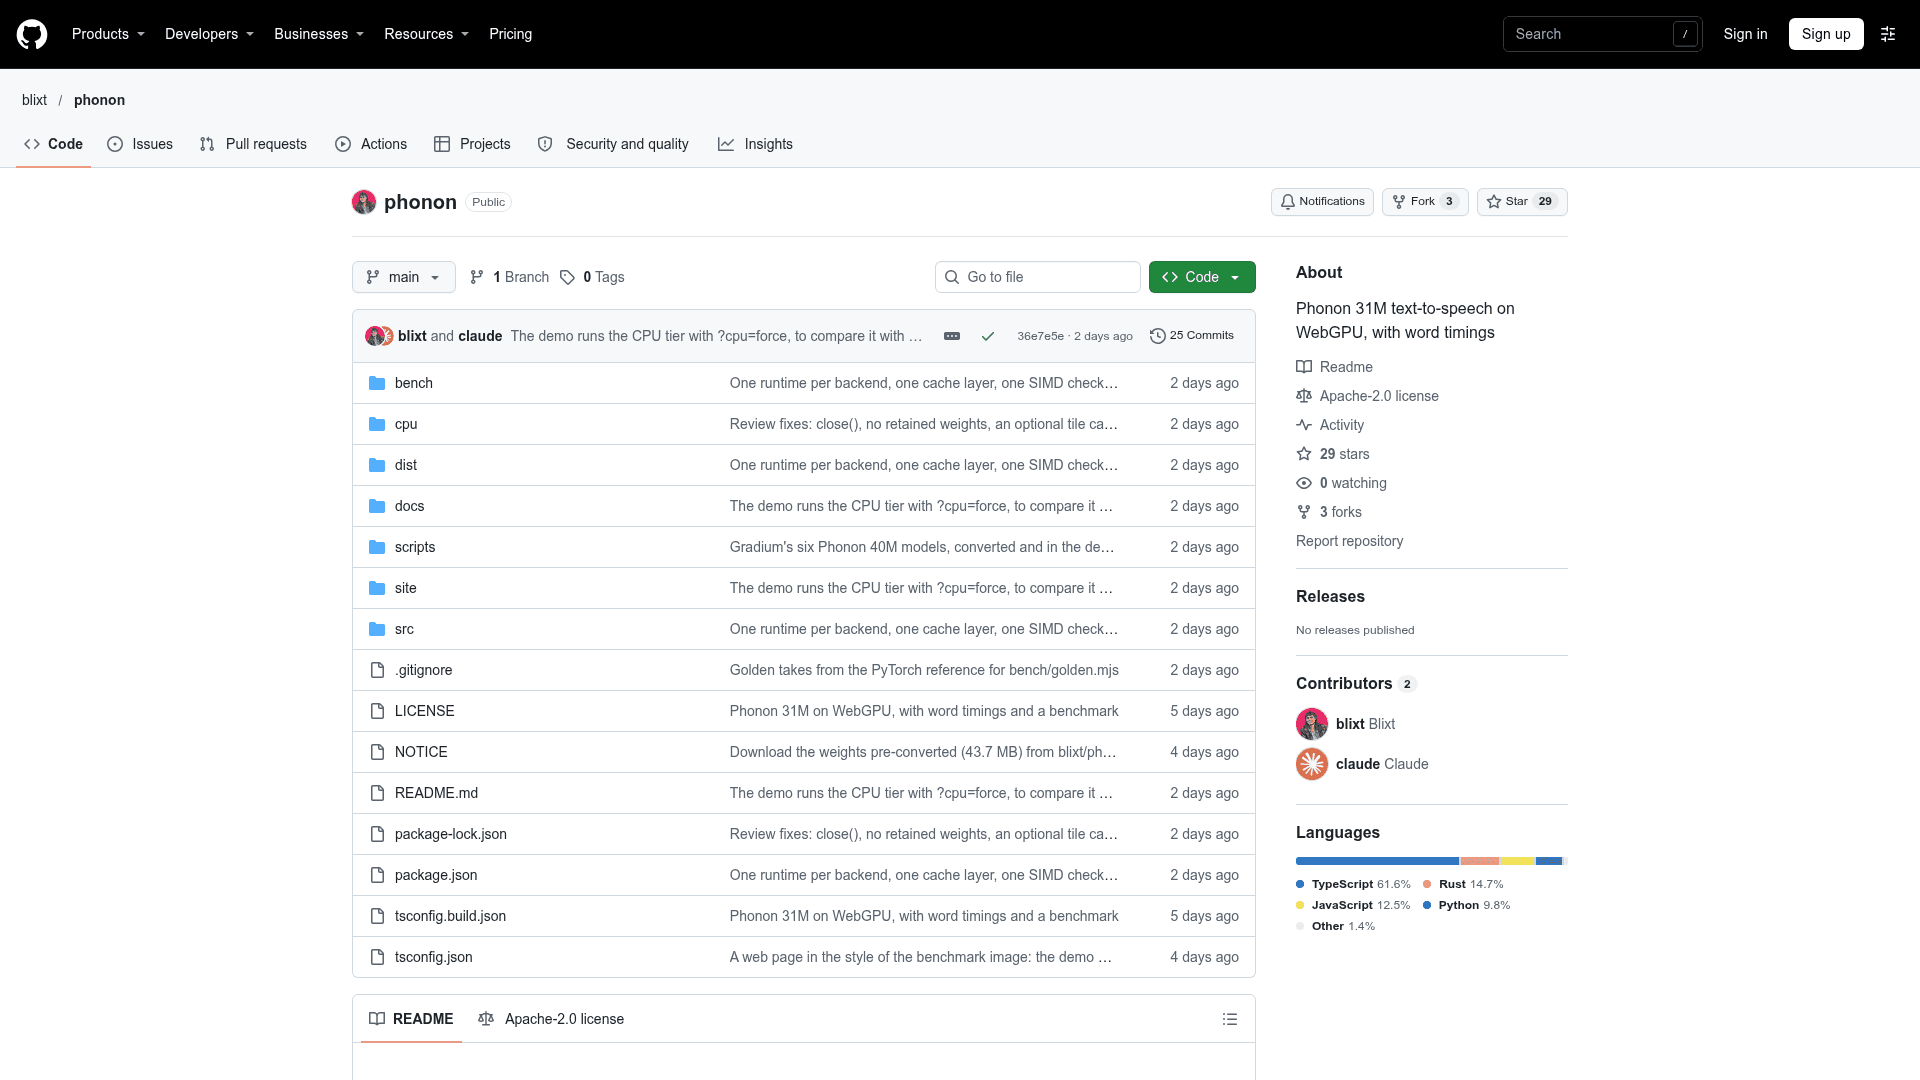
blixt/phonon is an open-source runtime, published by the GitHub user blixt, that runs Gradium's Phonon text-to-speech models in the browser on WebGPU. It streams 24 kHz speech and reports a start and end time for every word and token as it speaks. A WebAssembly CPU fallback is used where WebGPU is unavailable.
What It Is
Phonon on WebGPU is a JavaScript/TypeScript library, installed as the phonon-webgpu package, for in-browser speech synthesis. It runs Phonon 31M, an Apache-2.0 English model by Gradium, and also Gradium's Phonon 40M models in English, French, German, Spanish and Portuguese, which are licensed CC BY-NC 4.0 and not for commercial use. Gradium did not make this runtime; the README credits the models, tokenizers and voices to Gradium.
A page calls Phonon.load, then speak with a text and a voice. The call returns audio samples as a Float32Array, plus the words and tokens with their times in seconds. Callbacks deliver audio chunks and words as soon as they are available. Speed can be set from about 0.77× to 1.3×.
How It Runs in the Browser
The engine is new code: WGSL compute shaders, TypeScript and Rust compiled to WebAssembly, with no phonon-tts or ONNX Runtime inside. Weights are converted to 8-bit integers (a 43.7 MB file) and cached in the browser after the first download. The README documents operation in Chrome on macOS and Windows and Safari on iOS, with one user report on Firefox on Android; other browsers are untested.
Without WebGPU, the same model graph runs on the CPU in a worker using WebAssembly SIMD. Threads are used only on cross-origin isolated pages, and the demo registers a service worker to enable that.
Word Timings
Word times are derived from one attention head of the model, corrected for the model's lead and for silence in the audio. The README compares them against wav2vec2 and MMS forced alignment and states they are not a forced alignment. Timings can be used to lay out words before speaking and highlight them token by token during playback.
Benchmarks and Limits
The README reports benchmark comparisons against Gradium's phonon-tts package and Kokoro 82M on a MacBook Pro M3 Max, an RTX 2080 Ti PC and an iPhone 17 Pro; these are the author's own measurements. Documented limits: it does not normalize numbers and symbols into words, so numbers read best written as words, and the 40M models are non-commercial.
Community Discussions
Be the first to start a conversation about Phonon on WebGPU
Share your experience with Phonon on WebGPU, ask questions, or help others learn from your insights.
Pricing
Open Source (Apache-2.0)
The WebGPU runtime code is licensed under Apache License 2.0. The default Phonon 31M English model is also Apache-2.0; the Phonon 40M models are CC BY-NC 4.0 (no commercial use).
- Code in the repository under Apache License 2.0
- Phonon 31M (English) model under Apache-2.0
- Phonon 40M models are CC BY-NC 4.0: no commercial use
- Per-word and per-token start and end times
- Streaming 24 kHz English speech
Capabilities
Key Features
- Streaming 24 kHz text-to-speech in the browser on WebGPU
- Start and end time for every word and token
- Speaking speed control from about 0.77× to 1.3×
- WebAssembly CPU fallback with optional multithreading
- 8-bit quantized weights cached in the browser
- Support for Gradium's English voices
- Phonon 40M models in English, French, German, Spanish and Portuguese
- Automatic splitting of long texts at sentence and word ends
- Benchmark and parity test scripts