
Reka Gateway
Reka Platform is an OpenAI-compatible API gateway for hosted Reka and open multimodal and text models running on Reka-operated infrastructure.
At a Glance
Engagement
Available On
Alternatives
Listed Nov 2026
About Reka Gateway
Reka Platform is the developer platform from Reka for calling Reka models and a curated selection of open models through a single API. Developers create an account, generate an API key, choose a model and send requests to one endpoint. Reka states that it builds the models and operates the inference infrastructure behind the gateway.
What It Is
Reka Platform, also referred to as Reka Gateway, is a hosted inference service. It exposes a chat completions endpoint at api.reka.ai/v1 that works with existing OpenAI client libraries by changing the base URL and API key. The model is chosen per request from a catalog that includes DeepSeek, GLM, Qwen and Reka models such as reka-flash-3 and reka-edge-2603.
How It Works
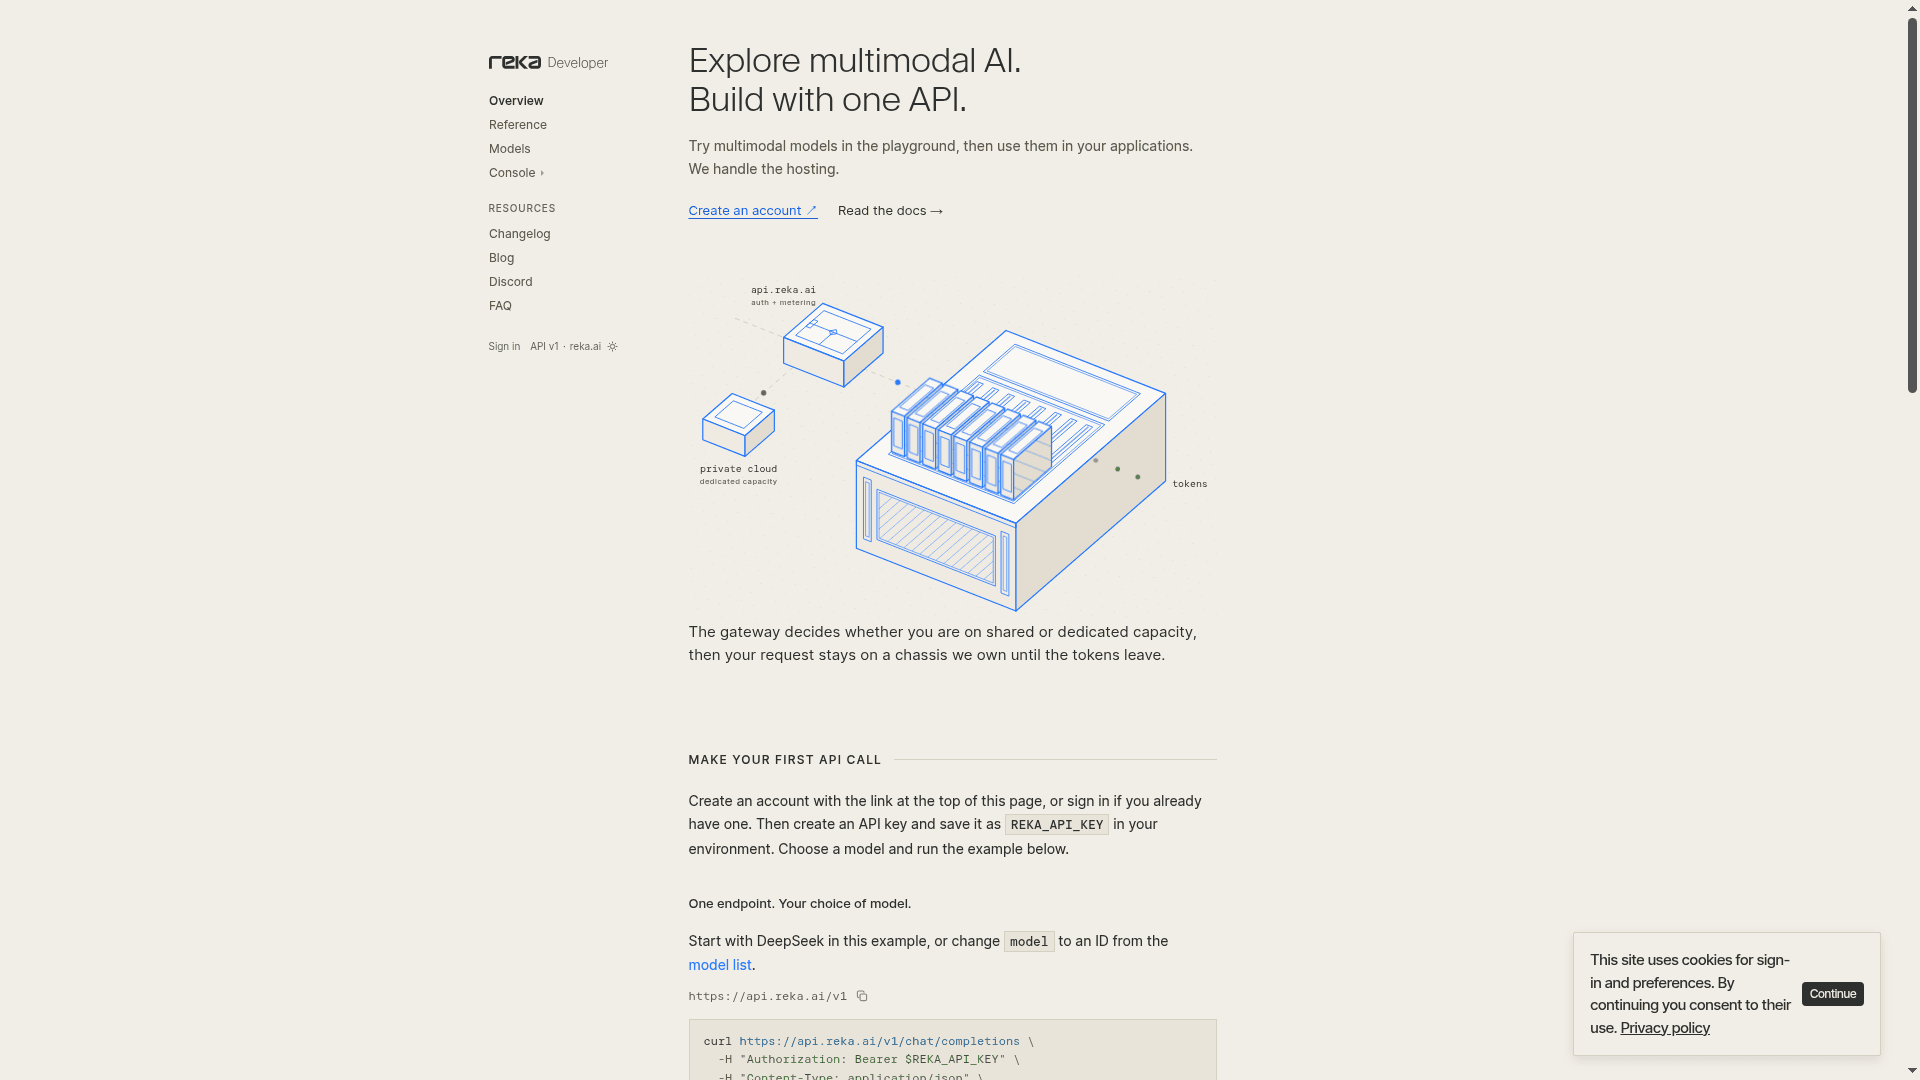
The gateway authenticates each request and tracks usage. The homepage says it decides whether a request runs on shared or dedicated capacity, and that the request stays on infrastructure Reka owns. A playground lets users try multimodal models before integrating them, and the docs cover streaming, supported parameters and error codes. Users can add credit and monitor spending on a usage page.
Models and Dedicated Capacity
The text model list shows context windows from 16k to 1M tokens, with cached-input rates where prompt caching is supported. Reka also offers dedicated inference capacity for teams with specific models, workloads or deployment needs, arranged by contacting the team. The models are also listed on OpenRouter, and a public status page is provided.
Current access and pricing
The former platform.reka.ai address redirects to developer.reka.ai, branded Reka Gateway. Serverless inference uses separate per-million input, output, and cache-read rates with no platform fee or minimum. Reasoning traces count as output tokens. The beta batch API offers 50% rates for the documented supported models with a 24-hour completion window. Reka Pass costs $10/month and grants $30 of inference credit monthly. On-demand deployments are billed by GPU time; training and fine-tuning are also documented.
Community Discussions
Be the first to start a conversation about Reka Gateway
Share your experience with Reka Gateway, ask questions, or help others learn from your insights.
Pricing
deepseek4-flash — per 1M input tokens
Input: $0.11/million tokens. Output: $0.66/million tokens. Cache read: $0.007/million tokens. Reasoning tokens are billed as output. This is not a flat per-request fee.
- Serverless inference
glm5.3 — per 1M input tokens
Input: $1.17/million tokens. Output: $3.96/million tokens. Cache read: $0.234/million tokens. Reasoning tokens are billed as output. This is not a flat per-request fee.
- Serverless inference
glm5.3-flash — per 1M input tokens
Input: $0.15/million tokens. Output: $0.5/million tokens. Cache read: $0.015/million tokens. Reasoning tokens are billed as output. This is not a flat per-request fee.
- Serverless inference
qwen3.8-27b — per 1M input tokens
Input: $0.2/million tokens. Output: $2.5/million tokens. Cache read: $0.05/million tokens. Reasoning tokens are billed as output. This is not a flat per-request fee.
- Serverless inference
reka-edge-2603 — per 1M input tokens
Input: $0.1/million tokens. Output: $0.1/million tokens. No cache-read rate listed. Reasoning tokens are billed as output. This is not a flat per-request fee.
- Serverless inference
reka-flash-3 — per 1M input tokens
Input: $0.1/million tokens. Output: $0.2/million tokens. No cache-read rate listed. Reasoning tokens are billed as output. This is not a flat per-request fee.
- Serverless inference
deepseek41-flash — per 1M input tokens
Input: $0.3/million tokens. Output: $1.2/million tokens. Cache read: $0.006/million tokens. Reasoning tokens are billed as output. This is not a flat per-request fee.
- Serverless inference
deepseek41-flash-20261017 — per 1M input tokens
Input: $0.15/million tokens. Output: $0.6/million tokens. Cache read: $0.003/million tokens. Reasoning tokens are billed as output. This is not a flat per-request fee.
- Serverless inference
qwen3.6-27b — per 1M input tokens
Input: $0.29/million tokens. Output: $1.95/million tokens. Cache read: $0.029/million tokens. Reasoning tokens are billed as output. This is not a flat per-request fee.
- Serverless inference
Reka Pass
$10/month subscription grants $30 of inference credit each month across supported models. Additional top-up is available; unused-credit rollover terms are not established here.
- $30 inference credit per month
- Supported open and Reka models
- OpenAI-compatible API
On-demand deployments
Dedicated capacity is billed by GPU time. Contact Reka for workload-specific arrangements; no universal hourly amount is represented.
- Dedicated inference capacity
Capabilities
Key Features
- Single OpenAI-compatible chat completions endpoint
- Per-request model selection
- Curated open models plus Reka models
- Multimodal model playground
- Streaming support
- Prompt caching for supported models
- Usage tracking and credit management
- Dedicated inference capacity option
- API key authentication