EveryDev.ai
Subscribe
Home
Tools

5,118+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2616
  • Coding1923
  • Infrastructure904
  • Projects719
  • Research646
  • MCP613
  • Analytics497
  • Marketing497
  • Design422
  • Testing411
  • Data378
  • Security329
  • Integration259
  • Communication250
  • Prompts247
  • Extensions219
  • Commerce171
  • Voice171
  • DevOps168
  • Web123
  • Learning114
  • Finance35
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. RunInfra
    RunInfra icon

    RunInfra

    LLM Orchestration
    Featured

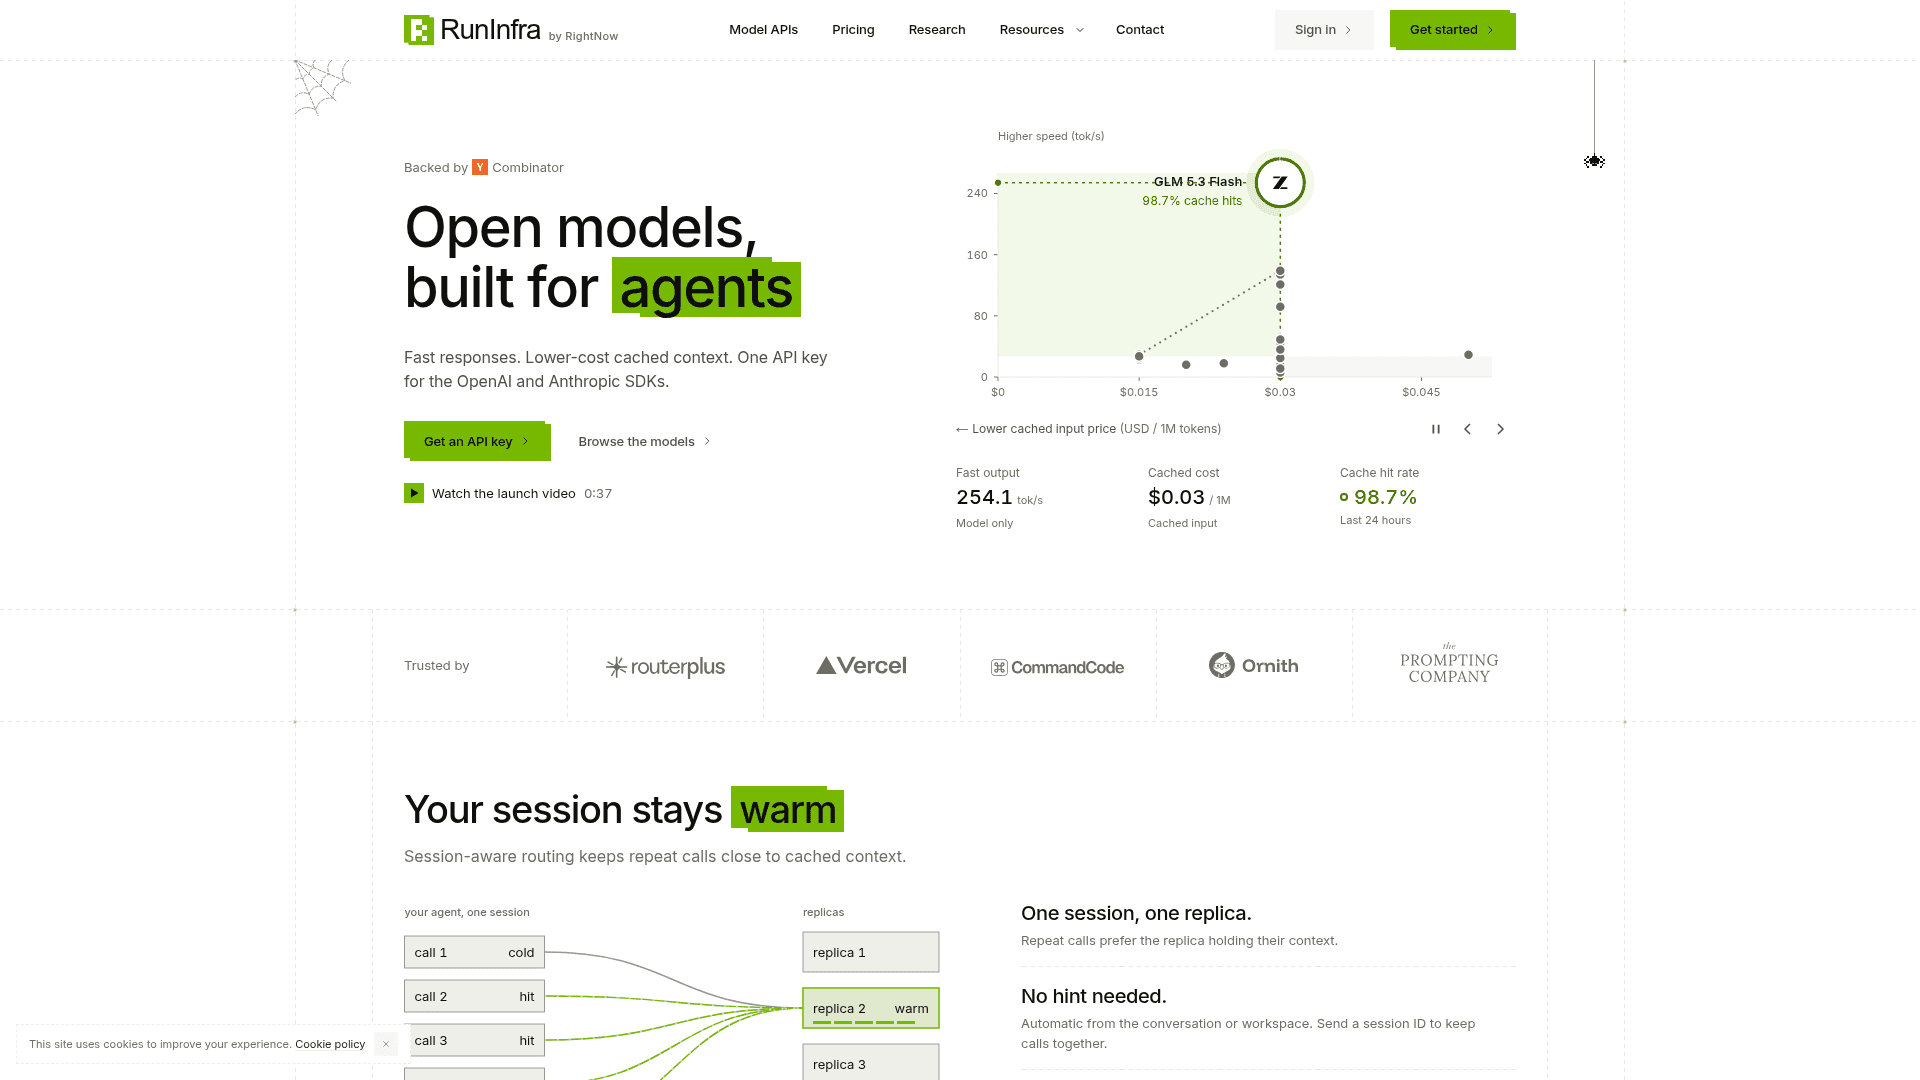
    Hosted open-model inference API for AI agents with session-aware cache routing, compatible with the OpenAI and Anthropic SDKs.

    Visit Website

    At a Glance

    Pricing
    Paid
    Pay as you go: $0.26 usage-based
    Starter: $10/mo
    Pro: $29/mo
    +2 more plans

    Engagement

    Available On

    API
    CLI
    Web

    Resources

    WebsiteDocsllms.txt

    Topics

    LLM OrchestrationAI InfrastructureCompute Optimization

    Alternatives

    AI21 LabsZeroGPUEdgee
    Developer
    RightNow AIAmman, JordanEst. 2019

    Listed Oct 2026

    About RunInfra

    RunInfra, made by RightNow AI, Inc., is a hosted Model API service that serves open models to AI agents and coding tools through a single API key. Chat completions and Responses endpoints are OpenAI-compatible, and a Messages endpoint is Anthropic-compatible. The homepage lists models such as Ornith, DeepSeek, GLM, Qwen and Nemotron variants.

    What It Is

    RunInfra is an inference gateway for open models. Developers set the base URL to the RunInfra API, use a workspace API key, and pass a model id, so existing OpenAI or Anthropic SDK code can call hosted models. The model library shows per-model input, cached input and output prices, output speed, and capabilities such as tool calling, JSON mode, streaming and image input.

    How Cache-Aware Routing Works

    RunInfra describes session-aware routing that sends repeat calls from one agent session to the replica already holding its cached context. Routing is automatic from the conversation or workspace, or callers can send a session ID to keep calls together. Cache hits are reported in usage and billed at the cached rate, and the site notes hits are best effort. The site publishes a cache measurement method and shows effective input rates based on measured cache share over the last 24 hours.

    Coding Agent Setup

    A CLI and a copy-paste setup prompt let coding agents such as Claude Code, Codex, OpenCode, Cline, Droid and Grok Build configure RunInfra models. The agent reads the setup docs, the user approves sign-in in the browser, and the user confirms a setup plan before anything is installed or changed. Docs also cover OpenAI compatibility with LangChain, LiteLLM, LlamaIndex and the AI SDK, rate limits and troubleshooting.

    Data Handling and Security

    RunInfra states that hosted Model APIs never store prompts, with zero data retention by default and no training on prompts or completions. It lists TLS in transit, AES-256 at rest, workspace roles with row-level security, and a SOC 2 Type II attestation with the report available under NDA. The site also references an enterprise serving package license for deploying optimized serving packages in a licensee's own products.
    RunInfra - 1

    Community Discussions

    Be the first to start a conversation about RunInfra

    Share your experience with RunInfra, ask questions, or help others learn from your insights.

    Pricing

    Pay as you go

    Hosted Model APIs billed per token from a prepaid balance; no subscription. $5 minimum top-up; credits last a year.

    $0.26
    usage based
    • $5 minimum top-up
    • OpenAI-compatible chat completions and Anthropic-compatible Messages
    • Cached input discounts on supported models
    • Ornith 1.5 122B: input $0.26, cached input $0.07, output $2.08 per 1M tokens
    • DeepSeek V4.1 Flash 1017: input $0.15, cached input $0.01, output $0.60 per 1M tokens
    • GLM 5.3: input $1.30, cached input $0.13, output $4.20 per 1M tokens
    • GLM 5.3 Flash: input $0.11, cached input $0.03, output $0.45 per 1M tokens
    • Nemotron 3.5 Lightning 30B: input $0.05, cached input $0.01, output $0.15 per 1M tokens
    • Get $1 free to test the Model APIs

    Starter

    Coding plan with about $12 of usage a month

    $10
    per month
    • About $12 of usage a month
    • 5-hour limit $1.11
    • Weekly limit $2.77
    • Free Standby up to $0.20 of chat a day
    • Requests at once per model, when busy 4 to 96

    Pro

    Coding plan with about $35 of usage a month

    $29
    per month
    • About $35 of usage a month
    • 5-hour limit $3.23
    • Weekly limit $8.08
    • Free Standby up to $0.58 of chat a day
    • Requests at once per model, when busy 5 to 96

    Team

    Coding plan with about $119 of usage a month

    $99
    per month
    • About $119 of usage a month
    • 5-hour limit $10.98
    • Weekly limit $27.46
    • Free Standby up to $1.98 of chat a day
    • Requests at once per model, when busy 8 to 96

    Enterprise

    Dedicated infrastructure, compliance, and custom volume.

    Custom
    contact sales
    • Audit logs and role-based access control (RBAC)
    • Custom volume and contract terms
    • Custom SLAs up to 99.99%
    • SOC 2 Type II attestation
    • Dedicated CSM and private Slack
    View official pricing

    Capabilities

    Key Features

    • OpenAI-compatible chat completions and Responses endpoints
    • Anthropic-compatible Messages endpoint
    • Session-aware routing to warm cached replicas
    • Cached input billing with reported cache hits
    • Hosted open model library with tool calling, JSON mode, streaming and image input
    • CLI and prompt-based setup for coding agents
    • Zero data retention by default for hosted Model APIs
    • Workspace API keys and roles
    • Published cache measurement methodology

    Integrations

    OpenAI SDK
    Anthropic SDK
    Claude Code
    Codex
    OpenCode
    Cline
    Droid
    Grok Build
    LangChain
    LiteLLM
    LlamaIndex
    AI SDK
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate RunInfra and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    RightNow AI

    RightNow AI builds an AI-powered code editor specifically designed for NVIDIA GPU kernel development and optimization. The company is part of the NVIDIA Inception Program and focuses on helping hardware AI developers at leading companies optimize their CUDA, Triton, and PyTorch kernels. RightNow AI provides tools for profiling, benchmarking, and GPU emulation that enable developers to test on 86+ GPU architectures without owning the hardware.

    Founded 2019
    Amman, Jordan
    10 employees

    Used by

    NVIDIA (Supported Platform)
    Hugging Face (Partner)
    Runway (Partner)
    Together (Partner)
    Read more about RightNow AI
    WebsiteGitHubLinkedInX / Twitter
    3 tools in directory

    Similar Tools

    AI21 Labs icon

    AI21 Labs

    AI21 Labs provides an intelligent gateway, harness optimization and post-training to reduce enterprise AI agent token cost while keeping frontier-level quality.

    ZeroGPU icon

    ZeroGPU

    ZeroGPU is a compute-efficient AI inference layer that routes high-volume tasks to specialized small language models across an edge-powered network, reducing costs and latency versus frontier models.

    Edgee icon

    Edgee

    AI Gateway that compresses prompts before they reach LLM providers, reducing token usage by up to 50% while preserving semantic meaning.

    Browse all tools

    Related Topics

    LLM Orchestration

    Platforms and frameworks for designing, managing, and deploying complex LLM workflows with visual interfaces, allowing for the coordination of multiple AI models and services.

    287 tools

    AI Infrastructure

    Infrastructure designed for deploying and running AI models.

    520 tools

    Compute Optimization

    Tools for optimizing computational resources and performance.

    75 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions