EveryDev.ai
Subscribe
Home
Tools

4,691+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents3426
  • Coding2391
  • Infrastructure1055
  • Projects732
  • Marketing662
  • Research612
  • MCP593
  • Analytics538
  • Design533
  • Testing420
  • Security410
  • Data358
  • Prompts260
  • Integration256
  • Communication250
  • Extensions222
  • Voice201
  • Learning193
  • Commerce173
  • DevOps161
  • Web122
  • Finance36
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai © 2026
    1. Home
    2. Tools
    3. smevals
    smevals icon

    smevals

    LLM Evaluations

    A command-line framework for running and grading evals against small and large language models.

    Visit Website

    At a Glance

    Pricing
    Open Source

    smevals CLI framework for running evals against models, released under the MIT License.

    Engagement

    Available On

    API
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    LLM EvaluationsCommand Line AssistantsAutomated Testing

    Alternatives

    Inspect AIOpikOpenCompass
    Developer
    Prime Radiant, Inc.

    Listed Oct 2026

    About smevals

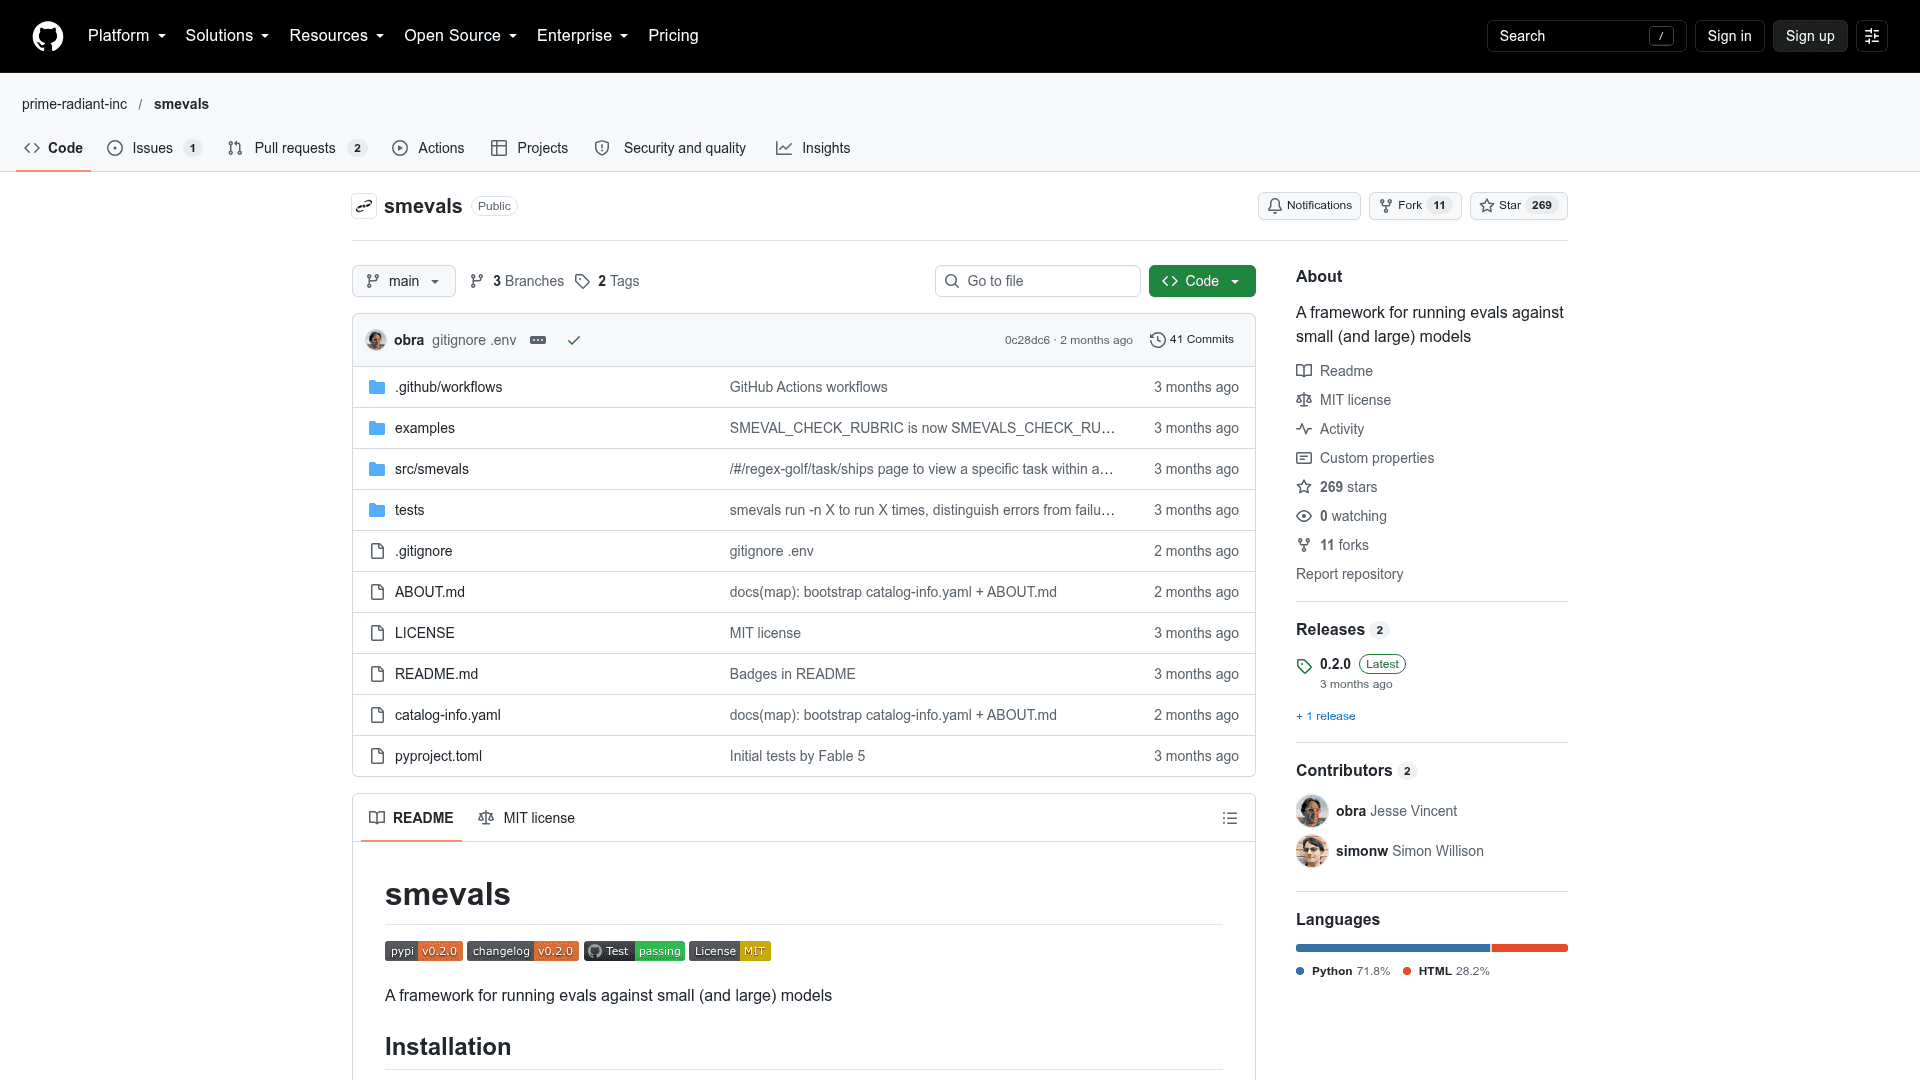
    smevals is an open-source Python framework from Prime Radiant, Inc. for running evals against small and large models. It organizes work into Evals, Tasks, Configs, Runs, Graders and Checks, and is installed as a CLI tool. The latest listed release is 0.2.0.

    What It Is

    smevals is a command-line evaluation harness. An Eval is a directory containing an eval.yaml file, with YAML files for Tasks, Configs and Graders. Runner executables send prompts to a model directly or drive an agent harness such as Codex or Pi. Checker programs can also be custom executables.

    How the Workflow Operates

    A Run records one Task executed against one Config through a Runner. The Runner receives its inputs as environment variables such as SMEVALS_MODEL and SMEVALS_PROMPT. Its standard output is saved as output.txt, and a non-zero exit marks the Run as failed. Failed Runs are never graded and do not count toward the -n sample target.

    Graders apply an ordered sequence of Checks to each Run. Built-in checkers include contains and xml-valid, and custom checkers can emit scores, metrics, tags and notes. Checks can be marked required, and files created by one Check are available to later Checks. Each Grade stores a snapshot of its Grader. Runs can be regraded without being re-executed, and multiple Graders can coexist.

    Reporting and Viewing Results

    smevals report prints a markdown leaderboard of config and model combinations with mean and standard error scores. It also shows tag shares and per-task breakdowns. smevals serve provides a live web UI, and smevals build generates a static site that can aggregate Evals from multiple repositories.
    smevals - 1

    Community Discussions

    Be the first to start a conversation about smevals

    Share your experience with smevals, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    smevals CLI framework for running evals against models, released under the MIT License.

    • MIT License
    • Install via uv tool install smevals, pip install smevals, or uvx smevals
    • Framework for running evals against small and large models

    Capabilities

    Key Features

    • Eval, Task, Config, Run, Grader and Check model
    • Runner contract using environment variables
    • Built-in contains and xml-valid checkers
    • Custom checker executables
    • Repeated runs with -n sample targets
    • Regrading without re-running
    • Markdown leaderboard reports with mean ± stderr
    • Live web UI via serve
    • Static site build
    • Multiple graders per eval

    Integrations

    llm CLI
    Codex
    Pi
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate smevals and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    Prime Radiant, Inc.

    Read more about Prime Radiant, Inc.
    GitHub
    1 tool in directory

    Similar Tools

    Inspect AI icon

    Inspect AI

    An open-source Python framework for large language model evaluations developed by the UK AI Security Institute, supporting agentic tasks, tool use, multi-turn dialog, and 200+ pre-built benchmarks.

    Opik icon

    Opik

    Open-source platform for evaluating, testing, and monitoring LLM applications with tracing and observability features.

    OpenCompass icon

    OpenCompass

    Open-source platform for evaluating large language and multimodal models across 100+ datasets.

    Browse all tools

    Related Topics

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    172 tools

    Command Line Assistants

    AI-powered command-line assistants that help developers navigate, search, and execute terminal commands with intelligent suggestions and context awareness.

    294 tools

    Automated Testing

    AI-powered platforms that automate end-to-end testing processes with intelligent test case generation, execution, and reporting for faster, more reliable software delivery.

    171 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions