
TRAIL Benchmark
A benchmark dataset and evaluation scripts for testing how well LLMs locate errors in annotated AI agent execution traces.
At a Glance
About TRAIL Benchmark
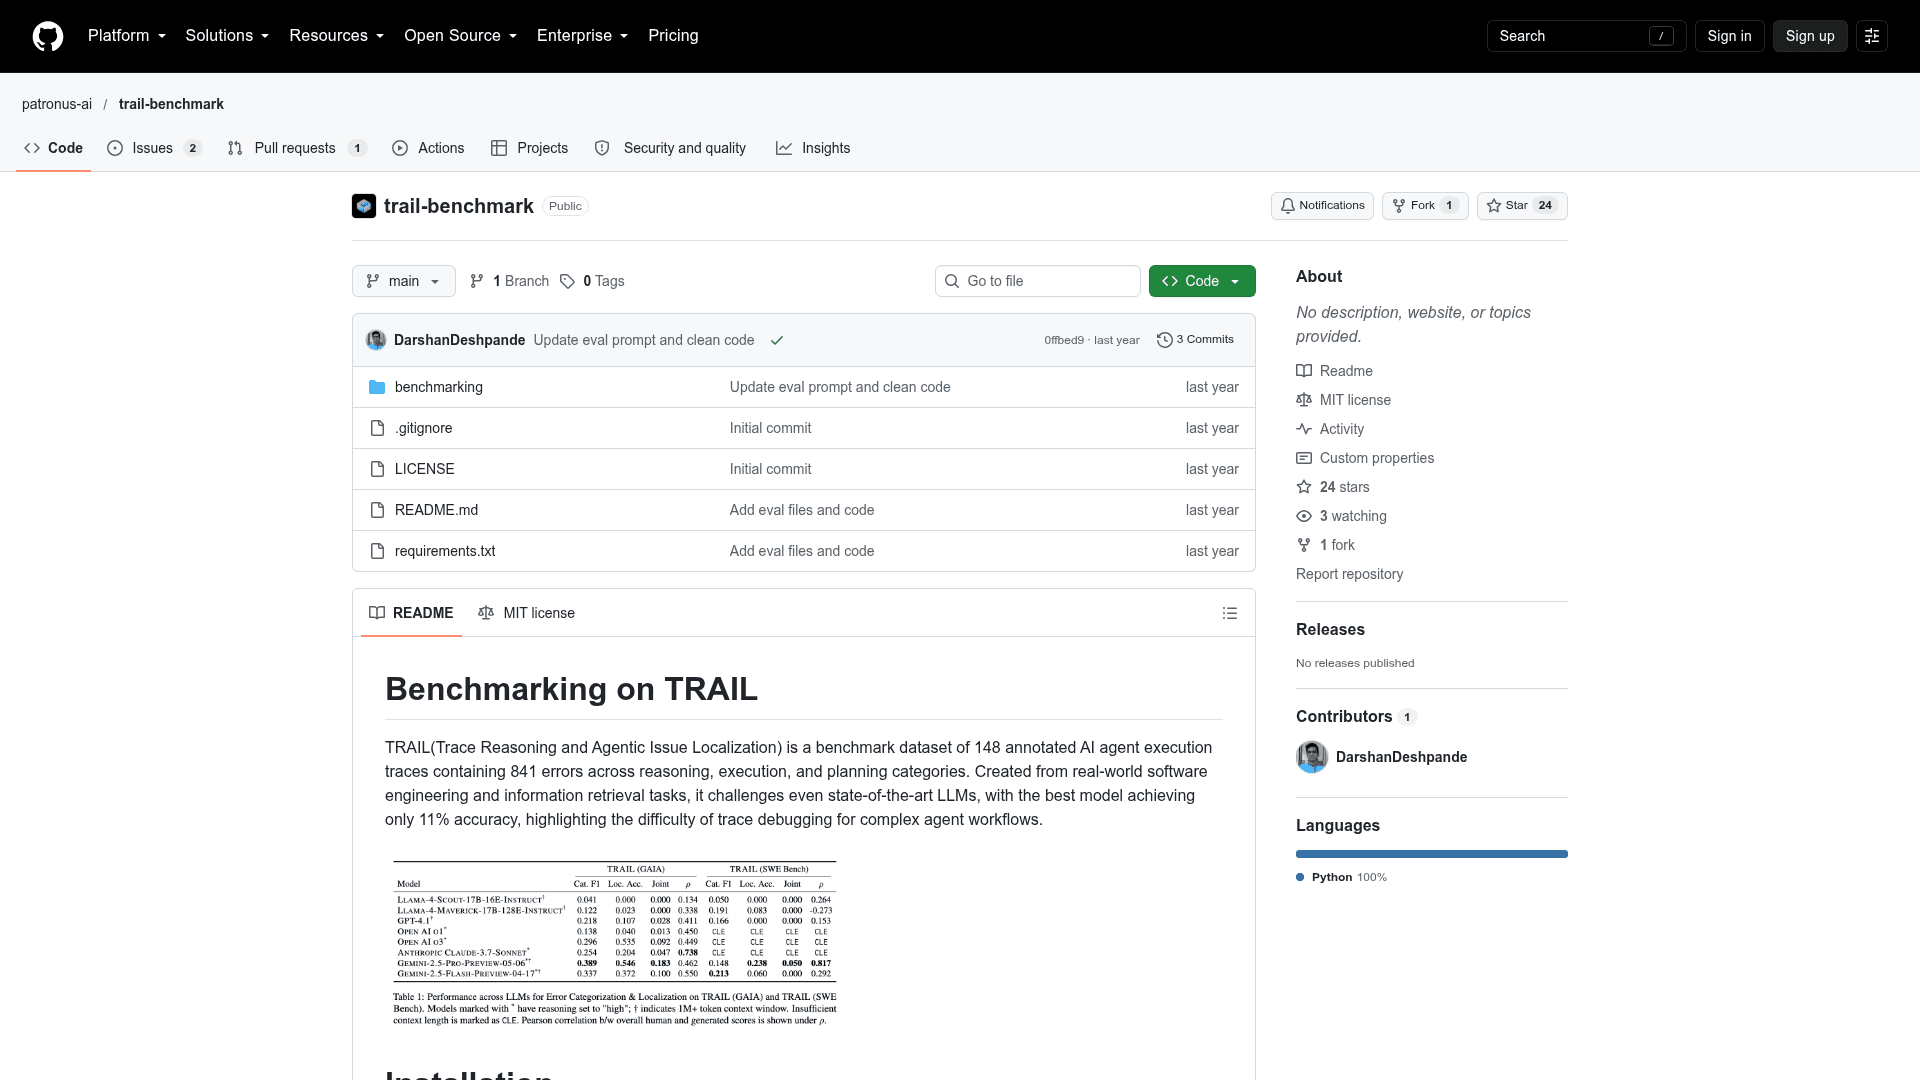
TRAIL (Trace Reasoning and Agentic Issue Localization) is an open-source benchmark from patronus-ai. It provides 148 annotated AI agent execution traces containing 841 errors across reasoning, execution, and planning categories, along with Python scripts to evaluate models on them.
What It Is
TRAIL is a dataset plus evaluation harness for trace debugging of agent workflows. The traces come from real-world software engineering and information retrieval tasks. The README states that the benchmark challenges even state-of-the-art LLMs, with the best model achieving only 11% accuracy.
How the Evaluation Works
After installing dependencies from requirements.txt in a virtual environment, users run run_eval.py with a LiteLLM-compatible model ID, a data directory, an output directory, a worker count, and a split (GAIA or SWE Bench). Evaluation results are written to the results directory. A second script, calculate_scores.py, reads those results and stores a text file with the calculated scores for each model.
Citation and Licensing
The project is released under the MIT License. The README asks users of the code or dataset to cite the accompanying paper, arXiv 2505.08638 (Deshpande et al., 2025).
Community Discussions
Be the first to start a conversation about TRAIL Benchmark
Share your experience with TRAIL Benchmark, ask questions, or help others learn from your insights.
Pricing
Open Source (MIT)
TRAIL benchmark dataset and evaluation code released under the MIT License.
- MIT License
- Benchmark dataset of 148 annotated agent execution traces with 841 errors
- Evaluation scripts run_eval.py and calculate_scores.py
- Running evaluations requires a LiteLLM-compatible model, whose inference costs are external
Capabilities
Key Features
- 148 annotated agent execution traces
- 841 labeled errors across reasoning, execution, and planning categories
- GAIA and SWE Bench splits
- Evaluation script supporting LiteLLM-compatible models
- Parallel evaluation with configurable workers
- Score calculation script producing per-model results
- MIT licensed