
vllm-mlx
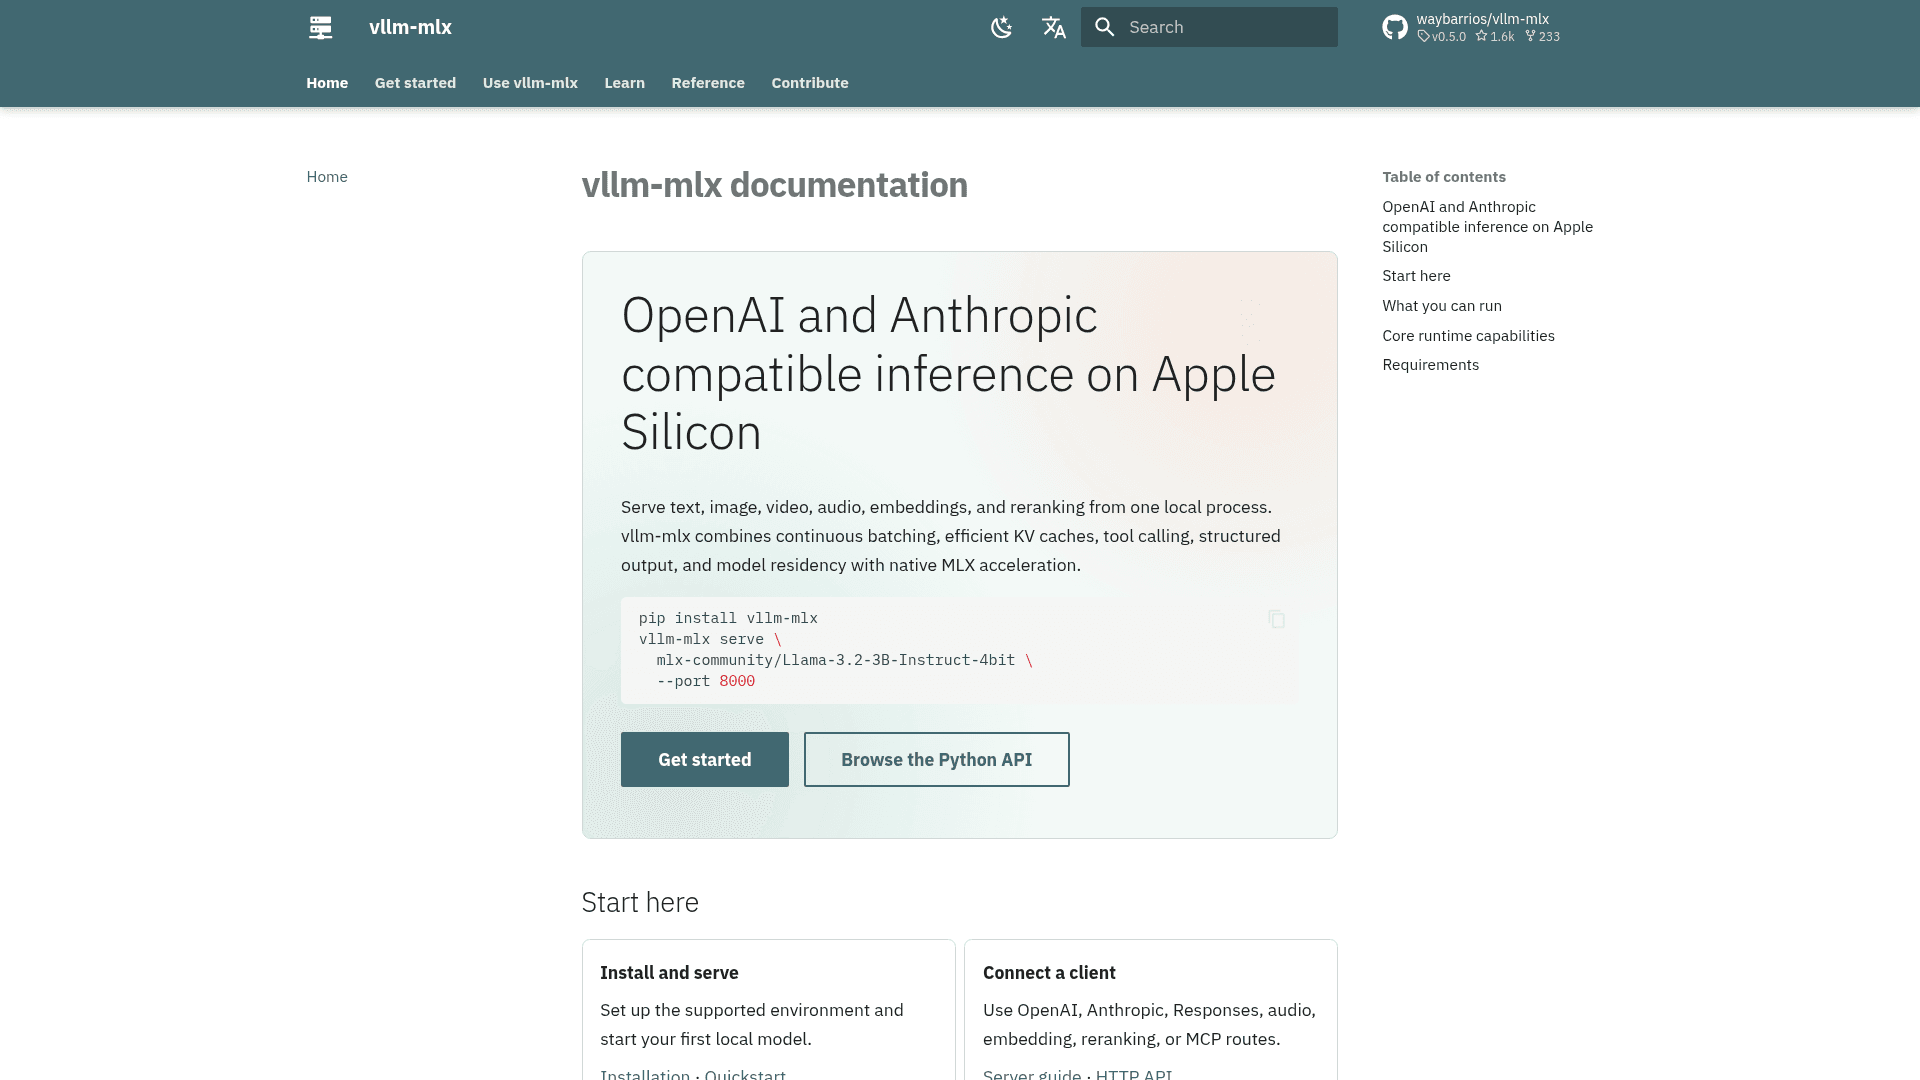
OpenAI and Anthropic compatible LLM inference server for Apple Silicon with continuous batching, built on MLX.
At a Glance
About vllm-mlx
vllm-mlx is an open-source inference server for Apple Silicon Macs, published by waybarrios on GitHub under the Apache 2.0 license. It serves text, vision, audio, embedding, and reranking models from a single local process through OpenAI-style and Anthropic-style HTTP APIs. The latest release listed is v0.5.0.
What It Is
vllm-mlx is a vLLM-style serving layer on top of Apple's MLX framework. You install it with pip, launch vllm-mlx serve with an MLX model, and point existing OpenAI or Anthropic SDK clients at the local endpoint. It runs on Metal with unified memory and needs no model conversion step for MLX-format models.
APIs and Client Compatibility
The server exposes /v1/chat/completions, /v1/completions, /v1/embeddings, /v1/rerank, /v1/responses, and the Anthropic /v1/messages route with streaming and tool use. This lets tools such as Claude Code be pointed at it through ANTHROPIC_BASE_URL. The README reports a validation run with several coding CLIs (OpenCode, pi, Codex, Claude Code, GitHub Copilot CLI, Cline CLI, OpenClaw's embedded agent), and says results apply only to the tested versions and settings.
Throughput, Caching, and Models
The runtime provides continuous batching, a paged KV cache, trie-based prefix caching, an optional SSD-tiered cache, and warm prompts that preload common prefixes. Tool-call parsers (19 according to the README), reasoning parsers, and JSON Schema structured output are included. Multimodal support covers image and video understanding, audio input, text-to-speech, and Whisper-family speech-to-text. Further options include MoE top-k reduction, speculative decoding via MTP, and sparse prefill.
Operations and Tooling
A Prometheus /metrics endpoint, a built-in bench-serve benchmarker with CSV, JSON, or SQLite output, and model inspect, acquire, and convert commands support running and evaluating models. Documentation also includes a Python API and LLM-oriented docs such as llms.txt.
Requirements
The docs list macOS on Apple Silicon, Python 3.10 or newer, and at least 8 GB of unified memory.
Community Discussions
Be the first to start a conversation about vllm-mlx
Share your experience with vllm-mlx, ask questions, or help others learn from your insights.
Pricing
Open Source
Self-hosted vllm-mlx inference server for Apple Silicon, licensed under Apache 2.0.
- Apache License 2.0
- OpenAI and Anthropic compatible APIs
- Continuous batching
- Paged KV cache and SSD-tiered cache
- Multimodal, audio and embeddings support
Capabilities
Key Features
- OpenAI-compatible endpoints (chat, completions, embeddings, rerank, responses)
- Anthropic-compatible /v1/messages API
- Continuous batching
- Paged KV cache and prefix caching
- SSD-tiered KV cache
- Warm prompts
- Multimodal text, image, video, and audio support
- Text-to-speech and speech-to-text
- Reasoning and tool-call parsers
- JSON Schema structured output
- MCP tool calling
- Multi-model registry
- Prometheus metrics
- Built-in bench-serve benchmarker
- Model inspect, acquire, and convert commands
- Speculative decoding and MoE top-k