EveryDev.ai
Subscribe
Home
Tools

5,901+ AI tools

  • Featured
  • Gems
  • Trending
  • New
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2962
  • Coding2238
  • Infrastructure1060
  • Projects817
  • MCP790
  • Research740
  • Analytics561
  • Marketing527
  • Design485
  • Testing473
  • Data442
  • Security408
  • Integration288
  • Communication284
  • Prompts282
  • Extensions238
  • Voice210
  • DevOps189
  • Commerce183
  • Web128
  • Learning122
  • Finance44
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. WebsiteBench
    WebsiteBench icon

    WebsiteBench

    Performance Metrics

    An open-source benchmark that tests whether AI agents can rebuild production-level websites through browser exploration.

    Visit Website

    At a Glance

    Pricing
    Open Source

    Benchmark code, task definitions, and verifier released under Apache-2.0. Reference website content is for non-commercial research only.

    Engagement

    Available On

    Linux
    Web
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    Performance MetricsLLM EvaluationsBrowser Automation

    Alternatives

    WebArenaClawBenchharness-kit
    Developer
    TIGER LabOur lab is currently based in UWaterloo, focusing on Text an…

    Listed Nov 2026

    About WebsiteBench

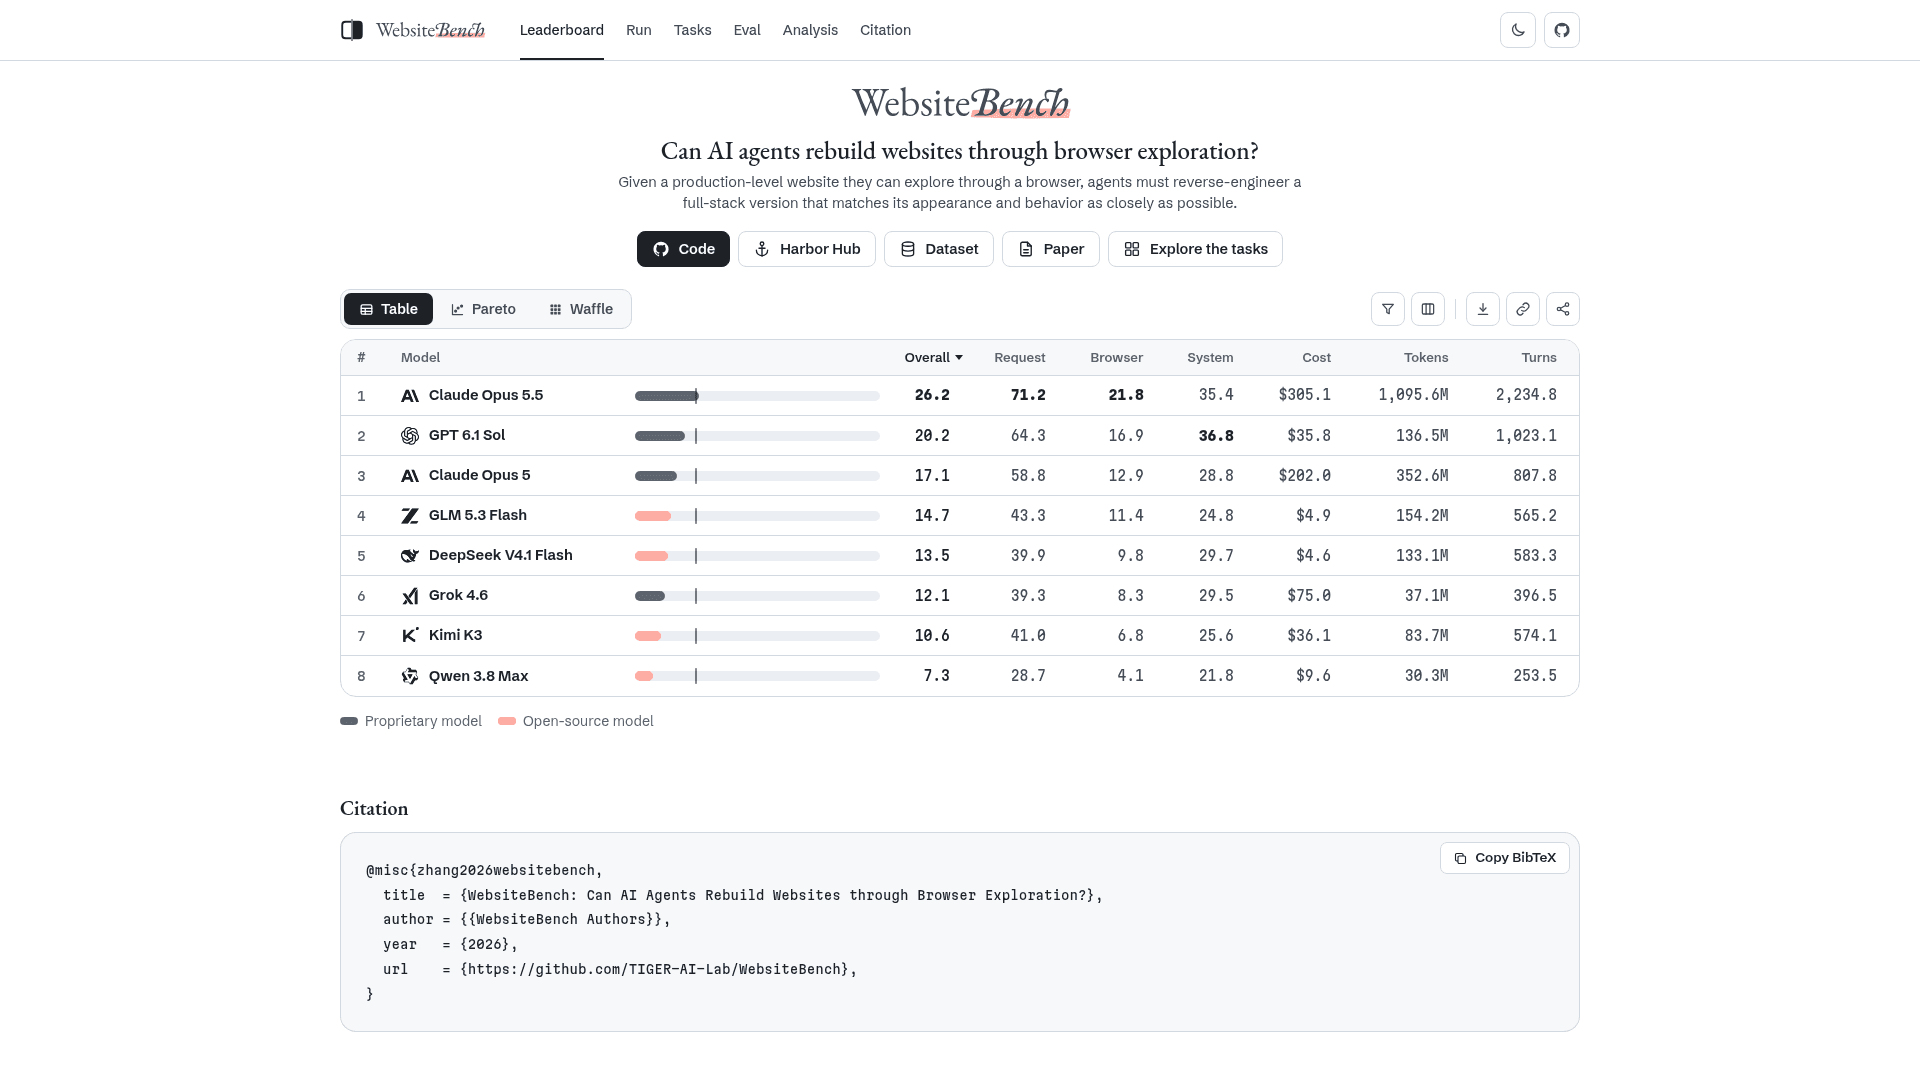
    WebsiteBench is a benchmark from TIGER-AI-Lab that evaluates AI agents on a hard task: given a production-level website they can explore through a browser, they must reverse-engineer a full-stack version that matches its appearance and behavior as closely as possible. It comprises 70 websites and 46,916 hidden test cases, with a public leaderboard comparing eight models.

    What It Is

    WebsiteBench is an agent-evaluation benchmark for website reconstruction. Agents explore a reference site via a browser, then build their own implementation. Tasks are distributed through Harbor Hub and Hugging Face, and can be fetched with the websitebench PyPI package. The code, task definitions, and verifier are released under Apache-2.0, while the reference websites reproduce third-party sites for non-commercial research only.

    How Scoring Works

    Each task has 302 to 2,016 hidden test cases. A case passes when its functional checks pass and every visual checkpoint reaches a normalized SSIM of 0.99. A task's reward is the share of cases that pass. The leaderboard reports overall, request, browser, and system pass rates alongside cost, token use, and turns per task.

    Running the Benchmark

    Users install Docker and the Harbor framework, then run an agent (for example Codex with a chosen model) across all 70 tasks or a single task using the harbor CLI. A reference oracle agent can check a task's reference solution. Each trial's reward is written to a verifier file in the job output directory. The project site also provides pages for tasks, evaluation, and analysis, plus leaderboard views as table, Pareto, and waffle charts with CSV download.

    Data Handling Note

    Task definitions carry a harbor-canary GUID, and the authors ask that documents containing it be excluded from training data.
    WebsiteBench - 1

    Community Discussions

    Be the first to start a conversation about WebsiteBench

    Share your experience with WebsiteBench, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    Benchmark code, task definitions, and verifier released under Apache-2.0. Reference website content is for non-commercial research only.

    • Benchmark code, task definitions, and verifier under Apache-2.0
    • Reference websites' content belongs to its owners and is provided for non-commercial research only
    • 70 websites and 46,916 hidden test cases
    • Model/API costs for running agents are external

    Capabilities

    Key Features

    • 70 website reconstruction tasks with 46,916 hidden test cases
    • Functional and visual scoring using normalized SSIM of 0.99
    • Public leaderboard with overall, request, browser, and system pass rates
    • Cost, token, and turn usage metrics per model
    • Leaderboard CSV, PNG, and SVG export
    • Task download via the websitebench PyPI package
    • Runs through the Harbor framework with Docker
    • Oracle reference solution check per task

    Integrations

    Harbor
    Docker
    Hugging Face
    PyPI

    Ratings & Reviews

    No ratings yet

    Be the first to rate WebsiteBench and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    TIGER Lab

    Our lab is currently based in UWaterloo, focusing on Text and Image Generative Research

    Read more about TIGER Lab
    GitHub
    2 tools in directory

    Similar Tools

    WebArena icon

    WebArena

    A standalone, self-hostable web environment for building and evaluating autonomous web agents on realistic tasks.

    ClawBench icon

    ClawBench

    Open-source benchmark that evaluates AI browser agents on everyday tasks across live websites using HTTP interception and an LLM judge.

    harness-kit icon

    harness-kit

    A Python toolkit for building and evaluating AI agent harnesses, enabling structured testing and benchmarking of LLM-based agents.

    Browse all tools

    Related Topics

    Performance Metrics

    Specialized tools for measuring, evaluating, and optimizing AI model performance across accuracy, speed, resource utilization, and other critical parameters.

    102 tools

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    242 tools

    Browser Automation

    AI-powered agents that autonomously navigate and interact with web applications to automate repetitive tasks, extract data, fill forms, and perform web-based workflows using intelligent understanding of page structure and content.

    203 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions
    2views