wllama
WebAssembly binding for llama.cpp that runs GGUF LLM inference directly in the browser.
At a Glance
wllama, a WebAssembly binding for llama.cpp, is released under the MIT License and can be used for free.
Engagement
Available On
Alternatives
Listed Oct 2026
About wllama
wllama is an open-source WebAssembly binding for llama.cpp, created and maintained by Xuan-Son Nguyen. It lets web applications run GGUF language models directly in the browser, with no backend required, and is distributed as the npm package @wllama/wllama. A hosted demo app is available on Hugging Face Spaces.
What It Is
wllama is a TypeScript library that compiles llama.cpp to WebAssembly so LLM inference can run client-side. Developers load a GGUF model from the Hugging Face hub or from a URL, then call an OpenAI-compatible API to create chat completions or embeddings. Inference runs inside a worker so it does not block UI rendering.
Capabilities
The V3 release adds WebGPU, multimodal (image and audio file input) and tool calling support. With WebGPU, all layers are offloaded to the GPU by default, and the n_gpu_layers parameter can adjust or disable this. The library automatically switches between single-thread and multi-thread builds based on browser support, and has no runtime dependencies. Examples cover completions, embeddings with cosine distance, multimodal completion, tool calling and decision models.
Model Handling and Limits
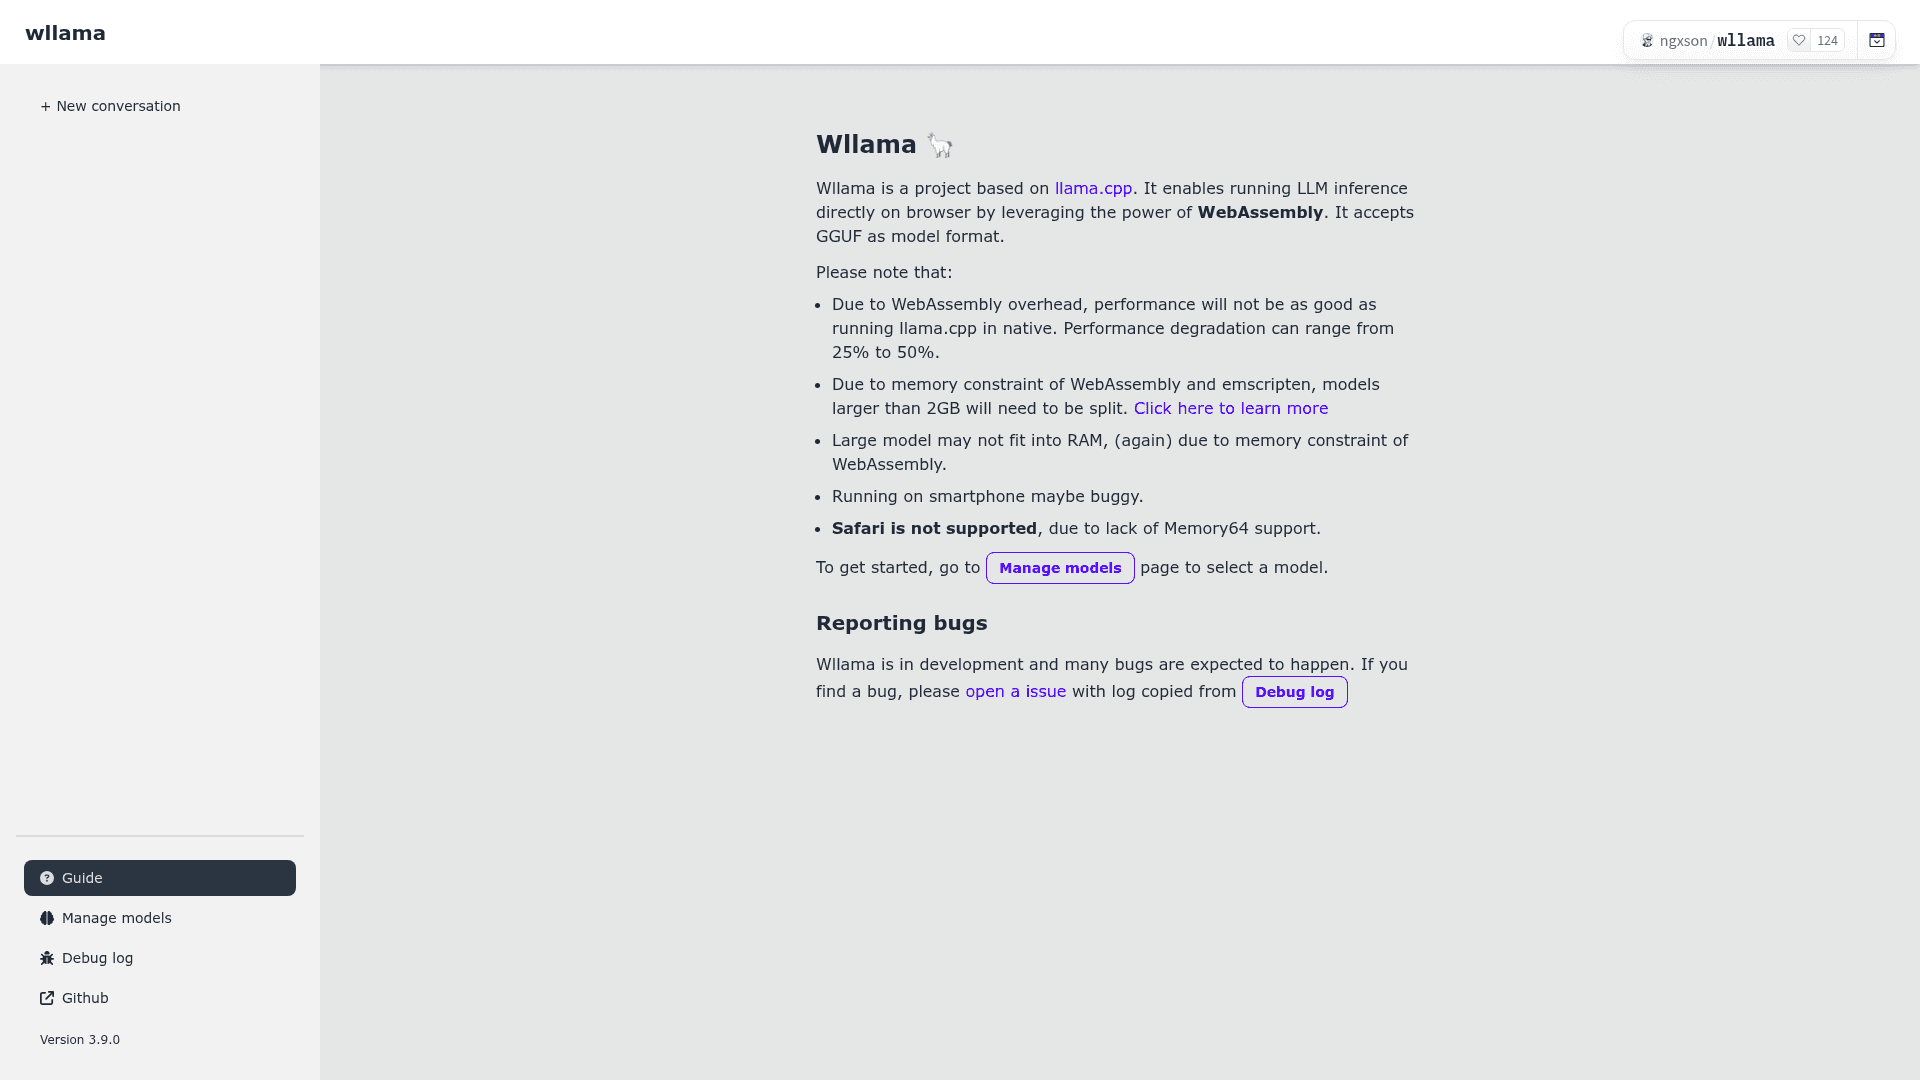
Because of ArrayBuffer size restrictions, files are limited to 2GB, so larger models must be split with llama-gguf-split. Splitting into chunks of up to 512MB also allows parallel downloads. Quantized Q4, Q5 or Q6 models are recommended. The project notes that WebAssembly overhead can reduce performance by 25% to 50% compared with native llama.cpp, that smartphones may be buggy, and that Safari is not supported because it lacks Memory64 support. Multi-threading requires Cross-Origin-Embedder-Policy and Cross-Origin-Opener-Policy headers.
Setup Path
Install with npm, import the Wllama class, point it at the wasm file paths, load a model and request a chat completion. The wasm binaries can also be built from source using Docker.
Community Discussions
Be the first to start a conversation about wllama
Share your experience with wllama, ask questions, or help others learn from your insights.
Pricing
Open Source (MIT)
wllama, a WebAssembly binding for llama.cpp, is released under the MIT License and can be used for free.
- MIT License
- Pre-built npm package @wllama/wllama
- On-browser LLM inference via WebAssembly, no backend or GPU needed
- WebGPU support
- Multimodal support (image and audio file input)
Capabilities
Key Features
- Run LLM inference in the browser via WebAssembly
- OpenAI-compatible fully-typed API
- WebGPU support
- Multimodal support (image and audio input)
- Tool calling
- Embeddings support
- GGUF model loading from Hugging Face or URL
- Model splitting with parallel downloads
- Auto switch between single-thread and multi-thread builds
- Inference runs in a worker without blocking UI
- No runtime dependencies
- Custom logger support