EveryDev.ai
Subscribe
Home
Tools

5,118+ AI tools

  • New
  • Trending
  • Featured
  • Rate tools
  • Compare
  • Arena
Categories
  • Agents2616
  • Coding1923
  • Infrastructure904
  • Projects719
  • Research646
  • MCP613
  • Analytics497
  • Marketing497
  • Design422
  • Testing411
  • Data378
  • Security329
  • Integration259
  • Communication250
  • Prompts247
  • Extensions219
  • Commerce171
  • Voice171
  • DevOps168
  • Web123
  • Learning114
  • Finance35
AI Tools by Topic
  • AI Coding Assistants
  • Agent Frameworks
  • MCP Servers
  • AI Prompt Tools
  • Vibe Coding Tools
  • AI Design Tools
  • AI Database Tools
  • AI Website Builders
  • AI Testing Tools
  • LLM Evaluations
Follow Us
  • X / Twitter
  • LinkedIn
  • Reddit
  • Discord
  • Threads
  • Bluesky
  • Mastodon
  • YouTube
  • GitHub
  • Instagram
Get Started
  • Users
  • Rate Tools
  • About
  • Editorial Standards
  • Corrections & Disclosures
  • Community Guidelines
  • Advertise
  • Contact Us
  • Newsletter
  • Submit a Tool
  • Start a Discussion
  • Write A Blog
  • Share A Build
  • Terms of Service
  • Privacy Policy
Explore with AI
  • ChatGPT
  • Gemini
  • Claude
  • Grok
  • Perplexity
Agent Experience
  • llms.txt
Theme
With AI, Everyone is a Dev. EveryDev.ai ©
    1. Home
    2. Tools
    3. ARC-AGI Benchmarking
    ARC-AGI Benchmarking icon

    ARC-AGI Benchmarking

    Performance Testing
    Featured

    Python harness for running ARC-AGI tasks against multiple LLM provider adapters with rate limiting, retries, and scoring.

    Visit Website

    At a Glance

    Pricing
    Open Source

    MIT-licensed self-hosted benchmarking harness for running ARC-AGI tasks against model adapters; provider API costs are external.

    Engagement

    Available On

    API
    CLI

    Resources

    WebsiteDocsGitHubllms.txt

    Topics

    Performance TestingLLM EvaluationsModel Management

    Alternatives

    FeatherbenchKimi Vendor VerifierEvalScope
    Developer
    ARC Prize FoundationSan Francisco, CAEst. 2024$6370337 raised

    Listed Oct 2026

    About ARC-AGI Benchmarking

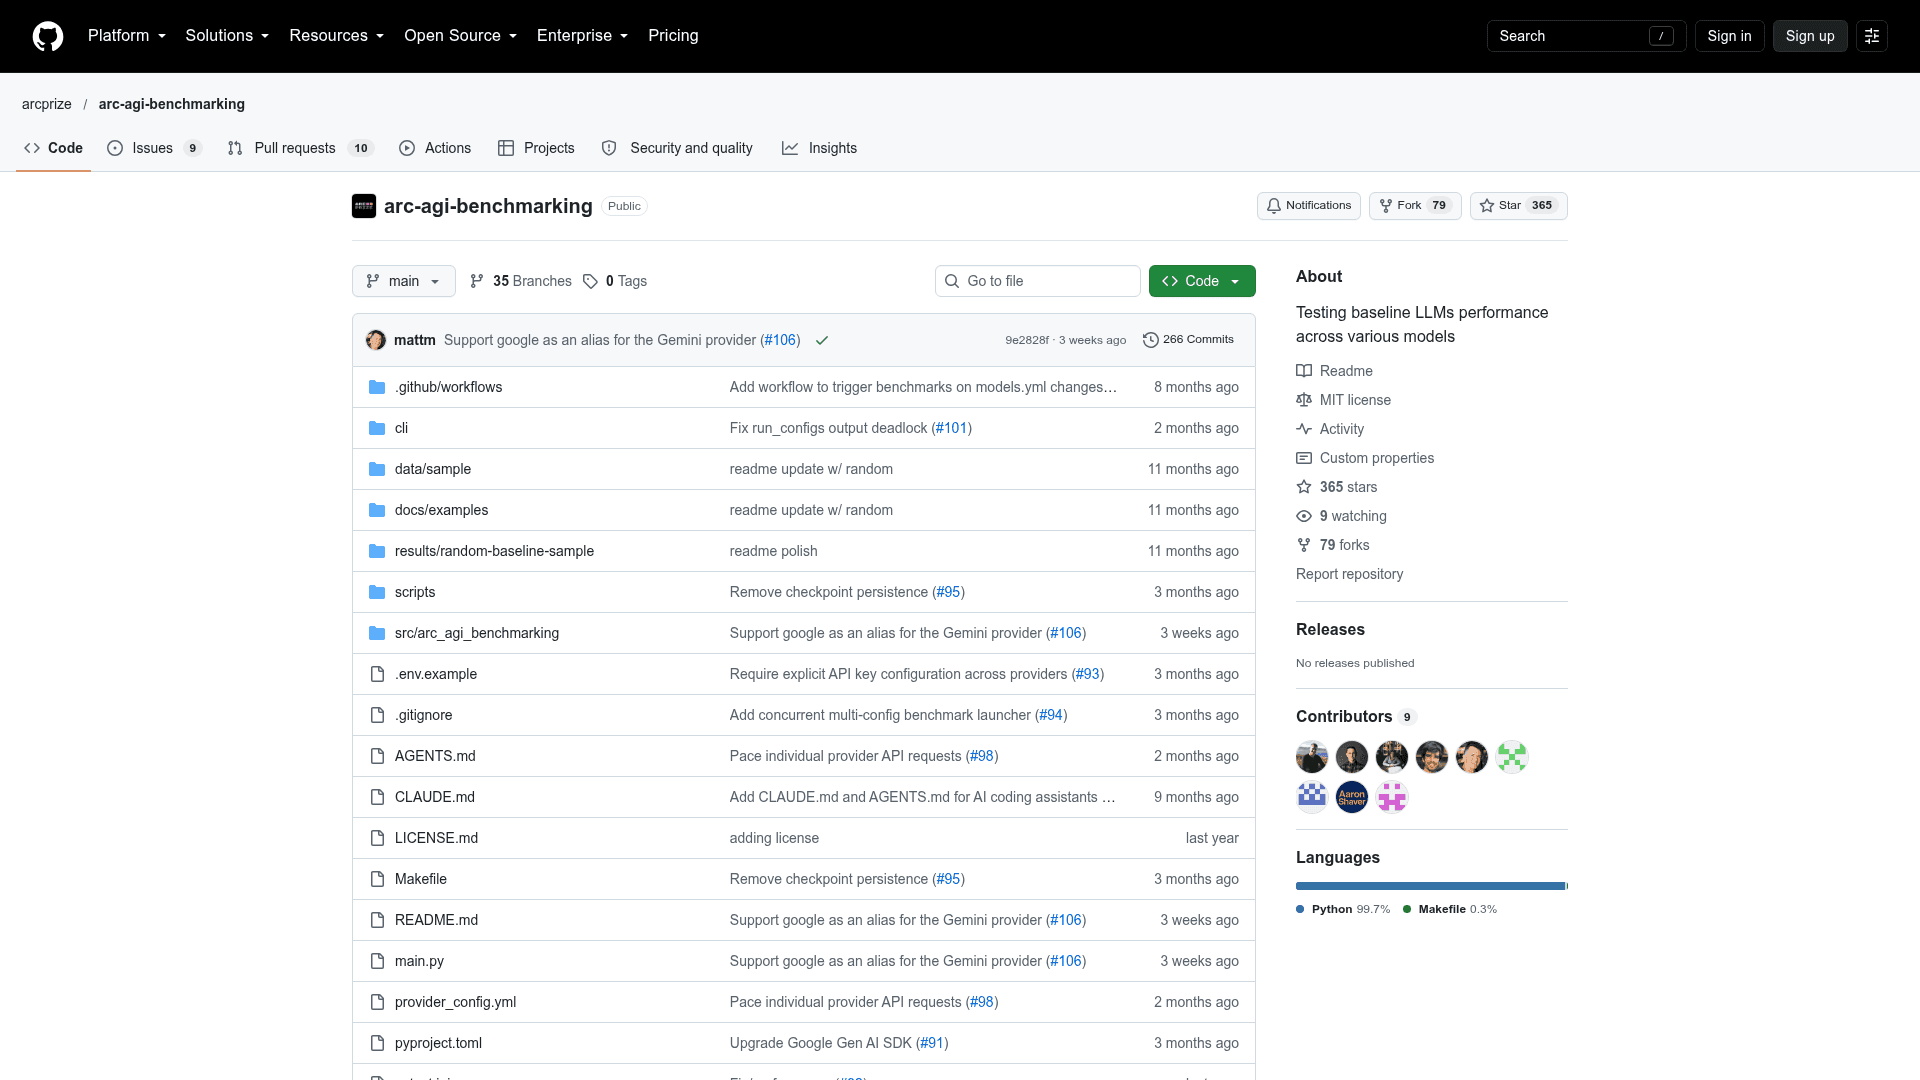
    ARC-AGI Benchmarking is an open-source Python project from the arcprize organization for testing models on ARC-AGI tasks. It runs tasks against model adapters such as OpenAI, Anthropic, Gemini, Fireworks, Grok, OpenRouter and custom providers, with built-in rate limiting, retries, and scoring. It is released under the MIT License.

    What It Is

    The project is a command-line benchmarking harness. Users point it at a folder of ARC task JSON files, choose a model config, and it writes submissions that can then be scored against the source tasks to produce aggregated results. A local random-baseline adapter allows a dry run without API keys.

    How a Run Works

    A single-task command (main.py) supports debugging, while cli/run_all.py runs a batch for one model config using asyncio, request pacing and tenacity retries. cli/run_configs.py launches several configs concurrently across datasets such as v1 and v2 public and semi-private evaluation sets, with provider rate limits shared across child processes and an optional cap on in-flight tasks. Settings include number of attempts, retry attempts, and a maximum number of tasks per run. Outputs land in a structured submissions directory, and the scoring script writes results to a results directory.

    Models, Config and Logging

    Models are defined in models.yml with a config name, provider model id, provider, API key environment variable, optional parameters such as max output tokens and temperature, and per-million-token pricing metadata. Provider rate limits live in provider_config.yml. Raw API request and response events are appended to per-task JSONL logs, which the README notes can contain task data and model reasoning and should be treated as sensitive. New adapters can be added by implementing a ProviderAdapter and registering it.
    ARC-AGI Benchmarking - 1

    Community Discussions

    Be the first to start a conversation about ARC-AGI Benchmarking

    Share your experience with ARC-AGI Benchmarking, ask questions, or help others learn from your insights.

    Pricing

    OPEN SOURCE

    Open Source

    MIT-licensed self-hosted benchmarking harness for running ARC-AGI tasks against model adapters; provider API costs are external.

    • MIT License
    • Adapters for OpenAI, Anthropic, Gemini, Fireworks, Grok, OpenRouter and custom providers
    • Built-in rate limiting, retries, and scoring
    • Local random-baseline adapter requires no API keys

    Capabilities

    Key Features

    • Run ARC-AGI tasks against multiple model provider adapters
    • Built-in rate limiting and retries
    • Scoring of submissions against task solutions
    • Random-baseline adapter for dry runs without API keys
    • Batch runs with asyncio and request pacing
    • Multi-config launcher with shared provider rate limits and concurrency cap
    • Model configs in models.yml with pricing metadata
    • Per-task raw API JSONL logging
    • Optional metrics collection
    • Extensible provider adapters

    Integrations

    OpenAI
    Anthropic
    Gemini
    Fireworks
    Grok
    OpenRouter
    X.AI
    Hugging Face
    API Available
    View Docs

    Ratings & Reviews

    No ratings yet

    Be the first to rate ARC-AGI Benchmarking and help others make informed decisions.

    Rate other tools you’ve used

    Developer

    ARC Prize Foundation

    Home Of ARC Prize Foundation

    Founded 2024
    San Francisco, CA
    $6370337 raised
    4 employees

    Used by

    OpenAI
    Anthropic
    Google DeepMind
    xAI
    +1 more
    Read more about ARC Prize Foundation
    WebsiteGitHubX / Twitter
    1 tool in directory

    Similar Tools

    Featherbench icon

    Featherbench

    A single-file Python harness for building private LLM benchmarks from JSON tasks and comparing models on pass rate, cost and latency via OpenRouter.

    Kimi Vendor Verifier icon

    Kimi Vendor Verifier

    Open-source toolkit from Moonshot AI for verifying third-party inference providers' Kimi model deployments via benchmarks and API conformance tests.

    EvalScope icon

    EvalScope

    Open-source framework for evaluating LLMs, VLMs, agents and AIGC models and stress-testing model serving performance.

    Browse all tools

    Related Topics

    Performance Testing

    AI-enhanced tools for load, stress, and endurance testing that analyze application performance under various conditions with predictive insights and optimization recommendations.

    9 tools

    LLM Evaluations

    Platforms and frameworks for evaluating, testing, and benchmarking LLM systems and AI applications. These tools provide evaluators and evaluation models to score AI outputs, measure hallucinations, assess RAG quality, detect failures, and optimize model performance. Features include automated testing with LLM-as-a-judge metrics, component-level evaluation with tracing, regression testing in CI/CD pipelines, custom evaluator creation, dataset curation, and real-time monitoring of production systems. Teams use these solutions to validate prompt effectiveness, compare models side-by-side, ensure answer correctness and relevance, identify bias and toxicity, prevent PII leakage, and continuously improve AI product quality through experiments, benchmarks, and performance analytics.

    206 tools

    Model Management

    Tools for managing, versioning, and deploying AI models.

    111 tools
    Browse all topics
    Back to all toolsSuggest an edit
    ratings
    discussions